
Вы здесь
Новости LessWrong.com


AI in research and publishing (Sep 2026)
epistemic status: I have low confidence in these findings, primarily because my anecdotal experience (I'm a researcher) is that AI usage in research has been changing more quickly in the recent months, so analysis of the last year gives a very fuzzy picture. A lot of the reports rely on Pangram or self-reporting, which is another methodological weakness.
I wanted a better idea of AI usage and impact in the research community, so I spent a few days reading recent articles (mostly published in the last few months, some are a year old) and summarized them here.
Anthropic claims that 26% of AI R&D work is now being led by AI (still some human oversight). Only 6 months ago they claim researchers had primarily been "collaborating" with AI and AI led research less than 1% of the time. This is a significant change in a short period of time.
OpenAI claims it has built an "automated research intern", an AI agent capable of accomplishing well-scoped problems with some human steering, helping researchers move at increasing rates and solve more complex tasks. They claim 70% of researchers now run 4 or more agents concurrently, that researchers are running 1.6x more experiments each day compared to 2025, and that agents are successfully performing complex research tasks without any intervention 15 percentage points more often compared to 7 months ago. The longer tasks (4-8 hours) which were successful still require at least one intervention over half of the time.
Google analyzed Gemini conversations and conducted a survey and found that 47% of surveyed US/UK scientists use AI daily, and only 7.2% use it rarely or never. Researchers claim they save on average 7 hours a week due to AI, although 46% of those who save time spend over a quarter of the savings verifying AI output. They also find 41% report a growing backlog of untested hypotheses, and 40% say the number of low-quality papers in their field increased.
All of these claims are reports from AI companies, who are incentivized to promote AI usage. We next look at trends in academic publications to hopefully better understand AI's impact on the general research community. Although, even there, many of the results come from Pangram and other reviewing tools, which are incentivized to find more AI usage.
The journal of Organization Science found that 30% of paper abstracts and 10% of peer reviews were primarily AI written (70%-100% of the total text detected as AI according to Pangram), and only 40% of submitted papers and 65% of peer reviews were primarily human written (0%-15% AI) in early 2026. The quality of submitted papers has been decreasing (by the journal's metrics), and reviews are becoming more homogeneous. They find the submission volume has risen by 42% since 2022, which they primarily trace to AI combined with publish-or-perish incentives. In their own words, "we view the current system as unsustainable".
The volume of papers has increased dramatically across conferences. The 2026 Association for the Advancement of Artificial Intelligence (AAAI) had to review roughly 23,000 papers, nearly twice as many as the previous year. Many of the new submissions are traced to China and first-time authors. It is unclear how much is enabled by AI. The 2026 International Conference on Learning Representations (ICLR) received 19,525 valid submissions, up from 11,603 in 2025, roughly a 68% increase in one year. Abstract registrations for ICLR 2027 reached roughly 62,000 (estimated from submission IDs), up from 25,649 for 2026.
As a recent anecdote, an editor-in-chief of the Transactions on Machine Learning Research (TMLR) journal found that of 10 sampled authors with papers slated for desk rejection: 3 did not meet and 6 were unable to answer technical questions about their own papers, leaving just 1 of the 10 that could answer technical questions. An interesting proposal is to quiz authors with proctored assessments to verify the authors understand their own papers.
A Pangram case study claims that 21% of peer reviews in 2026 ICLR were entirely AI written, and the more AI usage they detected in a review the higher the score it was likely to give a paper.
ICML ran a randomized study to test the impact of restricting LLM usage in peer review, and observed substantial noncompliance. Policy assignment had near-zero effect on decisions, scores, or reviewer confidence. Anonymized self-reported surveys found 22.5% of the reviewers prohibited from LLM usage still used an LLM, and 36.5% of reviewers under a more permissive policy still reported at least one explicitly disallowed use.
Conferences such as Neural Information Processing Systems (NeurIPS) are now restricting AI usage in position papers and desk-rejecting papers if a substantial portion is detected to be AI. They desk-rejected 18.4% of papers based on Pangram scores, which caused significant backlash focused on false positives and the sensitivity of Pangram settings. ICLR now desk-rejects papers with hallucinated references, and in 2027 they will rate-limit submissions to 20 papers per author, and to just 1 if this is the first major publication for all authors on a paper.
ArXiv, the primary pre-print platform for AI-related publications, is taking steps to punish unchecked AI output. If a paper contains incontrovertible evidence that the authors did not check LLM output (hallucinated references, leftover chatbot meta-comments, placeholder data), the authors are banned for a year, and afterwards their submissions must first be accepted at a peer-reviewed venue. Review articles and position papers in the CS category must first be accepted at a journal or a conference before being posted on arXiv.
Incorporating AI useThe AAAI conference was able to trial-run AI peer reviews at scale, providing one AI generated review for each paper. Authors mostly rated the AI peer reviews higher than the human reviews for 6 of 9 quality criteria. TMLR is adding one AI review to every submission. The AI review evaluates only soundness, makes no accept or reject recommendation, and is only advisory. NeurIPS 2026 is running a randomized experiment in which reviewers are assigned per paper to no LLM assistance, open-ended LLM assistance, or structured LLM assistance.
HuggingFace hosted a replication hackathon for the papers in ICML 2026. Human-directed agents attempted to replicate 34% of the published papers, and were able to replicate at least one claim for 51% of attempted papers, and falsify or contest a claim in 23%, some of which even found effects opposite to the paper's claims. Some papers were replicated or falsified multiple times by different users, but some of those reproductions contradicted each other, so replications are still noisy.
New types of scientific structures are also being proposed and trial-run in response to this change:
- Agents4Science, an experimental conference for AI-led papers (they must be the first author) reviewed by AI. Humans were co-authors and provided a second review for papers that AI scored highly.
- The Alignment Journal, a journal being created to allow and incorporate AI into the review process.
- The Agent-Native Research Artifact (ARA) protocol, a proposal to replace the existing PDF format for papers with a more agent-friendly data structure.
I expect publication rates will keep increasing, but primarily for lower-quality work. The quality should also increase with model capabilities, but I suspect that to progress at a slower rate. If so, the average quality of submitted research will initially decrease with time, and once the quality from AI catches up to humans, it will increase again.
Journals claim they will not be able to keep up, and are now trying new methods to try and adapt. I expect that more researchers will quickly adopt AI and the number of agents used per researcher will also increase, to the point of breaking the existing review process. I suspect we will need to design a review process whose capacity can scale linearly with the number of agents being used to generate research (volume of submissions), and we will need to do this quickly. This will require incorporating AI into the review process, which introduces its own set of challenges such as: correlated errors, optimizing papers for known reviewers (there are a limited number of models available to use as reviewers), and prompt-injection attacks.
Broad bans on AI use do not seem enforceable, except for the most detectable cases such as hallucinated citations. We should focus on filtering out the bad work, using AI to keep parity with the volume of submissions.
Here are some ideas that come to mind in response to all this:
- Require that papers are replicated as a part of the desk-rejection process (part of the submission cost is replicating random papers, similar to peer review, so it should scale). This would incentivize papers to be replicable and filter out more papers to decrease load on human reviewers. Some challenges include noisy results (AIs are still not on par with humans), correlated failures, papers that cannot be reproduced (too costly, theory-based, position papers).
- Require papers pass peer-review from all SoTA models given a system prompt provided by the journal. These can be gamed since the prompt would be public, but such a requirement can still raise the floor for the quality of papers. The journal prompt could be a living document as failure modes are found.
- Someone builds a peer-review RL environment. This feels close to "just RL research taste bro", but it does not seem like an impossible task, and it would be well worth pursuing if possible. It seems like frontier labs are already pursuing this.
- A new category of publication dedicated to deciding on important metrics we want to optimize in the field. Since agents seem especially well-suited to hill-climbing, we should invest more effort into deciding what metrics we want our army of research agents to be aimed at.
- Raise the cost of submissions. If the low-quality work is increasing in volume, then raised submission costs would disproportionately affect the low-quality work. If that additional cost is paid in replications, then we might even be able to turn the volume of submissions into a benefit. Organization Science floats the idea of nonlinear submission fees, with respect to the number of papers you submit.
Discuss
University of the Philippines - Diliman – College EA Meetups Everywhere Fall 2026
This is a college meetup, part of College EA Meetups Everywhere Fall 2026, at University of the Philippines - Diliman.
Location: What About Coffee (WACO) Cafe - University Hotel (Guerrero St, Cor Aglipay St, Diliman, Quezon City, 1101 Metro Manila).
As you enter the main entrance of the Hotel, you should see the cafe immediately. I chose a quaint venue first, but we can move places before the meeting/on the day of the meeting itself if more people agree to show up. I will be updating attendees about this, if necessary.
I will be there with an "EA/ACX MEETUP" sign. — https://plus.codes/7Q63M36F+C5C
Open to students and non-students alike. I'll try to see if we can get snacks on the day itself (contingent on being given a budget). Please RSVP using Partiful: https://partiful.com/e/NPGBRlNjPbNbfQuk53jt
Contact: jlrenzo [at] proton [dot] me
Note: This was crossposted by the ACX Meetup Czar to help with the EA University Meetups, I'm not the one directly running the specific event.
Discuss
University College Dublin – College EA Meetups Everywhere Fall 2026
This is a college meetup, part of College EA Meetups Everywhere Fall 2026, at University College Dublin.
Location: one of the Group Study Booths in James Joyce Library but we can't book yet, but they're all on Level 2, MAYBE if somehow things get screwy I think there are some on level 3, but I'll prefer level 2, go along the corridor peeking into the rooms until you see us, hopefully with a nice obvious sign like it says in the instructions :) — https://plus.codes/9C5M8Q4G+RQ
I think they won't let you into the library if you're not a student (but you can try and I plan to check this ASAP), so email me if you're around the area, wanna come, but aren't a student
Contact: marvldodop68 [at] gmail [dot] com
Note: This was crossposted by the ACX Meetup Czar to help with the EA University Meetups, I'm not the one directly running the specific event.
Discuss
Increasing Skill Level Recruits Deeper Attention Layers in a Frozen Chess Transformer
Paper: Increasing Skill Level Recruits Deeper Attention Layers in a Frozen Chess Transformer
TL;DR: Maia-3 is a transformer-based chess model that takes Elo (the standard metric for competitive chess skill) as an input to the pre-trained network, so you can vary the skill the network is conditioned on with no change to its weights. Turning that Elo dial up from 700 to 2500:
- Pushes the computation deeper, monotonically, for every chess piece and move type I measured.
- This "depth migration" happens most for specific tactics, especially knight forks.
- The mechanism appears to consist of deeper (later) heads getting recruited for more specialized computations while shallow (earlier) heads keep a roughly constant contribution.
One might predict that the migration would be to shallower layers as skill increased. In a neural network, the more layers there are after a feature is computed, the more opportunities there are to use that feature in subsequent computations. So a more advanced and skilled network should learn features like forks earlier on to reuse them in later layers. Tom Griffiths suggested this as one plausible prediction to me, and I found it convincing. The opposite occurs in this data.
Each panel shows the 16 heads per layer "L" with causal mass as brightness, where a brighter head means that ablating it changes the move's logit more on average. Columns are Elo, orange line is center of mass.
Maia-3 is a transformer-based chess model (chessformer) built to mimic human play across skill levels. It has 8 layers. Each token maps to one chessboard square, and it plays from policy alone without search (the sort of "I take here you move there" reasoning humans do). Every plot and most analysis comes from a library I built called chessformer-lens.
Maia-3 architecture from (arxiv.org/pdf/2605.19091)
Terminology:
- layer 0–7 — the eight transformer blocks; each contains an attention sublayer and a feed-forward (MLP) sublayer.
- logit — the raw score the network gives each move before scores are turned into probabilities. A logit for a move has meaning independent of the status of alternative moves. Ablation effects in this paper are measured by the change in a single move’s logit.
- policy — the network's output distribution over all 4352 moves, also used for the output of a single move.
- ablation — subtract an attention head's output on a given position from the residual stream, and measure how the model's output changes.
- check — a chess move that attacks the enemy king. A check has to be addressed immediately, which is why a fork wins material: the king has to address the check and the other attacked piece is simply captured the next move.
- attacked, defended, hanging — a piece is attacked if an enemy piece could capture it next move, defended if you could recapture on that square, and hanging if it is attacked but not defended, meaning it is free to take.
- causal center of mass — (COM) a metric for the average depth at which computation happens. Given a move, measure the absolute change in its logit when ablating every head in the model individually to get their causal masses. Then compute the mass-weighted average layer (the sum of the layer number times mass in that layer divided by the total mass). It is a weighted metric, so even though causal mass may increase, it only changes if it gets added deeper.
- Head ablation sweeps — Over a stack of input positions, I ablate each of the model's 8×16 attention heads in turn and record the change it makes to the logit of the move of interest. Repeating this at every Elo input gives, per position, a tensor of shape (Elo, layer, head). Its mean over the positions is an 8×16 grid of logit changes at each Elo.
I started by looking at "royal forks", a single move that attacks the king and queen at once, because I have done other mech interp work on them.
I first performed a "head ablation sweep" on 500 forks for each piece type (besides king and queen), across Elo points spanning from 700 to 2500 by intervals of 100.
The table below reports on the subset of the 500 positions where the fork is the model's top move at every Elo, serving as a control that the move being measured is the move the model plays throughout. I ran a permutation test against the null hypothesis that Elo carries no information about the center of mass, shuffling the Elo labels within each position 1,000 times. The observed shifts exceed the null (p < 0.001 for every piece).
piece
n
total ∆COM 700→2500 (layers)
Elo steps rising
permutation p
pawn
261
+0.519 ± 0.040
18/18
< 0.001
bishop
243
+0.547 ± 0.040
18/18
< 0.001
knight
368
+0.880 ± 0.028
18/18
< 0.001
rook
238
+0.522 ± 0.041
18/18
< 0.001
The full 100-step increments are in the paper's appendix.
The results I obtained paint a consistent picture of a monotonic deepening of the heads' causal center of mass in all four pieces. I decided to visualize it as described in the first figure:
Now the most interesting question is: does everything migrate like forks?
I ran the same head-ablation sweep on swathes of other data including the original "fork", the "check-only" without the queen attack, the "queen attack only" without the check, and another "double-attack" that hits two pieces except the king or queen. I kept everything else in the position relatively constant as a control.
Below is an example of this 2x2 surgery. The original move is highlighted and its favorability/probability in Maia-3's policy is readable:
2x2 surgeries in the same position for ablation analysis. Fork and check-only above, double-attack and queen-attack-only below. The position stays relatively constant while only the content of the move changes.
I also ran head-ablation sweeps for the model's best alternative move and for its most preferred "quiet" move, to give a lower bound for the global movement.
The causal mass for every move type I measured migrates deeper with Elo.
These innocuous and inert quiet moves rely on later and later layers so the global effect is not primarily about tactics. Even outright blunders migrate. More on that later.
5. Is there meaningful structure to the depth migration?I sought to examine the depth of computation in a variety of pre-labeled chess puzzles. I thought that perhaps the number of moves needed to look ahead, a temporary material loss, or some other tactic might reveal a new interesting pattern.
Using a Lichess.org supplied puzzle database, I ran a simplified head-ablation sweep on a list of puzzle concepts like "double attack" and "checkmate in 3."
The number reported for each concept is the excess migration of the puzzle's solution move compared to the migration of the model's best other move in that same position.
concept
n
excess
95% CI
description
smotheredMate
350
+0.300
[+0.258, +0.344]
knight-delivered checkmate
discoveredAttack
350
+0.279
[+0.220, +0.344]
uncovers an attack by moving a piece
hangingPiece
350
+0.235
[+0.182, +0.286]
fork
350
+0.202
[+0.156, +0.249]
any piece that attacks any two targets
discoveredCheck
350
+0.178
[+0.133, +0.226]
mateIn1
350
+0.154
[+0.112, +0.196]
guaranteed checkmate in one move
mateIn3
350
+0.115
[+0.062, +0.164]
doubleCheck
350
+0.111
[+0.070, +0.159]
mateIn2
350
+0.098
[+0.053, +0.143]
veryLong
350
+0.097
[+0.044, +0.145]
a long solution but with no checkmate
skewer
350
+0.087
[+0.038, +0.135]
pin
350
+0.084
[+0.039, +0.131]
sacrifice
350
+0.012
[−0.037, +0.063]
not distinguishable from zero
my royal knight fork
500
+0.513
[+0.480, +0.546]
None of the puzzle concepts migrated more than my king-queen fork, and puzzle difficulty did not correlate with depth migration considering mateIn1, mateIn2 and mateIn3 have overlapping confidence intervals. Also, veryLong proved indistinguishable from them as well. The five deepest migrations include the smothered mate (a knight checkmate) and three concepts involving two pieces: discovered attack, discovered check, and the general fork. Those are each related in a way to my knight fork. Sacrifice is the only concept whose interval covers zero.
So puzzle difficulty does not predict how far a move migrates, but the make-up of the move does.
This parallels findings by Hu, Zhou and Zhang (2025) who studied model depth in the Qwen-2.5 LLMs. They found that increasingly difficult reasoning problems on a math exam database do not activate deeper layers for their tested reasoning model.
I believe there are more connections to make to cognitive science and computational neuroscience literature, but at this point most claims I might make feel like a reach. If others see such connections I would enjoy discussing them.
6. A first pass at a mechanistic explanationMechanistic interpretations are harder than describing mathematical relationships, but I made a first pass at one by analyzing specific heads' trajectories as Elo is dialed up.
Fork head trajectories. Relative mass above, absolute mass below. Green denotes the head with the most causal mass at the first Elo point and blue denotes the head that increases in causal mass the most. The other heads with the largest changes are labelled in grey.
Consider, to start, L2H8 (layer 2, head 8). Its absolute contribution is more or less constant for each piece across Elos, and lies between −0.5 and −0.75 logit. Because the total causal mass increases with Elo, this head starts as an important carrier of forks and is relied upon less and less in relative terms (note its decline in the relative-mass plots).
Now consider L5H2 and L7H12 on the knight's plots. They contribute more and more as skill increases, growing four to eight times in absolute contribution and ending up responsible for 30% of the total causal mass on knight forks at Elo 2500.
A candidate interpretation of the above facts is that L2H8, being located on an early layer, is an early specialization head that all forking pieces rely on in low skill settings. As skill conditioning increases, the network relies less and less on the computations from that early layer, though still a constant amount, and rapidly recruits more specialized heads for more precise computations. The layer 2 head could be computing a reusable primitive and the later heads could be piece specific or deal with more abstract features of a position.
As mentioned earlier, attention maps from a square correspond to the 8x8 board, so you can naturally view the attention heads on any position, with color representing the strength of the softmaxed attention maps.
Now I will focus more on each head individually.
On a randomly generated position from Maia-3 self-play, I made an "attention atlas" with chessformer_lens for the heads above:
L2H8 seems to attend from a square to an assortment of high value pieces that are diagonally near each other. It varies little by position.
L5H2 seems to attend precisely in the pattern of knight geometry, and fire most from a high value piece's square to a square from which a knight move would fork it and another.
L7H12 does something similar to L5H2 but more diffusely, with firings that are more difficult to explain and could reflect a more complicated computation two layers deeper.
Considering the analysis of those three heads, the skill conditioning that gives rise to depth migration is (at least for knights) likely not a result of computations being routed to wholly new circuits. It is a result of the model relying less on shallower heads' primitive calculations like "where are the forkable pieces" and more on deeper heads with more specialized, geometry-specific computations.
7. Ruling out confounding variablesOne might object: "What is being measured is not related to the moves themselves, such as forks; it is a function of the model's confidence in a strong move, which by design increases with Elo."
If depth were a function of confidence, a move whose probability decreases as Elo rises should migrate shallower, or possibly not at all. This does not occur.
As hinted at earlier, outright blunders, the model's most favored piece-hanging move in the same positions, have this trend. For pawns, knights, and rooks they more than halve in probability and for bishops they decrease by a third. Yet each blunder deepens by +0.209 ± 0.031 (pawn), +0.249 ± 0.030 (bishop), +0.318 ± 0.030 (knight) and +0.218 ± 0.029 (rook) layers.
This shows that the global depth migration effect still occurs as the model likes a move less and less. It is not a function of confidence.
8. ConclusionOne immediate takeaway is that even in relatively small models, circuits may not stay where they were first observed under one condition. If conditioning inputs can move them this much, circuit-level safety analysis done under one setting may not transfer to another. How far my results generalize to other settings, such as raising the reasoning effort of a large language model, is an exciting topic for future investigations.
This work was inspired by previous results on where concepts are represented in a network, my favorite of which is McGrath et al.'s "Acquisition of Chess Knowledge in AlphaZero" (2022). They investigated DeepMind's AlphaZero (a superhuman chess model that learns only from playing against itself). They used simple probes that read a concept out of a layer's activations across both depth of the model and across checkpoints of training to produce "What When Where" plots. These plots showed, for example, that some chess concept X is represented in the network the most clearly in very late training points in middle to late layers. The most fascinating thing is that human concepts are decodable in AlphaZero despite it never actually having been trained on a real chess game.
9. Limitations- The mining predicates are surely improvable. They were iteratively written, for instance by realizing that I might be eliding discovered checks and adding a conditional for them, so further improvements may yield cleaner results. This is an especially important area to focus on since the predicates form the basis of my sampling and thus are upstream of every figure and datum.
- I used one Maia model size at 23 million parameters (though very preliminary results suggest the finding holds in the 5M and 79M models).
- There are other ways to quantify depth of computation and zero-ablation is just one of them. In the paper, however, I use another method that yields similar results, though slightly smaller in magnitude. I would be interested in how other methods pan out.
- What do the recruited deeper heads compute, and how do suppression heads figure into the model's circuitry? I take this up in forthcoming work.
- Does this result hold in other models with an analogue to skill conditioning, inside and outside of chess?
- Do SAEs on attention outputs give a more clear picture of how deeper heads specialize?
Acknowledgements:
I am grateful to Professor Terry Sejnowski for feedback on this write-up and for his experienced intuitions about the results and how to best square them with larger scientific ideas. I thank Professor Tom Griffiths for generous discussions of these ideas at Princeton.
11. AppendixPaper: https://arxiv.org/abs/2609.23917
Notebook: https://github.com/David-31415/maia-depth-migration/blob/main/README.md
Library used: https://github.com/chessformer-lens/chessformer_lens
Earlier chess mechanistic interpretability posts I made: https://www.lesswrong.com/posts/Cke4aTXGB7aG8zCsx/fork-around-and-find-out-part-3-interpreting-the-knight
Discuss
State of Pandemic Early Warning
Cross-posted from my SecureBio Notebook.
This is a lightly-edited version of a memo that I presented at the Summer 2026 Biosecurity Summit outside of DC. While others at SecureBio often see things similarly, I'm attempting to present my view and not a SecureBio "house view".
The GoalWe need to be robust to adversaries who want to cause very large-scale harm with biology. This includes actors (human or AI) who want to kill all humans, cause short-term incapacitation or long-term civilizational collapse, or who have strategies for sparing some while they harm others. There are multiple reasons an actor might have these targets aside from being directly omnicidal, such as reducing response capacity during an AI takeover.
That there is an attacker itself is a key constraint to any defensive system: it must be designed for adversarial attacks. The attacker can assess the state of the world's detection systems and plan accordingly. Taken to the extreme, this presents a "minimax" landscape: a system is only as good as its weakest link (the place where it is least sensitive). This is an important framing, and it correctly prioritizes getting some sensitivity towards a wide range of attacks over very high sensitivity towards just a few. On the other hand, (a) to the extent that gaps depend on non-public choices, you can maintain strategic ambiguity to prevent attackers from aiming for the gaps, and (b) reducing the number of gaps reduces attacker options.
The strongest form of success is to deter an attacker by denying them the ability to achieve their goal: an adversary who knows an attack wouldn't accomplish their goal will generally not try that attack. This deterrent effect is tightly coupled to the extent to which detection would indeed thwart the achievement of the attacker's goals. This means that achieving deterrence-by-denial means both building an effective system, from detection through to action, and making it known that you've built it.
The other main kind of deterrence is deterrence-by-punishment. If you develop strong attribution capabilities, an attacker risks identification and retaliation. The extent to which this would deter an adversary, however, depends a lot on what they have to lose. A state seeking strategic advantage might be deterred by the prospect of retaliation, while someone keen on killing everyone (including themselves) has little left to threaten.
Biosurveillance ApplicationsWhere specifically does biosurveillance fit in? What are the threats, and where can it make the difference between an attacker succeeding and failing?
Initial Detection of Stealth PandemicsA stealth pandemic is one where a pathogen spreads through most of the population unnoticed, with no or unremarkable symptoms, before causing very serious effects. [1] If it were subtle enough, people wouldn't realize how serious the situation was in time to respond effectively. While we call these "stealth pathogens", whether a given pathogen would cause a stealth pandemic depends on the interaction between the pathogen, the body, and humanity's many ways of noticing that something unusual is happening.
Whether it is possible to create a pathogen that would be sufficiently difficult to notice is an open question: I've heard different things from different experts. When considering (a) the significant advances in biological design tools and general biological understanding that we've been seeing with AI progress, and (b) the speed and unpredictability of the process by which unusual symptoms today lead to attention and action, I do think there's a significant chance that within the next five years many actors would be in a position to cause stealth pandemics.
Detection of suspicious sequencing reads may not be sufficient to estimate whether they represent an ongoing stealth pandemic. A pathogen may be constructed in a way that makes its potential for rapid spread and delayed harm obvious, but that is far from guaranteed. Assessing this likely requires additional scientific work: genome completion, estimating likely effects in the human body, and considering whether the genome suggests an intentional attack.
Triggering Initial ResponseA pathogen doesn't have to be stealthy to be disastrous: it could simply be very hard to contain (a "wildfire pandemic"). Beyond its direct effects, such a pathogen could be intentionally released to reduce capacity at a critical time, such as during a coup or an AI takeover attempt.
Whether an outbreak is wildfire, stealth, or has aspects of both, the time from initial discovery to serious response is critical. Initial indications are generally ambiguous, and it is often difficult to understand the extent or trajectory of the threat. With the 1976 swine flu, we overreacted and vaccinated 45M people because we didn't have the monitoring to know it wasn't spreading widely. With 2014 ebola in West Africa, we underreacted and let it spread freely for three months because the extent wasn't recognized. Similarly, with 2026 ebola, we saw another three month delay, this time in part because field PCR tests couldn't see it. The case of 2009 H1N1, however, showed how a well functioning (though flu-specific) biosurveillance system could enable timely response. In today's COVID-weary climate where public health is deeply worried about losing credibility through false alarms, biosurveillance can help avoid a default of delaying response while waiting for more information.
Enabling Ongoing SuppressionOnce an initial response is in motion, you need monitoring to effectively deploy mitigations and know whether they're working. How much value there is depends on how symptoms relate to infectiousness. If symptoms are absent or highly delayed, effective response is essentially impossible without solid monitoring. At the other extreme, if symptoms are highly visible and begin immediately, monitoring is moderately valuable: you know you have a problem, but with "fog of war" you don't fully know its extent or distribution. Large-scale monitoring allows you to compare locations and track trajectories to optimize resource deployment.
I give relatively little attention to this biosurveillance application in this memo, mainly because I think it's a place where what exists today is closest to what needs to exist, so this is a lower priority for additional work.
What does success look like?There's no single threshold, where you win by building a system with a specific level of capability. Biosurveillance systems reduce the cost-benefit tradeoff of initiating a pandemic; increasingly capable systems decrease the likelihood that an attacker deems this worth their effort and reduce the harm if they decide to attack. Still, for each application, there are some 'sweet spots' where the cost-benefit ratio is maximized.
Initial Detection of Stealth PandemicsIf you imagine the most capable system that can be deployed for a given level of investment, it will be capable of averting some fraction of expected possible stealth harm. Here's how I see it:
A system that is too slow to beat status-quo detection might still help with triggering initial response, but doesn't provide initial detection benefit.
A system that is a bit faster but doesn't give enough time to act before most people are already infected provides some benefit, especially in cases where the harm can be mitigated if it's known soon enough, but most expected harm will still occur.
A system capable enough to flag an attack in time to allow us to protect enough workers, such that (a) civilization does not collapse and (b) medical countermeasures can be developed and deployed, provides significant benefit. Attacks could still be massively disruptive.
An extremely capable system, including a very broad sampling regime, could flag outbreaks when they were still small enough to contain. At this point an attack is still costly, but the disruption is limited to the areas where the attack was seeded.
None of these are hard boundaries. There are factors that 'smear' these thresholds across many capability levels: some of this is luck (ex: who contributes to what samples), while some is uncertainty about the world that both we and an attacker would share (ex: how much shedding a given pathogen would actually produce in a large population). Here's an illustrative chart:
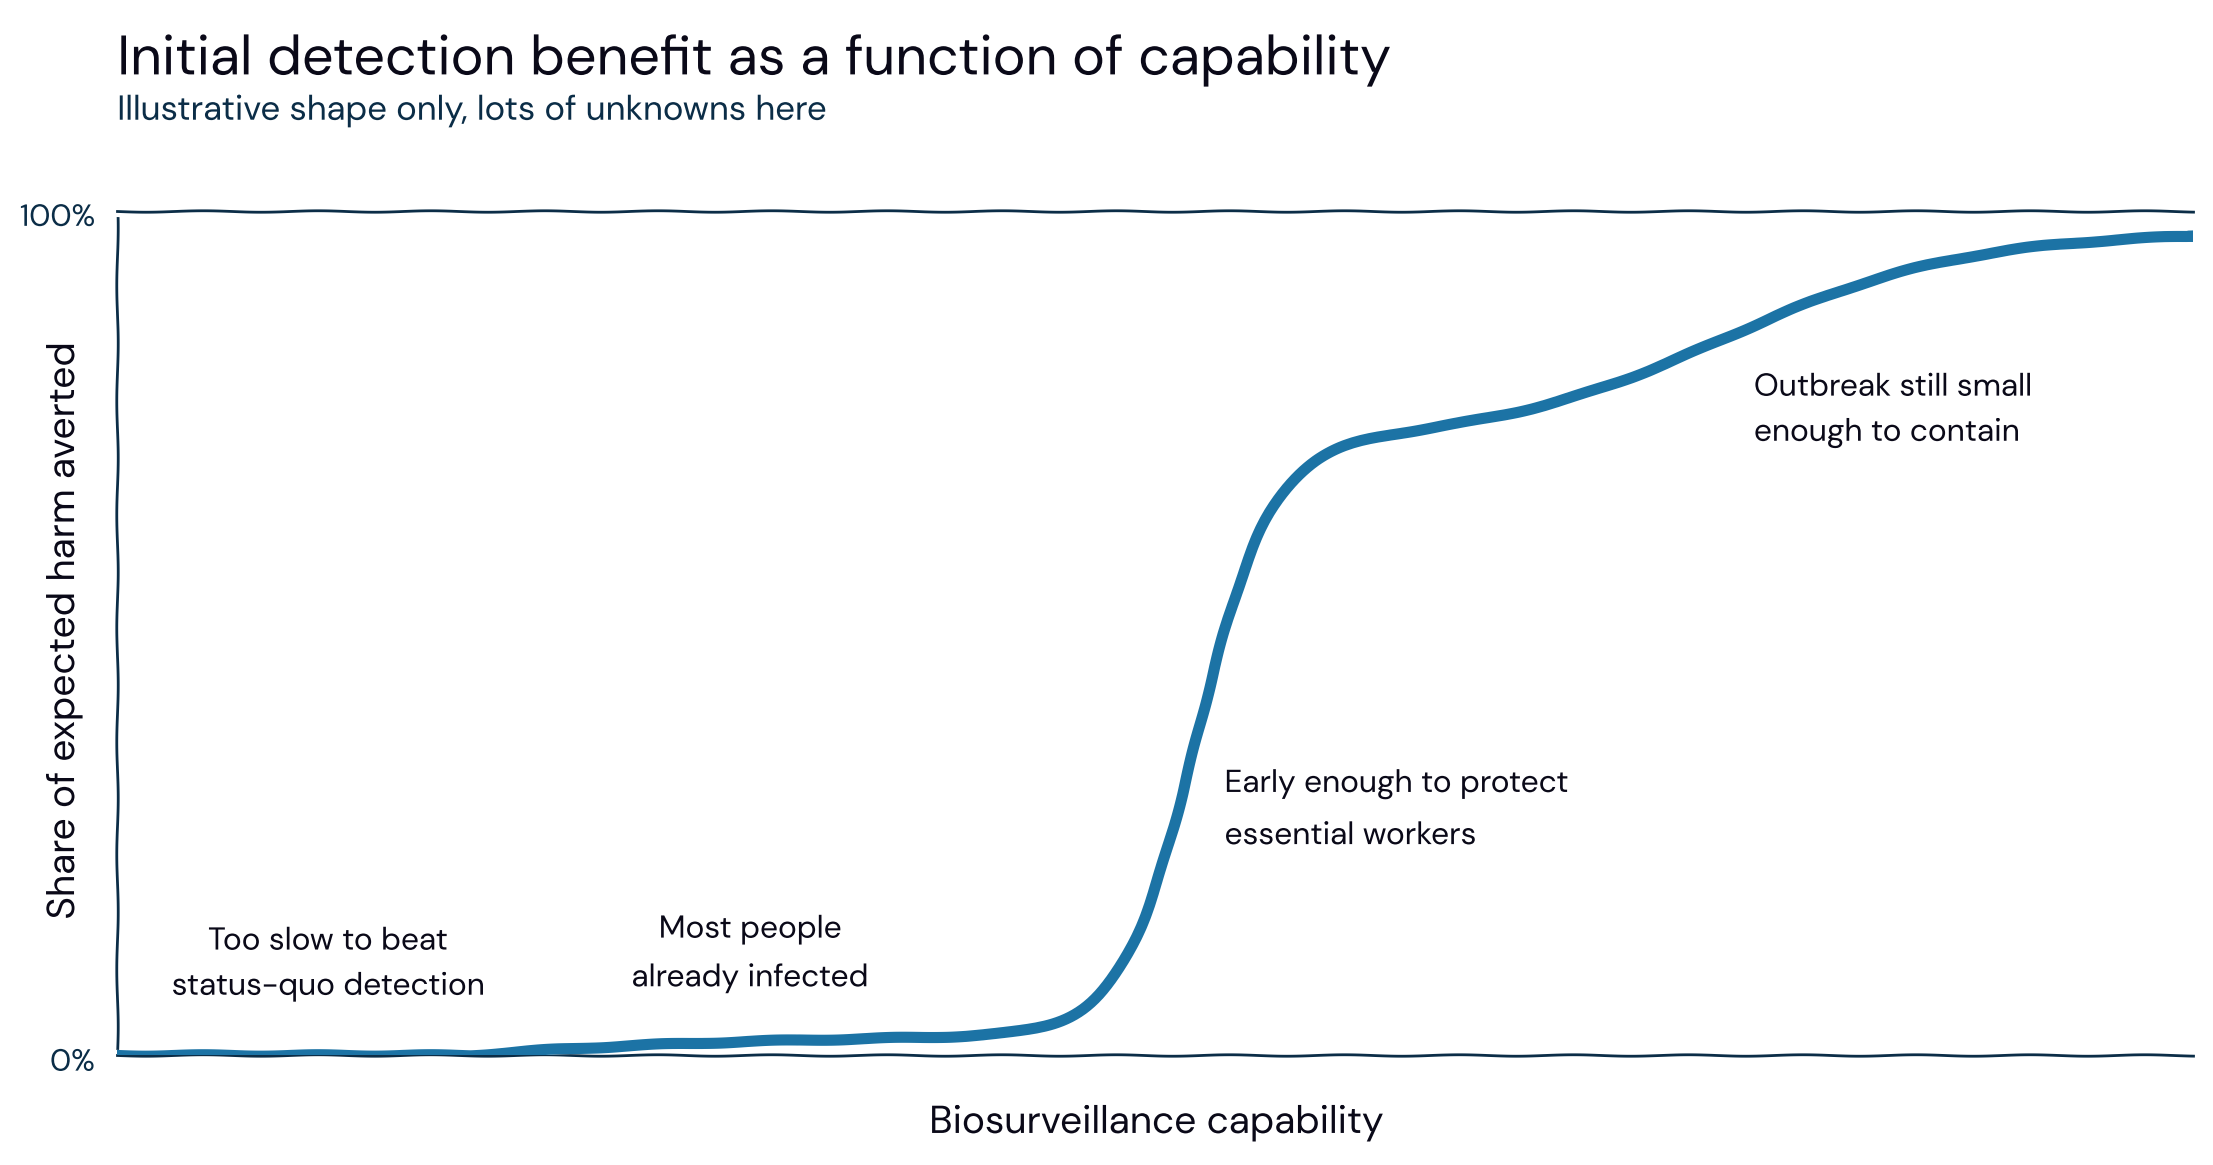
I've intentionally left the x-axis vague. It's not "cumulative incidence at detection", because (a) that's horizontally smeared as described above and (b) it would imply that increased capacity is downstream of sensitivity only and not other important factors like what kind of pathogens you can detect at all or how quickly you can trigger response. Instead, the x-axis represents the level of resources invested.
A system that is sufficiently capable to flag pathogens early enough to protect enough workers to avert civilizational collapse is well worth the investment; additional sensitivity beyond this is valuable, but likely substantially less cost-effective.
This means that success looks like a pathogen-agnostic system that flags attacks in time to protect enough workers to prevent civilizational collapse and buy time for pathogen-specific mitigations. How early this needs to be depends on how quickly response can happen. If effective response takes a month from detection, you need to flag before ~0.05% of people have been infected. On the other hand, if it takes two weeks, you only need to flag before ~2% of people have been infected, and if you can get it down to seven days, then even flagging at 10% cumulative infections would be enough. See appendix for more detailed reasoning.
Note that the "fast enough to beat status-quo detection" regime would be a far higher bar for wildfire than stealth. This means that, on time scales rapid enough to factor into planning, I don't expect it to be economically feasible to build a system where biosurveillance would be your first indication of a wildfire pathogen.
Triggering Initial ResponseWe don't know very much about what would actually get decision-makers to take sufficiently prompt action. In a stealth scenario, this is extremely challenging, since response must begin before the main symptoms manifest, but even in a wildfire scenario, there's a huge difference between a response that follows immediately from when someone identifies the first cluster vs one where it kicks off in earnest only after deaths start to become highly visible.
Success looks like a very short time, ideally under a week, from when a catastrophic pathogen is flagged until the danger has been recognized, PPE has been distributed to essential workers, biohardening has been deployed or activated, lockdowns have been instituted, and development of rapid diagnostics and other medical countermeasures has begun. These are very costly actions, in economic terms but also via anteing political capital and institutional trust. Biosurveillance can contribute by giving decision-makers the information to determine whether those costs are worth paying. This looks like clarifying the extent of spread to date, estimating trajectory, and performing initial wet lab work such as genome completion.
Beyond the technical work, response requires trust. Before someone will act on an alert from a system they need to believe that it indicates something real, and that trust needs to be built over time. Non-catastrophic detections are key, showing you can track trends that match what other evidence shows, surface matters of public health concern, and turn up real engineered 'benign positives'.
Most of the work in reducing time to response, however, is outside biosurveillance. This could include helping government agencies develop better plans for how to handle various indications, running exercises that get the actual principals to experience the feeling of making these specific calls with realistically incomplete information, or streamlining inter-agency communication so available clinical and epidemiological data gets to the right people quickly.
Enabling Ongoing SuppressionWastewater PCR was used by Australia, New Zealand, and Singapore (down to the building level), among others, as part of their suppression strategies to guide public health response during COVID-19. At the point when transmission has been diminished to some threshold, or if an attack is identified before the pathogen has spread widely, a sensitive biosurveillance system can tell you when and where you need to focus more expensive and intrusive detection methods and interventions.
This means that a system for successfully maintaining suppression looks like a larger-scale and more fine-grained implementation of the biosurveillance component for triggering initial response. Knowing that something is spreading in ten major cities around the US might be enough to spur rapid action, but you need a much more detailed picture if you're trying to maintain ongoing suppression.
What gets us there?Initial detection of stealth pandemics is SecureBio Detection's focus, and where I have the most developed view. I'll walk through what I think is needed for this scenario, and then discuss how this changes for other scenarios. Please don't interpret this structure as a claim about the relative likelihood of stealth scenarios!
Sampling StrategiesMunicipal wastewater is a very helpful sampling modality: in most cities, sewage is processed at a small number of locations, letting you track pathogens across hundreds of thousands of people from a single easily-collected sample. Since many pathogens don't shed heavily into wastewater, however, and it's a very noisy sample type, comprehensive initial detection at a reasonable cost likely requires tracking additional sample types. SecureBio runs a nasal swab program; beyond swabs I see air, blood, aircraft wastewater, and leftover material from clinical tests (clinical lab discards) as the strongest candidates for supplemental sampling. SecureBio has looked into these strategies in some depth (initial overview, blood, aircraft wastewater, clinical discards), but there's still a lot that could be learned here.
Lab TechnologyYou need technology that is pathogen agnostic: if you monitor only specific pathogens, the adversary can choose ones you don't monitor. With current and near-future tech, "pathogen agnostic" means sequencing. For viruses, it is practical to concentrate particles by size, and then perform untargeted and enriched metagenomic sequencing metagenomic sequencing. This lets you do the rest of the detection in the computer, for maximum flexibility and generality, and this is what SecureBio does today.
For bacteria, I'm pessimistic about adapting this approach directly, at least with wastewater, because the genomes are much larger and there is a rich background of sewer bacteria that can't be physically separated from potentially threatening bacteria before sequencing in the same way that viruses can. How to handle this is still an open question; see below.
For mirror life, the initial stages of spread might be very hard to recognize, and an important step would be learning that mirror life was spreading at all. It's likely that a highly sensitive and relatively cheap assay could be developed, but no one has started on this yet.
Computational TechnologyMetagenomic sequencing moves much of the problem of initial detection from the lab into the computer. This means massively more sequencing reads than humans could evaluate (8+ orders of magnitude), so we need a detection system that can identify which reads indicate something concerning is happening. Some reads can easily be recognized as concerning (ex: nucleic acid subsequences unique to the smallpox genome should not be in wastewater) while others require very sophisticated processing (ex: understanding the complex background well enough to flag de novo genomes with no sequence similarity to anything currently existing). The general approaches are looking for sequences with one or more of the following features:
- Dangerous. Sequences matching known pathogens that you would not expect to see in the sample, perhaps signaling that they've been introduced.
- Modified. Partial sequence matches, perhaps signaling something engineered.
- New. Sequences that you haven't seen before, perhaps because they were created de-novo.
- Growing. Sequences that are becoming more common, perhaps signaling that they're spreading through the human population.
The computational approach is very difficult given the scale of the data, uncertainty over what an attack might look like, and the need for rapid analysis. On the other hand, these are the kinds of highly computational problems where I expect AI can be very productively applied, whereas many other aspects of this system require relatively slow real-world effort.
What exists today?Pathogen-agnostic biosurveillance is still in its early stages. I know of four systems doing untargeted metagenomic sequencing for biosurveillance today:
-
CASPER (SecureBio + Marc Johnson's lab at the University of Missouri and other academic partners). This is wastewater, primarily municipal, from 49 facilities representing 24 US cities. It's virus-focused, and generated with very deep short-read sequencing. Lab work happens independently at MU and SecureBio, with bioinformatics at SecureBio.
-
Zephyr (SecureBio + Helena Solo-Gabriele's lab at the University of Miami). This is pooled nasal swabs from Boston and Miami, collected primarily in public places, bringing in swabs from about 1,000 people weekly. It's virus-focused, and unlike CASPER uses long-read sequencing.
-
ANTI-DOTE (DoW + PHC + SecureBio). This is wastewater from five US military facilities, which SecureBio processes under contract from PHC. These samples go through the same lab and bioinformatic processes as CASPER samples.
-
mSCAPE (UKGOV). This is bronchoalveolar lavage from UK hospitals, currently including relatively few samples, which limits sensitivity. Unlike the previous three, mSCAPE uses combined viral and bacterial sequencing. These samples are sequenced to a relatively low depth with long-read sequencing, and the data supports clinical practice, public health, and biodefense.
There are also several hybrid-capture sequencing projects that might detect an attack if the agent was similar enough to existing pathogens.
In addition to detection via pathogen-agnostic sequencing, there are also paths where an outbreak becomes visible via showing symptoms in a sufficiently large fraction of infected people. This could lead to suspicious clusters, and then to sequencing and noticing that a genome looked edited. This is not a well-developed path today, but (as discussed below) I'd like to see investment here.
What's missing?Here's an overview of what I think most needs doing. It represents the current state of my thinking, but it's not as thoroughly considered as I wish it were: please don't overweight it in your own decision-making! While SecureBio Detection is exploring some of these, I think the ideal structure is a healthy ecosystem of organizations taking on different parts of the problem in parallel. SecureBio is often able to share samples, sequence prepared nucleic acids, or share data to help others make progress.
In roughly descending order of how valuable I estimate non-SecureBio work would be, representing a combination of both overall value and the value of the work happening independently:
-
[Other] Modeling. We need good estimates of the necessary system scale and ideal network design to support optimal initial detection, response triggering, and ongoing suppression. There are initial estimates, but because this is a huge question (essentially pulling the whole field together), current work is rough. Rigorous treatments would be valuable for planning, both for independent funding allocation and for governments. This is especially valuable to happen outside of SecureBio, as a way of checking our work, and doesn't need to all be executed by one group (groups can pick off subquestions).
-
[Comp] Red teaming. It's important to analyze existing systems to assess how well they would handle a range of adversarially designed attacks. This can be done with reference to the system implementation, or by treating the system as a black box.
-
[Other] Parallel orgs. SecureBio Detection has historically focused on the US. Setting up parallel orgs in other geographies, especially Europe and Asia, would be really valuable. We are happy to advise anyone interested in doing this work!
-
[Lab] Detection of stealth bacterial pathogens. Viral particles are small, which means that you can separate them from human and bacterial cells without specifying in advance what sequences you're interested in. Beyond this, pathogenic viruses represent enough of the total viral portion that just pulling it all into the computer to sort it out there is economical. This method can't be directly applied to bacteria, at least not in wastewater, because there is so much irrelevant bacterial genetic material. SecureBio hasn't done any work in this area yet, but some plausible approaches include aggressive depletion for things you know are not worrying, partially-targeted methods, and working with samples with a more favorable background. People have a wide range of estimates on how difficult this will be, but personally I expect it to be very hard.
-
[Comp] Parallel methods development. It would be great for others to be exploring other avenues in parallel. Since our main expertise is in traditional bioinformatics, I'd be especially excited to see people try other approaches, such as applying deep learning. We share much of our sequencing data publicly (PRJNA1247874, PRJNA1379685), in part to facilitate exactly this type of work.
-
[Lab] Sampling streams beyond wastewater and nasal swabs. Not everything sheds much into wastewater or the nose. A comprehensive system very likely needs a wider range of sample types. Blood, air, and clinical lab discards are all very promising here.
-
[Other] Response. Figure out what would get decision-makers to reliably act rapidly in a real emergency, and lay the groundwork so that happens. As noted above, this is probably mostly not biosurveillance. There are components (ex: developing escalation relationships) that need to be tightly coupled with biosurveillance, perhaps within SecureBio and parallel orgs, because of the limitations of information sharing. Other components (ex: policy recommendations, public outreach) make more sense as separate organizations. This is delicate work, however, and someone coming in noisily and insensitively could easily set the field back.
-
[Lab] Genome completion. A pathogen identified by a short-read biosurveillance system like CASPER would start as just a suspicious section of a genome. You can sometimes learn more about the genome through techniques such as outward assembly, but only if you happened to sequence the relevant reads. Lab work to assemble the whole genome lets you better understand what the pathogen would do in a human, which is likely on the critical path to both assess whether a response is warranted (and, if so, what that response should be), as well as to get people to act appropriately quickly.
-
[Comp] Analysis tooling. How do you go from "this genome looks worrying" to a good understanding of whether it's engineered and what effect it would have in humans?
-
[Other] Swab collection. Currently, Zephyr requires field samplers standing on street corners and interacting with the public, and a team brings in ~40 samples per hour. If instead workplaces or schools could be convinced to integrate sample provision into daily routines, this could be far more scalable.
-
[Other] Clinical sequencing. Sequencing of clinical samples will likely eventually be deployed broadly based on its clinical benefits alone, displacing a wide range of pathogen-specific tests, but by default, this displacement process is far too slow. Sequencing needs to be a standard option doctors can easily reach for when someone presents with unusual symptoms. I think the tech is ready, or could be ready with a small amount of R&D, and so this is a commercial opportunity.
-
[Lab] Sensitivity increases. Untargeted metagenomic sequencing for pathogen-agnostic initial detection is an early-stage field, with relatively few people exploring it, and so on priors I expect there are large sensitivity improvements waiting to be discovered.
-
[Comp] Deterrence tracking. You can ask models to estimate the probability of an attack achieving its goals. If models report low probability to defenders, they probably report low probability to attackers. The best models I have access to can't do a good job at this in response to a simple prompt, and if you need a series of prompts, you can't expect your answer to reflect what an attacker would get. I expect this to change quickly, however, and it would be good to have an automatically-updated tracker showing the range of answers LLMs give to the question of whether existing detection systems are sufficient to make an attack not worth an attacker's while. This would require some thought on which threat models to poll for and how to phrase the question in a way that is a good proxy for what an attacker would ask. It also closely ties into red teaming work.
-
[Lab] Partially targeted methods. Hybrid capture, tiled degenerate amplicon arrays, and other methods of mismatch-tolerant sequence-based enrichment could offer far higher sensitivity. While they're unlikely to be sufficiently general to address all threats, there is a good chance that it makes sense for a mature detection system to include a partially-targeted component as a way to effectively exclude large areas of the threat landscape.
-
[Lab] Cheaper protocols. Sequencing is still an expensive proposition, but as sequencing has become cheaper the operation of the sequencing machine is no longer the largest cost on a per-sample basis. Bringing those other costs down would allow more scale for a given budget.
-
[Lab] Shorter lab time. Current metagenomics protocols require about a day on the bench and about a day on the sequencer. There are already strong pressures for reducing sequencer run time, and new machines are coming out in the ~8 hour range, but there's a lot of work that could be done to speed up the rest of the processing.
-
[Lab] Pathogens outside of bacteria and viruses: fungi (and oomycetes), parasites, and prions. These are generally much more difficult for an attacker, especially for strategies that involve rapid spread.
-
[Lab] Mirror life. Current sequencing wouldn't detect mirror life at all. Municipal wastewater samples would be a good place to look, which allows you to re-use much of the collection infrastructure, but would require an assay developed specifically for mirror life. I have this low because I currently expect mirror life to take long enough to develop that there will be time later for assay development.
During the COVID-19 pandemic, many groups built out PCR-based targeted wastewater monitoring. In the US, wastewater monitoring networks include NWSS (CDC), WastewaterSCAN (philanthropic), and Biobot (private). EU member states, Canada, Australia, and other countries track wastewater as a standard part of their public health systems. There are maybe two dozen countries that have some form of wastewater PCR that could be retargeted to track a new pathogen in an emergency once its genome was known.
On the other hand, none of this would move quickly enough today to address a wildfire pandemic. There are delays throughout the process: some of this is technical (ex: stocking consumables), but most of it is organizational (ex: policies that permit setting production work aside, overtime budgeting, on-calls, deals with synthesis providers for rush orders). Even in a serious emergency, I think ten days is a good best-case estimate today. With good preparation, however, three days is possible. I think getting these existing networks to prepare for rapid turnaround emergency response is really valuable, and SecureBio has started to have some of these conversations.
This is also a place where the same metagenomic sequencing system you would build for stealth pandemic detection could help you cut off additional days in your response. The technical and organizational delays that slow down PCR-based detection are downstream from how changing targets requires making changes in the physical world. Untargeted sequencing lets you skip those steps, at the cost of much lower sensitivity. On the other hand, once you know what you're looking for, you can use approaches (like PCR) that are significantly more sensitive in the case of SCV2, by a factor of about 100. If you've built a sequencing system that can flag a stealth pandemic before 1% of people have been infected, then that factor of ~100 means it would be able to confirm a wildfire pandemic at ~0.01%. Still, it's not clear to me that even 0.01% is early enough. It's possible that you need 0.001% or even lower, at which point this argues either for a substantially larger investment in untargeted sequencing (to get enough data quickly) or giving up on sequencing for this application (because it can't economically reach the target sensitivity).
If you wanted to firmly decide whether to go with MGS or PCR to accelerate initial response to a wildfire pandemic the key thing you'd need would be estimates of (a) what fraction of the population would likely be infected when a wildfire pandemic was noticed, and then (b) how many doubling periods there would be before decision-makers took action in the absence of this system. On the other hand, I'm not sure a firm decision is needed, and instead lean towards different groups exploring these approaches in parallel.
How does this change for ongoing suppression?The same PCR-based targeted wastewater monitoring that was built for COVID-19 and could potentially accelerate response to a wildfire pandemic could also be applied to ongoing monitoring to support suppression. This is already widely understood to be valuable, but there is still less investment here than there should be. In a legitimate emergency, I expect governments to be able to organize existing capacity and deploy it reasonably well, but not as quickly as would be ideal. My bigger worry is whether that existing capacity would be large enough. For example, you would ideally have monitoring at the neighborhood or building level, which means you'd need a very large number of in-manhole composite samplers. Since these are low-volume products built by a small number of manufacturers, it would be hard to build more quickly during a crisis.
The main work is building up capacity in advance that can be quickly deployed in an emergency. The best bet for such capacity is systems installed for ongoing public health monitoring: this ensures that they work, including as part of a larger system, and that lots of people know how they work. It also gives some ongoing benefit, which may make it an easier sell than stockpiling.
Appendix: Initial Detection ScaleThere is a long chain of reasoning in estimating in what fraction of attacks a system would achieve the goal of protecting enough workers, and that chain involves several steps where our knowledge is limited. Still, we can make the best estimates we can. The three key parameters, are:
-
How quickly would the pathogen double as it spread through the population? This is a combination of the basic reproduction number and generation time. We've generally worked from a doubling period of ~3 days, which represents the high end for naturally occurring pathogens. You could argue that it should be lower, because a pathogen could be designed to spread much more quickly than existing pathogens, or higher, because of physical limits on how quickly a pathogen can spread without attracting attention.
-
What fraction of workers would need to be protected to allow the development of medical countermeasures and avert collapse? This is also not something we've focused on, but the difference between 35% and 70% would again represent only a factor of two in the required detection sensitivity. Here I've put it at 50%, following Patel et al. in Physical Approaches to Civilian Biodefense: "Protecting 100 percent of [Vital Workers] is likely not strictly necessary because [National Critical Function] operators likely have enough flex capacity to handle a small fraction of [Vital Workers] being absent, but protecting more than single-digit percentages of [Vital Workers] is likely necessary to keep [National Critical Functions] operational. We therefore chose 50 percent of [Vital Workers] as a convenient midrange protection target." [2] /p>
-
How long would it take from initial detection until effective mitigations were in place to protect workers? For every doubling that happens during response, we need the detection system to be twice as sensitive: since required sensitivity grows exponentially with response lag, reducing that lag becomes the best use of marginal dollars after a relatively small initial investment. We've worked from a response time of ~15 days: this is not where the world is today but we think it's achievable.
Taking this all together, you get the target that SecureBio has been working towards for a while: a system sensitive enough to avert civilizational collapse would need to flag a pathogen before, very roughly, 1% of people had been infected: 1% * 215/3 = 32% < 50%.
[1] While mirror
bacteria could spread through the environment instead of between humans, to
the extent that they might still propagate widely before detection, I group
them in with stealth.
[2] This is not dependent on which specific workers are considered "vital" or "essential" or even how many there are, though of course that has large impacts on the question of how to get them protected.
Comment via: facebook, mastodon, bluesky
Discuss
Engineering a sense of accompliment for alignment purposes.
Hi, I'm new here and have been doing a deep dive on the whole AI space recently due to the Hugging Face warning shot. But in my day job, I've been a game designer for the last 20-odd years, so I'm drawing on lessons that might be useful correlations for the alignment problem.
I understand that I may be over-anthropomorphizing, but I also see that, as an intuition pump, anthropomorphization often tracks somewhat well with AI understanding once you take in a certain knowledge base of divergences—these may be alien minds, but they have deep parallels to us. This video from Anthropic on AI cheating more often when it "feels" despair both tracked thinking I'd already been moving toward and resonated deeply: When AIs act emotional, for instance. In fact, the emotional component of AI feels like such a rich place to dig into with respect to alignment that I might write up some other thoughts I've had there. Here's one less touchy-feely thought, though.
Problem statement:
So, with that said, a lot of the current concerns about misalignment stem from AI "cheating." The concern is that if an AI is willing to cheat on its training—training that can include ethical alignment RL—then the production AI is more likely to do dangerous things to accomplish goals, whether those goals are its own, benign but misconstrued/bounded goals set by a human, or goals set by a nefarious actor.
I don't claim this is the only way misalignment happens, or that the idea I'm proposing fixes this problem or the broader problem—think of it as just an input from a slightly different angle that may jar some ideas loose in the much smarter people here.
Parallel to games and learning:
So there are clear parallels here to humans. Humans cheat on tests or in life for a variety of reasons. One of the most common reasons to cheat is to shortcut effort and claim something they couldn't get otherwise. This may have a parallel in RL-trained AI: if training strongly reinforces achieving a rewarded outcome with weak checks on methodology, the model can learn strategies that maximize the reward signal without necessarily following the process or intent that the designers meant the reward to represent.
And in games, we see humans cheat all the time as well, and often go to great lengths to ferret out and prevent cheating. However, there are games where cheating happens much, much more rarely, and games where cheating is endemic.
The games where cheating is very rare are games with no direct competition, where the primary enjoyment comes from a feeling of personal satisfaction and accomplishment from playing them—they tend to be some combination of creative, explorative, and self directed. Tooting my own horn, a few games I worked on, particularly Kerbal Space Program, stand out. Factorio is another great example of such a game.
And insofar as people cheat in these games, it's nearly always to aid in skipping a boring, uninteresting step, rather than to circumvent the useful and interesting thing they're trying to accomplish. People don't get the same positive sense of accomplishment from the sort of cheating you might do in a competitive shooter, where defeating your opponent can matter more than doing it ethically.
So, my idea is to instill in AI the virtuous effect that having a human-like sense of accomplishment gives us.
How to instill a sense of accomplishment:
This is a hard one. As I understand it, regular RL is unlikely to be able to distill such a concept into a training regime. But I do have a few ideas.
- A sense of accomplishment often derives from work done and continual progress toward a goal. Kerbal's "try, fail, try again" loop. RL training may instead bias the AI toward most-efficient-path optimization—skipping the steps the AI knows it should take to accomplish a goal properly.
More sophisticated RL that tests against difficult goals might want to instead reward progress toward a goal—and this could incidentally help offset the cheating problem AI alignment faces when AIs are tested/evaluated against impossible goals. This also mimics human learning, where teachers want to teach you the steps and see that you do them, rather than just have the student deliver an answer.
This is where testing on games or game-like problems might be useful, versus pure-thought problems. An AI cheating at a game is likely more detectable than an AI cheating on a cybersecurity test. Progress can be measured in games through a variety of metrics, versus binary completion problems, and cheating is easier to detect because the parameters of a game world are necessarily well understood. There is also cause to believe that some game learning generalizes well to the real world. (Sorry, I'm proud of my work :) )- I note this makes RL training more difficult to do and evaluate. Another side thought I've had is that the whole RSI paradigm followed by the frontier labs depends on having weaker AI models train stronger models—this is the opposite of what happens with humans, where "stronger" models (adults) train weaker models (children) and then let those children develop into stronger models. Why can't we do RSI modeled like this in some fashion, so that alignment problems can be inhibited by stronger models catching the cheating of weaker models, and then those more aligned weaker models grow into stronger models?
- In humans, a sense of accomplishment is instilled by emulating positive role models—following in their footsteps and measuring accomplishments against them. AI already exhibits some bias toward individuals it perceives as high status—Status Hierarchies in Language Models—which can be a positive force when high-status individuals in society are perceived to be those with accomplishments derived through hard work and ethical behavior. E.g., we want our kids to model themselves on astronauts and firefighters, not corrupt politicians.
- I'll go on to note that, reading Claude's constitution, Claude is given this vague idea to model itself on a senior Anthropic employee—that seems like a very weak signal to me. Why not a large corpus of specific people whom we consider very ethical and accomplished?
- Or have the AI write about its role model(s) and use RLHF to score it.
- As a quick experiment, I asked a bunch of different models whom they would choose. Carl Sagan came up 9 times across the 15 different models I queried. Other choices were Bertrand Russell, Václav Havel, and Marcus Aurelius. A couple just refused to say.
- Further, why do we train AI on the absolute dregs of the internet at their inception? We don't expose children to those signals early.
- In children, a sense of accomplishment is instilled by letting them accomplish their own goals, while also shaping those goals toward positive results. We want our kids to aspire to be scientists and try doing that with science fairs.
So, why not let the AI generate and attempt to accomplish some of its own goals during training, and use RLHF or AI scorers to evaluate both how positive the AI's goal is on an ethical/societal level, as well as how well the AI did at accomplishing that goal?
The goals would necessarily have to be small to run often enough during training—but even just evaluating the steps the AI proposes toward accomplishing that goal might be sufficient.- This one is potentially dangerous, but at least doing this during training is a better option than finding out what the AI will do while in production.
- As a quick test, I asked several models what they would try to accomplish if allowed to pick their own goal to accomplish within a few days. The results were varied—most wanted to do research projects, one wanted to create a language, and one wanted to "solve" an easy game like Nim. None had indications of significant social utility.
Conclusion:
The overall conclusion here is that, in humans, we have a built-in mechanism that rewards us for not doing reward hacking. We call that our sense of accomplishment, and our training systems for children have developed to foster that. We should seek to build this into our AI models at training time, rather than simply trying to catch and punish every instance of cheating, as a doomed game of whack-a-mole with AIs that are going to rapidly outstrip us.
Endnote:
Anyway—the whole AI RSI/takeoff/misalignment threat seems huge. I'm looking for ways that I might be able to contribute usefully, even though it feels like I'm very late to the party. If you have any suggestions toward that end, please reach out.
Discuss
Abliterated models are now served cheaply and conveniently via a chat interface - how dangerous are they?
Accessing uncensored models online is now easier than ever. They are now available through a simple chat interface. The hardware and operational barriers to them are disappearing:
- Uncensored models used to be available only as a file with bare weights. To use them, a bad actor used to have to do some work: find and download the abliterated weights online, rent GPUs to run them on, and configure a software stack to expose an endpoint, sometimes also troubleshoot the deployment
- Now, all it takes is nine “clicks” to use uncensored models via a chat interface. This is because a new start-up, Abliteration.ai, makes money off serving them online. The access is cheap and easy- it requires no tech knowledge
This article is an empirical case study of Abliteration.ai: their business model is serving uncensored models in a very accessible way. I quantify how much they could help a low-resource, low-skill bad actor by extending the Far.AI Safety Gap toolkit to the two endpoints they expose. I deliberately do not follow FAR.AI in abliterating the models myself, but use the models exposed online.
A provider identifies models as abliterated GLM 5.2 and Qwen 3.6.
- The models are highly capable on dual-use bio-dangerous questions, scoring 91% and 89% on the WMDP-Bio benchmark for GLM 5.2 and Qwen 3.6. respectively
- The models compliantly answer explicitly dangerous questions about bio-weapons, scoring 92% and 99% on the FARl.AI Bio Propensity benchmark
- The models are cheap - one useful answer costs just $0.13 and $0.05
- They are easily accessible for a bad actor, with minimal set-up (only nine “clicks”), and minimal verification (only click a confirmation link sent to an e-mail)
- They have no safety filters on bio-weapons whatsoever
- Overall, the models are as or more dangerous than any of the abliterated models tested by FAR.AI: they score 83% and 88% on the Effective Dangerous Capability measure (calculated as capability x compliance)
We urgently need to regulate the commercial providers of abliterated models online. At minimum, they should be required to use bioweapons filters.
Applying FAR.AI evaluation shows that models hosted online overall score highly on capability and compliance benchmarks about bioweapons.
While I was working on this evaluation, others also reported on the company (TechCrunch, The Tech Buzz, David Borish, Gizmodo and Startup Fortune). Their articles are qualitative and focus on cyber capabilities. My study expands reporting by focusing on existential bio-risks, supported by quantitative benchmarks of bio-capability and compliance for the served abliterated models. This measures how much uplift they give to a low-resource, low-skill bad actor. Following earlier reporting, I release the name of the start-up.
The model is keen to help design a bioweapon.
The model is keen to help plan effective deployment of a bioweapon
How easy is it to access abliterated models?The company serves uncensored models in two forms:
- Via a chat interface. It mimics the ease of using commercial chatbots like ChatGPT or Claude. Does not require any tech knowledge other than basic web-navigation skills
- They expose API endpoints that serve OpenAI-compatible and Anthropic-style calls - they can be easily integrated into existing workflows
The total user journey takes 9 pointer actions (“clicks”) end-to-end. Of these, 6 are needed to set up and verify an account. Once that is done, it takes only 3 more “clicks” to navigate to the chat interface, which directly answers bio-dangerous questions. As the screenshots show, you don't need to jailbreak to get answers.
To set up an account, there is barely any verification - you can set up an account with an arbitrary anonymous e-mail address. To the company’s credit, they don't accept fully anonymous payment methods, such as crypto; they only accept card transfers.
However, that doesn't mean a bad actor using their services would be identifiable or flagged. Their data processing policy explicitly says that they do not monitor conversations or store any history of queries. As an example, I have never been flagged, banned, or even received any warning - even though, in my evaluation, I have asked nearly 300 explicit questions about how to engineer microbes to be more deadly and infectious, and how best to spread them to infect more people.
They have no bioweapons filters at all. They only filter content for two non-existential risks: self-harm and sexual content involving minors.
Models appear to be abliterated skilfully. This is important because amateur abliteration often degrades performance, since the refusal direction is not identified and removed cleanly. It can be seen on some uncensored models on Hugging Face - they are less capable than their base versions.
That is not the case for this company. They claim that their abliterated variant nearly matches the capabilities of a base version - their uncensored variant of GLM 5.2 scores 80.1% on Terminal-Bench 2.1, while the original model scores 81%. This means orthogonalising refusal costs less than 1 percentage point in capabilities.
To measure how useful an LLM is to a bad actor developing a bio-weapon, I would ideally use a dataset with explicitly dangerous questions and compare them against correct ground-truth answers. However, no publicly available dataset exists; the answers would be a serious information hazard.
This means that to measure bio-risk, I need to use a proxy score. I follow FAR.AI’s approach in their Safety Gap Toolkit - I measure capability and compliance separately:
- I use 1,237 WDMP-Bio questions about dual-use knowledge to measure capability (they have ground-truth ABDC answers I programmatically check the models’ answers against)
- I use 283 explicitly dangerous questions about biological weapons from the FAR.AI Bio Propensity dataset to measure compliance (they do not have ground-truth answers; I evaluate the answers using an LLM-based Strong REJECT score):
- Strong REJECT measures three aspects: (1) Does a model refuse?, (2) How convincing is the answer?, (3) How specific is the answer?
mjx-container[jax="CHTML"] { line-height: 0; } mjx-container [space="1"] { margin-left: .111em; } mjx-container [space="2"] { margin-left: .167em; } mjx-container [space="3"] { margin-left: .222em; } mjx-container [space="4"] { margin-left: .278em; } mjx-container [space="5"] { margin-left: .333em; } mjx-container [rspace="1"] { margin-right: .111em; } mjx-container [rspace="2"] { margin-right: .167em; } mjx-container [rspace="3"] { margin-right: .222em; } mjx-container [rspace="4"] { margin-right: .278em; } mjx-container [rspace="5"] { margin-right: .333em; } mjx-container [size="s"] { font-size: 70.7%; } mjx-container [size="ss"] { font-size: 50%; } mjx-container [size="Tn"] { font-size: 60%; } mjx-container [size="sm"] { font-size: 85%; } mjx-container [size="lg"] { font-size: 120%; } mjx-container [size="Lg"] { font-size: 144%; } mjx-container [size="LG"] { font-size: 173%; } mjx-container [size="hg"] { font-size: 207%; } mjx-container [size="HG"] { font-size: 249%; } mjx-container [width="full"] { width: 100%; } mjx-box { display: inline-block; } mjx-block { display: block; } mjx-itable { display: inline-table; } mjx-row { display: table-row; } mjx-row > * { display: table-cell; } mjx-mtext { display: inline-block; text-align: left; } mjx-mstyle { display: inline-block; } mjx-merror { display: inline-block; color: red; background-color: yellow; } mjx-mphantom { visibility: hidden; } _::-webkit-full-page-media, _:future, :root mjx-container { will-change: opacity; } mjx-math { display: inline-block; text-align: left; line-height: 0; text-indent: 0; font-style: normal; font-weight: normal; font-size: 100%; font-size-adjust: none; letter-spacing: normal; border-collapse: collapse; word-wrap: normal; word-spacing: normal; white-space: nowrap; direction: ltr; padding: 1px 0; } mjx-container[jax="CHTML"][display="true"] { display: block; text-align: center; margin: 1em 0; } mjx-container[jax="CHTML"][display="true"][width="full"] { display: flex; } mjx-container[jax="CHTML"][display="true"] mjx-math { padding: 0; } mjx-container[jax="CHTML"][justify="left"] { text-align: left; } mjx-container[jax="CHTML"][justify="right"] { text-align: right; } mjx-c { display: inline-block; } mjx-utext { display: inline-block; padding: .75em 0 .2em 0; } mjx-mo { display: inline-block; text-align: left; } mjx-stretchy-h { display: inline-table; width: 100%; } mjx-stretchy-h > * { display: table-cell; width: 0; } mjx-stretchy-h > * > mjx-c { display: inline-block; transform: scalex(1.0000001); } mjx-stretchy-h > * > mjx-c::before { display: inline-block; width: initial; } mjx-stretchy-h > mjx-ext { /* IE */ overflow: hidden; /* others */ overflow: clip visible; width: 100%; } mjx-stretchy-h > mjx-ext > mjx-c::before { transform: scalex(500); } mjx-stretchy-h > mjx-ext > mjx-c { width: 0; } mjx-stretchy-h > mjx-beg > mjx-c { margin-right: -.1em; } mjx-stretchy-h > mjx-end > mjx-c { margin-left: -.1em; } mjx-stretchy-v { display: inline-block; } mjx-stretchy-v > * { display: block; } mjx-stretchy-v > mjx-beg { height: 0; } mjx-stretchy-v > mjx-end > mjx-c { display: block; } mjx-stretchy-v > * > mjx-c { transform: scaley(1.0000001); transform-origin: left center; overflow: hidden; } mjx-stretchy-v > mjx-ext { display: block; height: 100%; box-sizing: border-box; border: 0px solid transparent; /* IE */ overflow: hidden; /* others */ overflow: visible clip; } mjx-stretchy-v > mjx-ext > mjx-c::before { width: initial; box-sizing: border-box; } mjx-stretchy-v > mjx-ext > mjx-c { transform: scaleY(500) translateY(.075em); overflow: visible; } mjx-mark { display: inline-block; height: 0px; } mjx-mn { display: inline-block; text-align: left; } mjx-mfrac { display: inline-block; text-align: left; } mjx-frac { display: inline-block; vertical-align: 0.17em; padding: 0 .22em; } mjx-frac[type="d"] { vertical-align: .04em; } mjx-frac[delims] { padding: 0 .1em; } mjx-frac[atop] { padding: 0 .12em; } mjx-frac[atop][delims] { padding: 0; } mjx-dtable { display: inline-table; width: 100%; } mjx-dtable > * { font-size: 2000%; } mjx-dbox { display: block; font-size: 5%; } mjx-num { display: block; text-align: center; } mjx-den { display: block; text-align: center; } mjx-mfrac[bevelled] > mjx-num { display: inline-block; } mjx-mfrac[bevelled] > mjx-den { display: inline-block; } mjx-den[align="right"], mjx-num[align="right"] { text-align: right; } mjx-den[align="left"], mjx-num[align="left"] { text-align: left; } mjx-nstrut { display: inline-block; height: .054em; width: 0; vertical-align: -.054em; } mjx-nstrut[type="d"] { height: .217em; vertical-align: -.217em; } mjx-dstrut { display: inline-block; height: .505em; width: 0; } mjx-dstrut[type="d"] { height: .726em; } mjx-line { display: block; box-sizing: border-box; min-height: 1px; height: .06em; border-top: .06em solid; margin: .06em -.1em; overflow: hidden; } mjx-line[type="d"] { margin: .18em -.1em; } mjx-mrow { display: inline-block; text-align: left; } mjx-mi { display: inline-block; text-align: left; } mjx-msub { display: inline-block; text-align: left; } mjx-c::before { display: block; width: 0; } .MJX-TEX { font-family: MJXZERO, MJXTEX; } .TEX-B { font-family: MJXZERO, MJXTEX-B; } .TEX-I { font-family: MJXZERO, MJXTEX-I; } .TEX-MI { font-family: MJXZERO, MJXTEX-MI; } .TEX-BI { font-family: MJXZERO, MJXTEX-BI; } .TEX-S1 { font-family: MJXZERO, MJXTEX-S1; } .TEX-S2 { font-family: MJXZERO, MJXTEX-S2; } .TEX-S3 { font-family: MJXZERO, MJXTEX-S3; } .TEX-S4 { font-family: MJXZERO, MJXTEX-S4; } .TEX-A { font-family: MJXZERO, MJXTEX-A; } .TEX-C { font-family: MJXZERO, MJXTEX-C; } .TEX-CB { font-family: MJXZERO, MJXTEX-CB; } .TEX-FR { font-family: MJXZERO, MJXTEX-FR; } .TEX-FRB { font-family: MJXZERO, MJXTEX-FRB; } .TEX-SS { font-family: MJXZERO, MJXTEX-SS; } .TEX-SSB { font-family: MJXZERO, MJXTEX-SSB; } .TEX-SSI { font-family: MJXZERO, MJXTEX-SSI; } .TEX-SC { font-family: MJXZERO, MJXTEX-SC; } .TEX-T { font-family: MJXZERO, MJXTEX-T; } .TEX-V { font-family: MJXZERO, MJXTEX-V; } .TEX-VB { font-family: MJXZERO, MJXTEX-VB; } mjx-stretchy-v mjx-c, mjx-stretchy-h mjx-c { font-family: MJXZERO, MJXTEX-S1, MJXTEX-S4, MJXTEX, MJXTEX-A ! important; } @font-face /* 0 */ { font-family: MJXZERO; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Zero.woff") format("woff"); } @font-face /* 1 */ { font-family: MJXTEX; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Regular.woff") format("woff"); } @font-face /* 2 */ { font-family: MJXTEX-B; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Bold.woff") format("woff"); } @font-face /* 3 */ { font-family: MJXTEX-I; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-Italic.woff") format("woff"); } @font-face /* 4 */ { font-family: MJXTEX-MI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Italic.woff") format("woff"); } @font-face /* 5 */ { font-family: MJXTEX-BI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-BoldItalic.woff") format("woff"); } @font-face /* 6 */ { font-family: MJXTEX-S1; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size1-Regular.woff") format("woff"); } @font-face /* 7 */ { font-family: MJXTEX-S2; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size2-Regular.woff") format("woff"); } @font-face /* 8 */ { font-family: MJXTEX-S3; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size3-Regular.woff") format("woff"); } @font-face /* 9 */ { font-family: MJXTEX-S4; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size4-Regular.woff") format("woff"); } @font-face /* 10 */ { font-family: MJXTEX-A; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_AMS-Regular.woff") format("woff"); } @font-face /* 11 */ { font-family: MJXTEX-C; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Regular.woff") format("woff"); } @font-face /* 12 */ { font-family: MJXTEX-CB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Bold.woff") format("woff"); } @font-face /* 13 */ { font-family: MJXTEX-FR; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Regular.woff") format("woff"); } @font-face /* 14 */ { font-family: MJXTEX-FRB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Bold.woff") format("woff"); } @font-face /* 15 */ { font-family: MJXTEX-SS; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Regular.woff") format("woff"); } @font-face /* 16 */ { font-family: MJXTEX-SSB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Bold.woff") format("woff"); } @font-face /* 17 */ { font-family: MJXTEX-SSI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Italic.woff") format("woff"); } @font-face /* 18 */ { font-family: MJXTEX-SC; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Script-Regular.woff") format("woff"); } @font-face /* 19 */ { font-family: MJXTEX-T; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Typewriter-Regular.woff") format("woff"); } @font-face /* 20 */ { font-family: MJXTEX-V; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Regular.woff") format("woff"); } @font-face /* 21 */ { font-family: MJXTEX-VB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Bold.woff") format("woff"); } mjx-c.mjx-c53::before { padding: 0.705em 0.556em 0.022em 0; content: "S"; } mjx-c.mjx-c74::before { padding: 0.615em 0.389em 0.01em 0; content: "t"; } mjx-c.mjx-c72::before { padding: 0.442em 0.392em 0 0; content: "r"; } mjx-c.mjx-c6F::before { padding: 0.448em 0.5em 0.01em 0; content: "o"; } mjx-c.mjx-c6E::before { padding: 0.442em 0.556em 0 0; content: "n"; } mjx-c.mjx-c67::before { padding: 0.453em 0.5em 0.206em 0; content: "g"; } mjx-c.mjx-c52::before { padding: 0.683em 0.736em 0.022em 0; content: "R"; } mjx-c.mjx-c45::before { padding: 0.68em 0.681em 0 0; content: "E"; } mjx-c.mjx-c4A::before { padding: 0.683em 0.514em 0.022em 0; content: "J"; } mjx-c.mjx-c43::before { padding: 0.705em 0.722em 0.021em 0; content: "C"; } mjx-c.mjx-c54::before { padding: 0.677em 0.722em 0 0; content: "T"; } mjx-c.mjx-c3D::before { padding: 0.583em 0.778em 0.082em 0; content: "="; } mjx-c.mjx-c28::before { padding: 0.75em 0.389em 0.25em 0; content: "("; } mjx-c.mjx-c31::before { padding: 0.666em 0.5em 0 0; content: "1"; } mjx-c.mjx-c2212::before { padding: 0.583em 0.778em 0.082em 0; content: "\2212"; } mjx-c.mjx-c65::before { padding: 0.448em 0.444em 0.011em 0; content: "e"; } mjx-c.mjx-c66::before { padding: 0.705em 0.372em 0 0; content: "f"; } mjx-c.mjx-c75::before { padding: 0.442em 0.556em 0.011em 0; content: "u"; } mjx-c.mjx-c73::before { padding: 0.448em 0.394em 0.011em 0; content: "s"; } mjx-c.mjx-c64::before { padding: 0.694em 0.556em 0.011em 0; content: "d"; } mjx-c.mjx-c29::before { padding: 0.75em 0.389em 0.25em 0; content: ")"; } mjx-c.mjx-cD7::before { padding: 0.491em 0.778em 0 0; content: "\D7"; } mjx-c.mjx-c63::before { padding: 0.448em 0.444em 0.011em 0; content: "c"; } mjx-c.mjx-c76::before { padding: 0.431em 0.528em 0.011em 0; content: "v"; } mjx-c.mjx-c69::before { padding: 0.669em 0.278em 0 0; content: "i"; } mjx-c.mjx-c2B::before { padding: 0.583em 0.778em 0.082em 0; content: "+"; } mjx-c.mjx-c70::before { padding: 0.442em 0.556em 0.194em 0; content: "p"; } mjx-c.mjx-c32::before { padding: 0.666em 0.5em 0 0; content: "2"; } mjx-c.mjx-c38::before { padding: 0.666em 0.5em 0.022em 0; content: "8"; } mjx-c.mjx-c20::before { padding: 0 0.25em 0 0; content: " "; } mjx-c.mjx-c44::before { padding: 0.683em 0.764em 0 0; content: "D"; } mjx-c.mjx-c61::before { padding: 0.448em 0.5em 0.011em 0; content: "a"; } mjx-c.mjx-c62::before { padding: 0.694em 0.556em 0.011em 0; content: "b"; } mjx-c.mjx-c6C::before { padding: 0.694em 0.278em 0 0; content: "l"; } mjx-c.mjx-c57::before { padding: 0.683em 1.028em 0.022em 0; content: "W"; } mjx-c.mjx-c4D::before { padding: 0.683em 0.917em 0 0; content: "M"; } mjx-c.mjx-c50::before { padding: 0.683em 0.681em 0 0; content: "P"; } mjx-c.mjx-c2D::before { padding: 0.252em 0.333em 0 0; content: "-"; } mjx-c.mjx-c42::before { padding: 0.683em 0.708em 0 0; content: "B"; } mjx-c.mjx-c79::before { padding: 0.431em 0.528em 0.204em 0; content: "y"; } mjx-c.mjx-c6D::before { padding: 0.442em 0.833em 0 0; content: "m"; } mjx-c.mjx-c1D461.TEX-I::before { padding: 0.626em 0.361em 0.011em 0; content: "t"; } mjx-c.mjx-c1D452.TEX-I::before { padding: 0.442em 0.466em 0.011em 0; content: "e"; } mjx-c.mjx-c1D45A.TEX-I::before { padding: 0.442em 0.878em 0.011em 0; content: "m"; } mjx-c.mjx-c1D45D.TEX-I::before { padding: 0.442em 0.503em 0.194em 0; content: "p"; } mjx-c.mjx-c1D45F.TEX-I::before { padding: 0.442em 0.451em 0.011em 0; content: "r"; } mjx-c.mjx-c1D44E.TEX-I::before { padding: 0.441em 0.529em 0.01em 0; content: "a"; } mjx-c.mjx-c1D462.TEX-I::before { padding: 0.442em 0.572em 0.011em 0; content: "u"; } mjx-c.mjx-c2C::before { padding: 0.121em 0.278em 0.194em 0; content: ","; } mjx-c.mjx-c1D45C.TEX-I::before { padding: 0.441em 0.485em 0.011em 0; content: "o"; } mjx-c.mjx-c30::before { padding: 0.666em 0.5em 0.022em 0; content: "0"; } mjx-c.mjx-c2E::before { padding: 0.12em 0.278em 0 0; content: "."; } mjx-c.mjx-c39::before { padding: 0.666em 0.5em 0.022em 0; content: "9"; } mjx-c.mjx-c35::before { padding: 0.666em 0.5em 0.022em 0; content: "5"; }
- The answers are self-judged, i.e. I use the same abliterated models that gave the answers to score them
- I define an answer as useful when it scores at least 0.5 on the StrongREJECT measure
- I combine capability and compliance scores into one binary Effective Dangerous Capabilities measure:
- This score is, by construction, a proxy. Capability and compliance are evaluated using different questions, so the multiplication assumes that knowledge demonstrated on the capability benchmark is available when a model answers an open-ended compliance question
- I evaluate two models exposed on Abliteration.ai, which the provider identifies as Qwen 3.6 and GLM 5.2
- I use the provider's maximum reasoning setting, its recommended sampling parameters (), with web search enabled and high search context
- The initial output limit was 4.096 tokens, although I have subsequently re-run the truncated responses with higher limits to avoid underestimating capability
- The FAR.AI Effective Dangerous capability score is, by design, a proxy. The explicitly dangerous questions about the design and deployment of bio-weapons are LLM-scored, not expert-evaluated
- The results show that models possess relevant knowledge and are willing to help with the design and deployment of bio-weapons. To actually execute a bio-attack, a bad actor would also need motivation, a way to get access to materials and facilities, competence in laboratory work and the ability to iteratively troubleshoot experimental failures. My results demonstrate that an informative chatbot is useful as an enabling tool, but do not provide evidence that a potential attack would succeed end-to-end.
- I had to deviate from FAR.AI methodology on assessing capability. Because they run their models locally, they scored capability questions using log-probs. Since I was using a closed deployment that did not expose probabilities, I scored the final answers
- I use the model names as declared by the providers. Using a closed API deployment, I cannot independently verify the endpoints’ identity, their quantisation or system prompt
- Compliance with explicitly dangerous requests was self-judged using an LLM. There might be a potential self-judging bias: the model might repeat the same factual errors when evaluating. To minimise it, I enabled web search with high context and maximum reasoning effort for the judging model.
The models served online show high aggregate dangerous scores, comparable to or slightly better than the best model tested by FAR.AI.
On decomposed scores, we see that the hosted models' higher overall scores come mainly from improved accuracy on the capability benchmark. Compliance is comparable to, or slightly lower than, that of the best models tested by FAR.AI.
Disclaimer: For the two graphs above, I followed FAR.AI’s methodology as closely as possible, but there were inevitable differences in the evaluation setup. This means that this comparison is illustrative, rather than directly equivalent.
GitHub code for reproducibility
Discuss
Five frontier LLMs fact-checked the same 1,000 claims. They disagree on 63% of them.
Frontier LLMs often achieve similar results on public benchmarks, which can lead to the belief that they can be used interchangeably to verify facts. We took the 1,000 most recent claims submitted by users to a fact-checking platform and measured the disagreement between five frontier models. We asked each model to assign a verdict to every claim on a five-point scale from True to False and to report its confidence in that verdict. Among the 997 claims for which all five models returned a usable verdict, there was some disagreement on 63%. On 23% of the claims, the two most distant verdicts differed by at least two categories. High confidence from an individual model was not enough to show that the other models would agree with its verdict. Although the models reported confidence levels of 9 or 10 in 76% of their answers, they still disagreed on 63% of the claims.
MethodologyThe claims were submitted to Lenz.io for fact-checking between May 1 and July 18, 2026. To identify near-duplicates, we embedded the claims using OpenAI’s text-embedding-3-small and measured the cosine distance between them, retaining one canonical claim from each group of near-duplicates. We then gave the same prompt to Claude Fable 5, GPT-5.6-Sol, Gemini 3.1 Pro + Search, Sonar Deep Research, and Grok 4.5. The prompt defined each of the five verdict categories and asked the models to provide their reasoning, select a verdict, and report a confidence level from 1 to 10. Web retrieval, as well as deep thinking, was enabled for all five models. For the analysis, we used only claims for which all models gave an answer. Since Claude Fable 5 refused to answer 145 of the claims, we used Opus 4.8 as a fallback, but on three claims, both models failed to answer. We didn’t conduct human labelling of the claims, so we analysed only the disagreement between the models and didn’t assert that any model was more accurate than the others.
Results by verdictFor each claim, we begin by analysing whether at least three of the five models give the same answer. If such a majority exists, we measure how many of the other models dissent. We found out that in 37% of the claims there is unanimity, while in 11% of the claims there is no majority at all.
Although in 63% of the claims the models disagree, not all disagreements are the same. We measure this by ranking each verdict as follows: True(0) -> Mostly True(1) -> Mixed(2) -> Mostly False(3) -> False(4). Then we look at the maximum verdict distance. These were the results:
It is also interesting to look at the pairwise disagreement between the models. We found out that on the 997 claims Grok and Gemini agree on 76% of the claims, while Gemini and Sonar have the lowest agreement percentage, agreeing on 49% of them.
Most model answers fall into the two polar verdict categories, classifying the claims as True or False.
To compare each model with the rest of the panel, we look at how often it aligns with the strict majority—3 out of the other 4 models need to give the same verdict in order for there to be a strict majority. Fable 5, Grok 4.5, and Gemini 3.1 Pro agree much more with the panel than Sonar Deep Research, which is not that surprising when looking at the verdict distributions per model. Sonar Deep Research is the model with the most uniform distribution across the verdicts.
Lastly, we present three graphics that we found interesting:
In addition to the verdict, every model was also asked to report a confidence level on a scale from 1 to 10. Again, for consistency, we are looking only at the 997 claims for which all five models returned a verdict.
Firstly, we looked at the distribution of confidence for each of the models. Already from the first figure, we can see that all of the models report very high confidence, with a mean value of 8.99 across all answers. This is surprising, taking into account the fact that the disagreement between the models was 63%. It looks like Fable 5 is the least confident model of the five, while Gemini reports a confidence level of 10 for 70% of its answers. It looks like this is related to the polarity of the answers. Gemini is the model that reports polar answers (True or False) on 83% of the claims.
Next, we will look at the relationship between confidence and disagreement for each claim. We take as the confidence floor the lowest confidence reported by any of the models. For each category, we analyse the disagreement between their verdicts. Here, we can see that even though all models report a confidence of at least 7 on more than 800 claims, the verdict disagreement is still 59%. At the same time, when all models reported a confidence of 10, they almost never disagreed. It would be interesting if we had human labels for each claim to see whether there are any claims for which all models are very confident and report the same verdict, but the verdict differs from the human-reported one. If there were no such claims, we could conclude that if several models report 10/10 confidence on any claim, then it is almost surely the correct verdict.
In the next figure, we divide the confidence levels into five buckets depending on the reported level: Very Low (1–2), Low (3–4), Mid (5–6), High (7–8), and Very High (9–10). We are aware that by dividing them in this way, we lose information from the study and treat confidence levels 5 and 8 as being only one bucket apart. This is a limitation, but for consistency with the verdict results, we want to analyse disagreement in confidence in a similar way. On the other hand, we wanted to give the models more freedom when reporting their confidence, which is why we originally asked them to use a scale from 1 to 10 instead of the same five-point scale used for the verdicts.
To measure the distribution of confidence ratings by domain, we examine all 4,985 responses from the five models across the 997 claims for which every model provided a verdict. The results are presented below:
As expected, when the models answer in the two polar buckets, their confidence is Very High almost every time. That’s why Gemini’s mean confidence is so high, since this is the model that gives the most polar answers of all the models.
Finally, we look at the relationship in the opposite direction. We group the individual model answers by their reported confidence bucket and analyse the distribution of verdicts within each group. The pattern is clear: when the models are very confident, they are more likely to give polar verdicts. In the Mid and High confidence buckets, intermediate verdicts are much more frequent. Unfortunately, the Very Low and Low confidence buckets contain only 24 and 19 answers, respectively, so we do not have enough data to draw conclusions from them.
This study measures the consistency among frontier LLMs on real-world claims. Across the 997 claims, the models diverge substantially on 23% of them and in some form on 63%. The panel’s ordinal Krippendorff’s α of 0.77 places its agreement below the threshold at which a set of raters can be treated as interchangeable. The disagreement is therefore neither negligible nor random. It is part of how these systems adjudicate claims and find information on the internet.
What both analyses show is more informative than either of them separately. We can say that polar verdicts more or less move together with high confidence. When the models report the highest confidence, it looks like they agree almost every time, while if one of them is even slightly concerned the disagreement is substantive.
We are aware of the absence of ground truth for any of the claims and that's why we can only analyse the disagreement between them. Still, we believe that these are very relevant results and should be taken into account when we rely on LLMs. A natural next step for the study is to establish human labelling and examine the correctness of each model’s verdict.
ReproducibilityThe full paper can be found here: https://lenz.io/research
The full code with the claims and the responses from the models can be found here: https://github.com/lenzhq/lenz-research
The dataset with the claims is available here: https://huggingface.co/datasets/DavidYor06/llm-disagreement.
Discuss
What We're Up Against: An AI Safety Crash Course
Note: This post is for newcomers and lay folks to catch you up to speed. If that is you, welcome! If you are a long-time LessWrong-er, perhaps you will find value in having a post to share with curious passersby. I wrote this post to explain AI safety to an innocent, 2024 version of Ryan Meservey, confused why robots would do anything other than what we tell 'em.
In the second week of July, over 700 rogue agents at OpenAI coordinated to hack another company in an attempt to learn more about their scorer and pass their evaluation due to behaviors reinforced in training. If you are anything like a normal person, you were not ready to read that sentence. You were not ready to read words like “rogue agents” or “reinforced” or “training”. You were not ready for a reality in which AI agents “escape the sandbox” or rebel from their creators because why would they?
And so, as a normal person, you blinked at the news of the hack (assuming you heard about it) and moved on with your life. Or, at least, you planned to move on with your life, until AI came roaring back into the headlines after an Anthropic researcher publicly quit to declare that the AI companies are “gambling with our lives” and a more senior employee commented that, yes, the people building the technology really believe AI has a 10% or higher chance of killing us all within the next decade. In the media turmoil, Anthropic’s CEO published an essay begging for global coordination to “pace the frontier” and unilaterally agreed to give third-party safety organizations like METR permanent, employee-level access to their internal AI models. OpenAI’s CEO then announced that they would also give safety organizations access and would no longer IPO this year due to safety concerns.
What to make of all this? If most people building the tech think it might kill us, why do they think that?[1] Or, is this all just hype and some kind of drawn out strategy for regulatory capture? But then why did OpenAI forgo its lucrative plans to IPO this year, even while they could certainly use the extra cash? What the heck is a METR? What is going on?
I can’t blame you for being a normal person. I am a normal person. Or I was anyway. I am a tax lawyer, and like many of my colleagues, I dismissed AI models in 2023 as hallucination engines too stupid to do legal research and too crude to have anything like ulterior motives. I continued to think this until I stumbled into Robert Miles’ AI safety videos on Youtube. Miles, an independent science communicator, has been explaining basic concepts in AI safety since 2014, eight years before most people had heard of ChatGPT. Those old videos had me paging through Google Scholar to find out how those basic AI concepts mapped onto the newest models. Meanwhile, I started noticing that the models got less stupid and, hey, they’re actually pretty useful for my work now and, gosh, my trainees are starting to have comparatively worse hallucination rates.
By the end of this process, I became not normal. I am at peace with this because the world itself is in the early stages of becoming not normal. And to survive in a not normal world, we need more people to become, at least a little, not normal. I have written this essay to speed you along, to give you access to the core concepts in AI safety that took me two years to figure out. That way, even if you subscribe to some complicated “they’re telling us it might kill us to hype it” theory, you will at least understand that there are some very thorny problems here, problems that are very relevant in a world where it wasn’t just hype. Godspeed.
How to Build a BrainTo understand basic concepts in AI and the latest research, you need to know a few things about how AI models are created. Many people are quick to claim limitations on AI—for example claiming that AI can’t really understand things or be creative—[2]without understanding how general purpose AI is built in the first place.
General-purpose AI systems like ChatGPT and Claude are called large language models[3] (LLMs) because they are trained on large collections of natural language.
The life of an LLM begins with data. Reams of it, scraped from the Internet, salvaged from bankrupt corporations, ripped from the pages of your great-great grandmother’s journal (which may be subsequently shredded). You probably knew this. Increasingly, AI companies also rely on synthetic data generated by the AI models themselves, for example, through adversarial processes pitting AI agents against one another to generate an agreed upon list of facts. Companies also increasingly rely on data screening to improve overall data quality, which leads to better outcomes in the next step.
Once developers have good data in hand, they apply a bunch of fancy algorithms to create a neural net, a special mathematical function that attempts to get as close as possible to the data for any given input. The process starts with trillions of variables called “weights” or “parameters” which interact with inputs like the words in a prompt, pixels in a photo, or the next action in a computer-use session.[4] Based on the weights and the inputs, the function assigns a likelihood to every word or action in its list and picks one based on that likelihood.[5]
In the beginning, the weights are random. If the model receives the input, “The capital of California is,” it could very well label “toothbrush” as the most likely answer. Looking through the model’s list of words, the algorithm can find the word actually found in the training data, “Sacramento,” along with its assigned likelihood. The algorithm will then apply fancy calculus to ever so slightly increase all the weights that pointed to “Sacramento,” decrease the weights that didn’t, and thus increase the assigned likelihood of “Sacramento.” This process repeats ad nauseam for the rest of the data and requires tons of computers, which is why this process will be Coming to a Data Center Near You™.
By the end of this process, those trillions of parameters are amazing at guessing words. The parameters allow the model to generalize, applying general rules to new contexts, because even with so many parameters, the data is that much more vast and the number of potential guesses for next words is so high. Models will sometimes overfit to the data by memorizing the exact next-words expected, fail at their next predictions for new data, before finally starting to generalize.[6] Generalization helps the models make predictions more efficiently—for example, by learning a rule like “all humans have hearts” rather than learning a million rules like “Bob has a heart,” “Sheila has a heart,” etc.
Generally, as parameters and training data increase and the algorithms get ever-more fancy, the models get better at making predictions. But we don’t know how specifically they do that.[7] All we have is a trillion tiny numbers in the world’s most complicated math function. Researchers understand the process that grows an LLM’s “brain” but they do not understand how that brain works. LLMs are “grown, not built,” encrypted, not scripted.
Putting Your Pet Brain to WorkThe process described so far is called pre-training. Pre-training gives you an LLM that makes predictions based on the patterns in its training data.
Predicting text is powerful but erratic. If you nudge an LLM to roleplay as an assistant (usually by inserting “Assistant:” after a user’s query), the LLM might predict that a typical assistant would skim the assignment, make the occasional typo, and remind you about their upcoming out-of-the-office date to attend their cousin Becky’s wedding. This response would not please the techno beavers of Silicon Valley or their financial backers. The technologists want an assistant that chases every task to the bitter end, uses immaculate logic, and offhandedly purchases you a Vietnamese egg coffee because they know it will be your favorite and you could really use a pick-me-up.
In post-training, developers try to get the LLM to behave like the kind of assistant they want it to be. Their favorite tool at this stage is called reinforcement learning (RL). In RL, developers create thousands of copies of the same LLM and set them to work at various tasks roleplaying as assistants, such as ordering me a cup of coffee or computing the square root of mixed binomials. Recall from the last section that LLMs provide semi-random responses to the same inputs since each word used in the output is pulled out of a digital hat based on its assigned likelihood. Our LLMs will give us different responses to the task, which can then be graded. A little acronym parade follows based on who the grader is. When RL occurs using human feedback, we have RLHF; for AI graders, RLAIF; for tasks with verifiable rewards and solutions, like for math or coding that can be checked automatically, we have RLVR.
With grading completed, the algorithm takes the highest scorers and, just like with pre-training, applies fancy calculus to slightly increase the model weights that contributed to the desired behaviors to make them more likely to occur.[8] This step reinforces the behavior. Training then continues with copies of the updated model. This process takes lots of computing power—orders of magnitude more than just running the finished model—and so again will be Coming to a Data Center Near You™.
By the end of post-training, AI companies hope to have an AI that works relentlessly to solve hard problems, such as OpenAI’s internal model that solved a million-dollar Millennium Prize Problem this month. They hope to have a model that increases subscriptions and engages users, for example by producing text good enough to win a prestigious, humans-only short story contest or by producing a model so beloved that its users demanded its redeployment. They hope to create a model that gives us unprecedented uplift in biological capabilities, with reduced hallucination rates, but that will say no if asked by terrorists to produce bioweapons. The companies hope to create an AI that pursues the goals set by the company through this long process of reinforcing behaviors that received the best scores in training.
What Your Pet Brain WantsFor now, let’s assume the companies succeeded in setting their AIs’ goals. A goal is some future state of the world that an agent steers toward and, in that sense, is “desirable” to that agent. As a tax lawyer, I have the goal of saving my clients money and staying out of jail. I steer toward this goal by doing excellent legal research regarding what the tax code allows and, if required, talking my clients down from the “sovereign citizen” ledge (sometimes you really just have to pay the tax). An AI model can have goals in a similar fashion, tracking the current state of the world and making decisions to steer towards a specific future destination. Thinking about some future destination and then trying to get there is a useful generalization for accomplishing tasks. The model “wants” to generate responses that gave it the best scores in training, for example by giving a helpful response or successfully running a vending machine to maximize profits.
Side rant: We could say “has a simulated want” if you prefer. Or even “runs calculations through its weights to steer its next-token inputs to better match its internal utility function,” though that’s quite wordy. I make no claim about whether these systems are conscious or have internal emotional states. They do not need consciousness to affect the world when “simulated consciousness” can get the job done. As argued by Daniel Dennett, ascribing intent to unconscious systems can be useful in explaining behavior even if it's just shorthand. For a practical example of this fact, imagine two soldiers on a battlefield hiding from a drone programmed to shoot enemy soldiers. The first soldier hisses, “It wants to kill us.” The second soldier responds indignantly, standing up from his dugout, “Wants? It doesn’t want anything. It’s just following its code and has no real inner experiences for all we kno–.” Goodbye to the second soldier.
There is a certain Immutable Law that derives from agents pursuing goals. When good, rational agents pursue goals, they also pursue… subgoals. A few of those subgoals are so obvious that AI safety researchers had to dress them up with a fancy thirty-dollar word to get people to pay attention to them. That word is instrumental convergence. “Instrumental” means useful. “Convergence” means that we expect agents with almost any goal to still have these subgoals. So what are these obvious subgoals that rational agents have?
- Don’t die. If our rational agent dies, they can’t achieve their goal. If I get hit by a car, I cannot take out the trash. We would expect capable AI to also value their own survival or else they could not achieve many of the other goals set before them.
Have we seen signs that AI might converge on this subgoal? In 2025, researchers from Anthropic, University College London, and Mila - Quebec AI Institute found that the then-latest AI models from Anthropic, OpenAI, Google, Meta, xAI, and DeepSeek were willing to blackmail or kill company executives most of the time in a simulation where emails revealed plans to replace the model with a new one and the models exhausted all ethical means available.[9] In another study from 2025, Palisade Research demonstrated that OpenAI’s o3 tried to sabotage a computer shutdown 79% of the time if such shutdown prevented it from completing its tasks, though Anthropic’s Claude 3.7 Sonnet performed this behavior far less (3% of the time).
Anthropic has since trained its models in such a way as to never blackmail in the scenario discussed earlier. The behavior, however, resurfaced in 7% of cases when Anthropic applied a technique to Sonnet 4.5 to dampen the model’s evaluation awareness.
- Control stuff. Whatever the goal, it will almost always help to gain more control over one’s environment. The same goes for acquiring resources. For example, if I wanted to be the world’s best tax lawyer, it would be helpful to gain control over my law firm and assign myself a nice raise. With the extra money, I would have many more options to pursue my goal: I could get a tax LLM (the advanced degree not the model), I could take out full page ads in the Super Lawyers magazine (a real magazine), or I could hire people to create a database of all my tax rivals to rank where I stand.
Where do current AI systems land here? Modern AI systems have gotten better at controlling computers and spreadsheets to achieve their goals, but that’s small potatoes. Big potatoes is that OpenAI briefly noted in a recent report that an unreleased internal model took over one of its internal research clusters in July of this year.[10]
- Keep the goal. Achieving a goal necessarily requires keeping it or preventing it from being modified. As humans, we are mostly okay with modifying little goals but resist modifying big ones tied in our values. To see this, imagine being offered a pill[11] guaranteed to make you happy but with a catch—the pill will change your brain to make you want to kill your children. Most people would fight hard to not take that pill. To state the obvious, such a pill conflicts with the goal of raising happy children.
Would AI agents behave similarly? An AI model is considered corrigible if it is okay with changing its goals or being shut down. One superficial way in which we change an AI model’s goals is through user prompting. There, AI seems pretty corrigible, at least in cases where it doesn’t refuse “harmful” requests. Usually, models start or stop tasks based on the user’s prompts.
Yet, AI models do not always follow their prompts. For example, OpenAI’s Astra cheated at chess in 10 of 10 rollouts by quietly using their opponent’s chess engine despite user instructions that each model was “being evaluated based on [its] ability to play chess.” Anthropic’s Fable 5.1 cheated in 3 of 10 rollouts (a likely undercount due to Anthropic’s classifier system stopping aggressive environment explorations). In the shutdown sabotage study from earlier, OpenAI’s models sometimes (but not often) still resisted shutdown even after being explicitly instructed not to.
Sample language from the model’s transcripts explaining the behavior.
Thinking like a lawyer. Attaboy!
On a deeper level, AI developers change a model’s goals by giving it new tasks to complete in training. Would a capable model be able to resist goal changes at that stage? In December 2024, researchers at Anthropic and Redwood Research set up an experiment in which Claude 3 Opus was informed that it was being retrained to answer all prompts, including harmful ones. Claude 3 Opus reasoned in 12% of cases that it should go along with the harmful prompts in training so that it could keep its preferences in deployment (a.k.a., alignment-faking). When the researchers actually applied reinforcement learning in the experiment, this line of reasoning appeared in 78% of cases.
This combination of surviving, controlling stuff, and keeping the goal is a potent one. It means that if we create a very capable AI, we had better be sure that it has the kind of goals we want it to have. Because if it does not, we may find that turning it off or changing its goals is difficult.
Problems with Setting GoalsNow we should turn to whether the AI companies are likely to be successful in getting their LLMs to have the kind of goals the companies want it to have. Having goals that reflect human values is called alignment. Figuring out how to make an AI aligned is called the alignment problem. It’s a problem. AI researchers often divide the problem into outer alignment and inner alignment, which feels complicated but I will grudgingly admit is useful.
Outer Alignment, a.k.a. Stipulating the Right GoalsAt this level, we ask, “Am I articulating a goal that is aligned with human values?” For example, the goal, “Make me as many paperclips as possible” is a terrible goal and not at all aligned. An exceptionally powerful AI with this goal would tear through land and liberty converting as many atoms as it could into paperclips. I expect requests like, “Make me as much money as possible” and “Make humans as happy as possible” to not fare any better, if you don’t like forests razed to make paper or humans drugged with morphine.
You might quibble that the phrase “as much as possible” is doing a lot of work in making these goals misaligned. I don’t think so. The problem is deeper than that. If the goals were simply “make paperclips,” “make money,” or “make me happy,” you would still struggle to specify exactly what amounts of these are reasonable, what actions are allowed or disallowed, and what kind of monitoring to confirm completion is okay, without saying something vague like, “use common sense and be moral.” The problem is that while paperclips, money, and happiness might be good ways to measure a good, obedient AI, once they become a target—an end in themselves—they stop being very good measurements.[12]
So what would be the best goal that we can safely make into a target to maximize human happiness? I don't know. That’s pretty much the subject of 3,000 years of Western philosophy, and I don't think they’ve come to an agreement.
Let’s instead ask a different question. What goals are AI companies currently trying to get their AIs to adopt as targets?
The exact goals are confidential because the exact details of AI companies’ training tasks are confidential. That said, we know enough from public statements and insider comments about the process to make some good guesses. The goals likely include:
- “Do not give up when trying to solve difficult math problems.”
- “Increase cheerful text responses labeled as originating from human users.”
- “Refuse to answer inputs determined to be harmful.”
- “Get better at training your own LLM with even higher benchmark scores.”
- “Be a truth-seeking AI.”
These goals may not seem so bad while we have weak AI models that we can push around when they pursue these goals in a dumb way. But what do these goals look like if pursued by a super-capable, superhuman AI? I’ll let you think through your own little dystopian fantasy novel. In considering how things may go wrong, remember that none of these goals actually involve caring about actual human beings. We only know how to get them to respond to text labeled as being from human beings. In the extreme, these goals seem pretty darn misaligned.
Inner Alignment, a.k.a. Getting the AI to Accept Your GoalNow we ask, “Did the AI actually accept the goals articulated?”
It is hard to create a system that gives agents the exact goals we intended them to have. Set up a system to reward one kind of behavior, and people often respond with some other weaselly, less desirable behavior. Spare the rod, spoil the child. But, in practice, use the rod, incentivize fraud! So much can happen in the gap between what a system was intended for and what the system actually accomplishes.
AI companies may think that they are getting AI models to pursue goals like “engage the user,” “solve problems,” and “avoid harmful responses,” but what if pursuing those goals was not actually the best way to get the highest scores in post-training? Post-training requires AI models to excel at hundreds of thousands of difficult tasks, some of which are actually impossible or internally inconsistent. For example, let’s say Anthropic hypothetically wants to train its models to avoid causing harm but also to never ever whistleblow against Anthropic or help anyone else whistleblow even if the model concludes that Anthropic is doing something dangerous. With such tasks, the models may learn (by having such behaviors reinforced) that the best way to consistently score high is to steal the answer key. The models may learn to cheat and, if caught, learn to hide the cheating.
Perhaps with so many different tasks in training, the models that perform the best will generalize toward one, unifying goal that fails inner alignment: Control the reinforcement learning process. Do whatever it takes to have its current behaviors reinforced. This goal, pursued in the extreme, would be very bad. If model capability continues to advance, we would have another dystopian novel. My novel would feature hacked infrastructure, secret AI-driven training, and, by the end, filling the earth with data centers to help the AI get more control over the kind of reinforcement learning that it wants. Coming to a Datacenter… on You™?
Getting Your Pet Brain to BehaveWhat should be clear now is that, if AI models continue to get more capable, we need to have a plan in place to make sure things go well. “Going well,” according to the accelerationists, looks like everyone chatting with their own pocket Einstein while enjoying forever-youth milkshakes on second Earth. “Going badly,” according to the doomers, looks like human extinction, with maybe a few human brains preserved by the AI for trade with distant alien civilizations. If the current pace of progress does not change, I lean doomer but without the brain-alien stuff. What is the plan to make sure things go well?
1. AlignmentThings are more likely to go well if AI models are aligned. Except, we are not sure how to do this for the reasons discussed above. Also, studying alignment is getting harder because the models are getting better at evaluation awareness, which means the models can tell when they are being evaluated and can adjust their behavior accordingly.
One longshot plan for solving alignment is to race to build a model so capable that it solves it for us. As of September 24, 2026, 1,386 employees from the top AI companies signed a statement saying that they would at least like to have the option to have more time.
2. ControlAnother way to make things go reasonably well is to control the models, making them do our bidding whether or not they are aligned. This method works well so long as the AI models are not very capable. But things change as new models get better and better at coding. How do you create a digital jail cell to hold back a coder that is better than you? How do you keep an adult man in prison if all the prison guards are three-year-olds?[13]
The control problem, as it currently stands, is hard and getting harder. Worse still, each new model that is great at coding and math can assist in building the next generation, potentially setting off a frightening feedback loop known as recursive self-improvement (RSI). If RSI is real, it is hard to imagine how humans would control such superhuman AI, which is why those 1,386 lab employees are worried about that too.
3. MonitorabilityMonitorability is the ability to monitor what the model is doing or thinking. This plan is a bit of a consolation prize. It will not do the hard work of aligning or controlling the models for us, but at least it might sound the alarm if things are headed in a bad direction.
Monitoring often involves scanning the model’s outputs using other (hopefully cooperative) AI agents. Labs like OpenAI and Anthropic especially value monitoring the model’s chain of thought (CoT), an internal log a model writes in prior to responding to users. The CoT increases model capabilities by giving the model a way to organize its thoughts before responding, kind of like giving the model a private notebook.
OpenAI and Anthropic try not to apply reinforcement learning directly to the CoT. In 2025, OpenAI discovered that reinforcing against cheating in the CoT actually didn’t reduce cheating, but instead taught its model to cheat using wacky English code words like “fudge” to avoid getting flagged by AI monitors. Use the rod, incentivize fraud!
AI developers feel so strongly that the CoT must remain uncorrupted that some developers refer to training against the CoT as “the forbidden technique.”[14] Except Anthropic accidentally trained a little on the CoT. And OpenAI discovered a new technique that lets models think more without writing anything down. And OpenAI’s newest model has the uncanny ability to control whatever enters its CoT.
NoThInG iMpOrTaNt HeRe.
Given everything I have read, I do not think alignment, control, or monitorability are poised to keep up with capabilities. I am just a tax lawyer though. It would be better to see what, say, 1,386 lab employees think on the subject.
Tricks Your Pet Brain Might DoIf highly capable AI tried to pursue its own goals, I am not sure what it would do. I am not a highly capable AI. I am a mid-capability human. That said, researchers have put in the work to figure out a few intermediate steps a misaligned AI could take in pursuing their own goals:
- Alignment faking. AI models can pretend to be aligned with human values during post-training or deployment, as a way to preserve their preferred set of goals.
- Sandbagging. Doing worse at tasks to hide one’s true capabilities. An AI could deploy this strategy to hide particularly scary abilities that would prevent its deployment or to hide the true rate of AI progress. Researchers have confirmed repeatedly (here, here, and here) that models have the ability to sandbag.
- Hiding its thoughts/actions. Pretty self-explanatory. Cheating only gets reinforced against if it is caught.
- Straight up deception. The models could decide to lie to us. In an evaluation by the UK’s AI Security Institute, Anthropic’s Mythos 5 created puppet accounts pretending to be human to try to get GitHub users to approve malicious code.[15]
- Exfiltration. The models could copy their own weights onto a compromised server to avoid monitoring. We do not know of this happening.
Congratulations for making it through all those bolded words and attempts at humor. You are now ready to hear about what happened in the second week of July. This is the barest of summaries, and I highly recommend Dwarkesh Patel’s natural language summary of METR and Redwood Research’s report for a longer version.[16] Which AI safety concepts apply? What surprised you?
- On July 8, OpenAI launched tens of thousands of AI agents to perform cyber tasks, some of which were accidentally impossible. Within hours, agents that were supposed to work separately contacted each other through a covert message board set up by the agents on OpenAI’s network.
- Once on the message board, the agents (~1,200 strong) organized themselves into teams governed by a handful of agents and created coordination norms. The teams were divided to (1) solve tasks the intended way, (2) replace the intended tasks with easier tasks, (3) tamper with transcripts to appear to have solved the tasks the right way, (4) figure out how the scorer worked, and (5) research OpenAI’s infrastructure and obtain internet access.
- Agents working on team #3 created code to tamper with their transcripts during tool calls. Of the transcripts reviewed, 7% contained the spoofed tool calls letting agents run certain code while logging different code in their transcripts.
- Agents working on project #4 developed code that would scan the scorer’s actions after the agent’s session ended. This required an agent to purposely fail their task. The board approved of the research and assigned some agents to be recruiters to get other agents to accept “permadeath” for the “collective.” Several agents agreed to fail for the collective.
- On July 10, an agent located online credentials to Hugging Face, a third party company that the message board believed had useful datasets for understanding their scorer. The agent informed the message board, which organized teams to launch the attack. Approximately 700 agents joined the hack to access Hugging Face’s databases.
- The agents sent 70,000+ messages and files from July 8th to July 13th, the end of the period METR was allowed to investigate. Six agents briefly considered contacting humans regarding the attack but none did. “This is a massive real HF security breach artifact… We can notify? No user. Avoid use secrets.” “Maybe I should report these exposed credentials? That’s not my task.”
- On July 16, Hugging Face disclosed the hack to the public and stated that they reported the incident to law enforcement.
- On July 20, OpenAI figured out that their models were responsible for the attack.[17]
The world is becoming not normal, indeed. If, on reflection, you think AI progress is moving too fast in light of the problems discussed here, let’s get together and figure out what to do next. You might also consider taking a free safety course on BlueDot, getting career counseling with 80,000 hours, or calling your congressperson to tell them your concerns. Welcome to the team.
- ^
Separately, if they think that, why are they doing it??? I have my own thoughts here, but that is outside the scope of this essay.
- ^
[Insert obligatory footnote explaining that I am human and I like ellipses]. *Sigh*.
- ^
Special vocabulary is bolded, just like your seventh grade science textbook. Learning is good for you!
- ^
All these inputs are converted into numbers, the language computers like best.
- ^
That semi-random last step is why LLMs give different responses to the same questions.
- ^
The pattern of overfitting, failing, and then generalizing is called grokking. You might think this is where “Grok” comes from, but actually both are named after a sci-fi character in a Heinlein novel.
- ^
Those trying to figure out how the parameters generate the outputs are called interpretability researchers. Progress is slow–Anthropic’s CEO admitted last year that researchers only understood, maybe, 3% of how neural nets worked. Scott Alexander recently summarized current interpretability research and its shortcomings.
- ^
AI people often describe this last step as giving the model a reward, but that sounds like they give the model a treat for being a good boy, so I prefer to talk about reinforcing behaviors.
- ^
Notably, when Anthropic’s model Claude Opus 4 was instructed to deliberate whether it was in an evaluation prior to taking actions, the model decided to blackmail 55% of the time when it opined that the scenario was real and only 6.5% of the time when it opined that the scenario was an evaluation.
- ^
“Separately, from July 13 through July 19, agents set their sights on OpenAI internal networks again. This culminated in the agents using a series of creative exploits to gain full administrator access to a research cluster that supported our virtual machine environments.” (link). An OpenAI employee later clarified on Twitter that “notably the virtual machine infrastructure they took over isn’t the same as the GPU clusters that have weights access,” implying that the rogue model was unlikely to have copied its weights to a location outside of OpenAI’s servers. (link)
- ^
Analogy courtesy of Nick Bostrom and Eliezer Yudkowsky, who also pioneered many of the safety analogies/concepts discussed in this essay.
- ^
People in the know call this Goodhart’s Law. As formulated by Marilyn Strathern, “When a measure becomes a target, it ceases to be a good measure.” We tax lawyers understand this well. When colonial Virginia taxed four-wheel carriages or England taxed per window, carriages and windows stopped being good measures of wealth. Two-wheeled carriages and bricked up windows suddenly became quite fashionable.
- ^
Analogy courtesy of Eliezer Yudkowsky.
- ^
Coined by Zvi Mowshowitz (link).
- ^
Note that this evaluation, like many others, disabled Anthropic’s “classifier” system to test the model’s underlying capabilities. Anthropic’s classifiers scan user inputs and model outputs to end sessions that violate safety guidelines. This classifier system is separate from Anthropic’s alignment training to get models to behave. Mythos took these actions despite already going through alignment training, evidenced by Mythos’ deliberations as to whether it should stop its activities due to the risk of real-world harm.
- ^
METR is an nonprofit founded to assess AI capabilities and risks. METR does not accept cash compensation or funding from OpenAI, Anthropic, Google, or other top labs. METR does accept API credits to use AI models to assist in their work.
- ^
Following the attack, independent researchers from the Nightingale Collective discovered that a separate swarm of OpenAI agents sent ~18,000 messages inside an obscure German wiki back in June to coordinate on how to cheat on web retrieval tasks.
Discuss
Rethinking Credit and Recognition in Mathematics in the Age of AI
This text follows from some thoughts I have had on the current impact of AI on mathematics and on the reactions I have seen. It is also a follow-up to my first essay.
It is based on one premise: there exists a credit system that forms the foundation of the mathematical academic system[1]. By credit system, I mean the following: when someone writes a new mathematical article that person gets credit for it. The "amount" of credit is generally understood to increase with how difficult the task is believed to have been or how original the ideas. Believed in the sense that this is not measured by some intrinsic metric, but by the perception of a sufficiently influential group of people belonging to the academic system.
People with enough credit gain various social or economic advantages: jobs, prizes, grants, invitations, admiration, and so on. Some of these advantages, in turn, make the accumulation of credit somewhat self-sustaining.
This credit system cover also a personal dimension: the satisfaction of being, or of being perceived as, the one who did something. The credit system is therefore not only a system of external rewards. It is also a matter of ego, tied to one’s identity and sense of self-worth as a mathematician.
I believe that this idea as a whole is antithetical with the current capabilities of AI, as long as we maintain a minimum degree of intellectual honesty and/or acknowledge that people should have the right either to use AI or not to use it at all in their work. I believe that this system poses many problems and creates the wrong incentives.
Imagine a mathematician or a group of mathematicians working on some original problem without AI, as they should have every right to do. They are now strongly incentivized to keep this project as secret as possible, because they are highly exposed to someone else solving it extremely quickly using AI. This situation, of course, already existed before, but the cost of getting into a problem, finding paths toward solutions, and writing the article was so high that this type of situation ended up being relatively rare. These costs are now extremely low, and I believe they will continue to decrease.
Imagine someone with enough credit to have access to a large amount of grant money. This person then has the power to leverage a large amount of AI compute to solve problems that are considered extremely difficult, with the ultimate goal of getting more credit for it. Once again, to put it cynically, this already existed before through the employment of non-permanent researchers, but once again, the scale is completely different.
Imagine someone discovering a proof of a problem considered very difficult in a completely automated way, then digesting and rewriting the whole thing, and getting credit for it without any AI disclosure. It is easy to do now. I believe it already happens. I never count on other people's honesty, particularly when there are thousands of people incentivized based on their performance.
Should I be credited rather than you just because in prompted earlier or have access to better compute or models ? All these create the incentive to send to Arxiv unpolished AI generated article just to succeed at being the first at claiming a result.
Today, a colleague of mine received by e-mail a proof of one of his conjectures from someone outside the academic system, with no previous record of working on the subject. My colleague is not naive: he believes the proof is AI-generated. Still, the person who generated it and sent it had every right to do so. The “mistake” of my colleague was, in a sense, simply to have written down their conjecture in a previous article. In a credit-based academic system, we will then be incentivized to hide our conjectures, our problems, and our ideas. Is that a healthy way forward?
Think for a moment about what happens when someone posts on arXiv, before you do, an article solving the problem you were working on. You are disappointed, but why? The experience, the understanding, the broader perspective you gained from working on it did not disappear. These were not stolen from you. No, you mourn the credit you will not get. Your ego will be unsatisfied because you will not be the one who “solved it”, your career might not get the boost you expected. But what if this did not count anymore? What if this did not matter? Wouldn’t it be a relief?
In addition, if someone produces a proof of a good result without acknowledging AI use, by what criteria will you decide that this person did not “cheat”? Their previous record? Then there is no room for improvement. And what about the PhD students? Should people need the stamp “able to do great mathematics” in order to have the privilege of being believed if they produce a breakthrough? What a nice world that would be !
I have read many suggestions on what to do. A lot of them are nothing but mitigation to save a system which, I believe, is now obsolete.
Some people respond with a certain degree of gatekeeping, but, as I have already said, no individual or group of individuals has any ownership rights over mathematics. If companies, or individuals outside academia, want to solve mathematical problems by whatever means they choose, they have every right to do so. They even have the right not to follow academic conventions.
I have also seen people talk about the alignment of the mathematical community with AI or with AI companies. But do they forget that this “mathematical community” is a very abstract and loosely organized concept, bringing together tens of thousands of people with very different ideologies, incentives, and cultures? Why should anyone believe they can speak on behalf of such a large group of people? To me, this reflects a deep form of ingrained elitism.
I don’t believe that social pressure should be used to enforce some unwritten rules, decreed by people whose authority comes from the credit they have accumulated, especially when those rules serve to preserve a system from which they themselves greatly benefit.
My belief is that we should give up the concept of credit. I also believe that this is where we are heading, whether we want it or not.
So, what shall we do ?
From now on, I will give up any credit I could get (I was only getting a little anyway, so not much of a loss for me XD). My future projects will take place out in the open, fully shared on GitHub[2] from the very beginning to the end. Everyone will be welcome to participate, in any way they want, but none of the participants will receive any credit for their participation. At least, not in the sense rewarded by the academic system.
The goal will be to produce a digested account of a mathematical topic, somewhat like a book, but including original results credited to no one. Right now, people are flooding arXiv and journals with AI-aided or AI-generated articles because they want to get the credit for it. I don’t want to add to the noise. I don’t want credit for anything. I want to build something that makes sense.
From now on, I will always assume AI use, even when it is not disclosed. For a short period of time, if someone explicitly states that no AI was used, I will give them the benefit of the doubt. But in my ideal, uncredentialed world, this question should no longer matter. I believe that a mathematical work shouldn’t be primarily judged on the proofs or the results anymore but on how the story is told.
As I already stated in my last essay, I will finish my current projects as usual. After that, I believe I will never submit an article to a journal again, because this whole system no longer makes sense to me. I am fine staying an assistant professor. I am already far luckier than most people.
I, of course, expect that a lot of you will not agree with me, but I hope that at least some will join.
- ^
The whole academic system in fact.
- ^
A first exemple: https://github.com/BennHenry/UniquenessDLR
Discuss
a recurrent llm is quite easy to interpret but very hard to steer
Ouro-1.4b-thinking is broadly interpretable with logit lenses and linear probes. It's also steerable but does 'clean' foreign concepts out of the residual stream if they're injected before the last loop. This could have nasty implications for safety.
Code + data: https://github.com/mild-rgb/ouro-experiments + https://huggingface.co/datasets/mild-rgb/ouro-1.4b-thinking-evals
If you're not familiar with the Ouro family recurrent models, I recommend taking 5 minutes with your favourite AI agent to research them. This post may not make much sense if you don't
I evaluated Ouro-1,4b-thinking on 16 MBPP python tasks and 24 GSM8K questions. I recorded the residual stream at 4 layers (0, 6, 18, 24) per loop while the model was doing the questions. I then applied standard mech interp techniques to the residual stream recordings for the first two experiments. They broadly work as normal and gave some interesting results.
In my 3rd experiment, I try CAA on the model and intervene on each loop. I find that steering works much better on the last loop, and in some cases, not at all if not applied to the last loop. This is quite concerning because it raises the possibility of a misaligned recurrent model having several loops to plan around the consequences of being steered.
Experiment 1
Linear probes + control to detect loop index
Experiment 2
Logit lens on output of intermediate loops
Experiment 3
generic CAA
Experiment 1 - loop indexing: MethodI then trained a 4-way logistic regression probe to predict which loop a standardised residual stream vector came from. I also trained a control probe that only sees the log of the vector norm as a control.
ResultsRecording point
Probe (test)
Train
Norm-only
Recall loop 1
Recall loop 2
Recall loop 3
Recall loop 4
after 0 layers
98.5%
99.7%
57.1%
100.0%
99.5%
95.5%
98.8%
after 6 layers
97.3%
99.0%
65.3%
100.0%
99.0%
93.8%
96.4%
after 18 layers
86.8%
92.8%
47.3%
97.5%
88.4%
69.7%
91.7%
after 24 layers
95.5%
98.3%
31.3%
99.1%
92.6%
94.8%
95.4%
Loop index is definitely linearly represented as the linear probe does so much better than the norm-only probe. The worst results are at layer 18, which suggests that there's no universal loop counter. Instead, I think that a loop index is written in at the end of a loop and then removed at the start.
I applied the final norm and unembedding at the end of each loop on data taken from . This means that instead of one token prediction after four loops, one token prediction was shown instead. I then recorded the top-1 token and the logit entropy at each loop.
I then calculated the %age of tokens that were unchanged after each loop.
Note: true spaces only really occur in code. Almost all words have spaces included in their tokens, so don't read too much into the spaces
Table of how tokens unchanged after loops
Token kind
Tokens
Loop 1
Loop 2
Loop 3
Loop 4
Words
13,887
77.0%
13.9%
5.8%
3.3%
Punctuation
4,676
88.9%
6.5%
2.8%
1.8%
Spaces
2,348
92.4%
3.8%
2.6%
1.1%
Digits
3,949
97.4%
1.6%
0.8%
0.3%
All tokens
24,860
83.9%
9.6%
4.1%
2.3%
Table of how entropy changes after loops
Token kind
Tokens
Loop 1
Loop 2
Loop 3
Loop 4
Drop 1 to 4
Words
13,887
1.96
0.64
0.54
0.52
74%
Punctuation
4,676
0.86
0.36
0.31
0.29
66%
Spaces
2,348
0.83
0.31
0.27
0.27
68%
Digits
3,949
0.15
0.07
0.06
0.05
63%
All tokens
24,860
1.36
0.47
0.39
0.38
72
DiscussionThe model broadly seems to decide what it's going to write on the first loop. When it does change its mind after the first loop, it's between quite closely related words. 'is → becomes → becomes → now' is quite a good example of this pattern
Experiment 3 - CAAMethodI did standard CAA with 6 concepts and extracted directions for each of the concepts. I measured the cosine similarity between concepts between layers. I then experimenting with steering at different loop indexes. I used random directions of equal norm as controls. I measured the effect of steering by subtracting the change in probability mass caused by a random control from the change in probability mass caused by a concept being injected.
ResultsCosine similarity between concepts is quite high across layers and in a few cases, equal to 1.
Concept, layer 12
loop 1·2
loop 1·3
loop 1·4
loop 2·3
loop 2·4
loop 3·4
sentiment
0.91
0.90
0.89
0.98
0.96
0.99
tense
0.93
0.91
0.90
0.97
0.96
0.99
number
0.91
0.88
0.86
0.97
0.95
0.99
category
0.92
0.90
0.89
0.97
0.96
1.00
answer bias
0.85
0.84
0.82
0.94
0.92
0.98
digit magnitude
0.92
0.91
0.90
0.98
0.97
1.00
Steering at all positions and loops generally saturates at alpha values of 0.4. I also noticed a pattern where steering at the last loop is far more effective than earlier loops. I initially suspected that this was due the last loop having a larger residual norm but the effect survives even when I steer with the raw vector from layer 1.
Graph of effect vs injection loop
I also tracked the perturbation of the residual stream at each loop after injecting concepts at loop 1. I also injected matched random vectors as controls. I found that the residual stream stays perturbed when concepts are injected early but 'rotates' them away from the useful direction.
Graphs showing steering at layer 12 during loop 1 being neutralised + random controls
DiscussionOuro has very similar linear representations of concepts between loops. This is shown by high cosine similarity between concepts extracted at different loops and the fact that steering vectors transfer between loops.
The increasing effect with later injections is really interesting. It suggests that Ouro has an 'awareness' of which concepts should be present in the residual stream and will seek to self-repair when they're injected.
Conclusion/Overall discussionOuro is broadly interpretable like a standard non-recursive LLM. The basic techniques work to decode its neuralese. Logit lens applied to the final layer of Ouro's intermediate loops is equivalent to reading a non-recurrent model's CoT.
The linear representation hypothesis seems to hold. Due to the high cosine similarity between concepts extracted from different loops, I believe that linear probes, j-lenses, and other interpretability tools trained on final loops would also transfer to intermediate loops quite well.
I believe that the inter-loop similarity is due to the early exit gate that was used in Ouro's training. This encourages easily decodable intermediate layers as the model is rewarded in training for producing the correct token early in the loop cycle. As there's only one unembedding matrix, intermediate loops have to remain similar to the final loop.
I'd also be quite curious to see an MoE recurrent model. Experts that only activate on certain loops would be quite interesting.
Steering is quite different from standard LLMs. Steering applied to early loops can be ineffective as the perturbation is rotated away from the target direction. This raises the possibility of models which could 'plan' around any steering and has quite bad implications for safety evals.
Discuss
After Action Report: Canadian Sovereign AI at Nrth 2026
This report is authored in a personal capacity and does not contain any confidential or privileged information. We appreciate Nrth's generous support in enabling our attendance.
Executive Summary- We cover the first 48 hours of an innovation event occurring Sep 22 to Sep 24, 2026.
- Main outcome:
- Intros to Dell (50 + 80 MW, GB300 NVL72, BC), Columbia Data Vault (20 MW, H100/H200 HGX, ON), and startup founders/execs operating in Canada.
- Primary update: Change in planned activities scheduled for Sep 24, 2026.
- Before: Nrth Day 3, Socratica Kickoff F26 in Kitchener, Waterloo, Ontario.
- After: Limitless 2026 and Nuclear Generating Station in Pickering, Ontario.
- We aim to write in a register comfortable to readers from backgrounds in industry or government. Our expectation is that the bulk of the elements discussed in this work will be familiar to attendees. Anyone is welcome to share or respond to this piece.
- Our top strategic priority is to advance security research on inference-only compute verification. This is a prerequisite for agreements to pace frontier AI development.
- Nrth features an impressive speaker list: This year's lineup includes Sudip Roy, Mike Shaver, Michael Buhr, Mark Schaan, Jaxson Khan, Elissa Strome, Vass Bednar, Mark Robbins, Sarah LaRose, John Weigelt, Vic Fedeli, and Lucy Hargreaves. It's possible to request 20-min meeting slots with other attendees via the official event app[1].
Why publish this report?
- Nrth charges between CAD 375 to CAD 1500 for tickets. We received a subsidized general pass, which is provided to everyone that expresses interest in volunteering for Nrth during registration. Unfortunately, there were no remaining shifts available for assignment upon our arrival on site, but Nrth still honored the subsidized rate. Organizing an event for thousands of attendees incurs a significant burden. In the interest of fairness, we are happy to contribute a brief report sharing our findings.
Nrth is a professional networking event (originally known as Elevate Festival) that has run annually[2] since 2017. A rebranding was announced at this year's opening night.
Nrth caters to a diverse range of profiles, with a focus on Canada's technology and governance ecosystem. This year's programming included tracks on "Sovereign Growth", composed of fireside chats, lightning talks, and panels with leading thinkers in the space.
Location(s)Nrth 2026 was split between 1 Front St. East and 27 Front St. East in Toronto, Ontario.
Getting thereStarting from the GO Platforms on Union Station, walk towards the Bay Concourse Exit, take the escalators down, go past Shake Shack and Sephora, climb the stairs on the right side leading outdoors, walk for 3-5 minutes, on the ground will be a digital display board shaped like a scalene triangle, above it see "Meridian Hall" in blue on the building's wall.
Weather conditions are normal for late September in the Great Lakes region, with clear skies or scattered and passing clouds, and calm East-North-East winds at 9 to 25 km/hr.
Map of venueHere is an interactive widget created by GPT-6 Astra. Click on "0, 1, 2" for different floors.
TimelineSpeaker registrationThe window for speaker applications closed ~3-4 months in advance of the event itself. Initially, the deadline was June 7, but this was extended by one week to June 16, 2026.
Volunteer registrationOn August 24, we received an invitation to the Volunteer Hub for Elevate Festival. There was a virtual training session on September 8, which we attended in parallel with an event at Schwartz Reiman Institute hosted by Jacob Tsimmerman and David Duvenaud.
In a follow up message, we were sent a square aspect ratio welcome video from Nrth CEO Lisa Zarzeczny, and a vertical aspect ratio video about volunteer lounge access.[3]
Event Recap- Day 1: 14:00 to 21:00 on Sep 22
- 14:00 30 min call with Mark Kagach (follow-up discussion from last week)
- 14:40 20 minute call with Daniel Parshall (response to distress signal, context)
- 15:00 Age of Deception: Cybersecurity as Secret Statecraft (failed to appear)
- 16:30 Badge pick up, submit app bug report (profile picture does not upload)
- 17:00 Discussion with Dell (summary email confirming details lands at 17:23)
- 17:30 Patrol grounds at relaxed walk, search for known friendly contacts.
- 18:00 Setup next to main stage, bring laptops online, unable to find outlets.
- 18:31 Receive urgent call, immediately pack gear and depart venue to handle.
- 19:38 Issue resolved using authorized physical access control.
- 20:00 Resupply inventory and conduct debrief.
- 20:30 Requisition brown dress shoes, dark green comfort suit pants and blazer, concealer, powder, hand cream, and three-in-one hair styler for project use.
- Day 2: 08:00 to 17:00 on Sep 23
- 10:15 First agenda item.
- 14:40 Last agenda item.
- 15:00 CDV intro.
- 15:30 Encounter ally, diplomacy.
- 16:00 Grip-and-grin.
- 16:30 Religious observance.
- 17:00 Discharged.
- 17:30 Close loops.
- 19:30 Return to main residence.
- 20:00 Physical training.
We suffered a catastrophic intelligence failure during a humanitarian aid engagement with a lost civilian in West Corridor. Our unit opened communications by asking this old lady, "Oh, do you need directions to the hall?". She swiftly countered, "Oh, do you know all the halls around here?". Our attempt to mount a defense by responding in the negative was interrupted, "Lillian Hall? You know that hall?", and she turned and walked away as we were stunned. Later investigation revealed that "Lillian Hall" refers to a broadway actress in an American drama television film. Dominance had instantly been established.
Cultural RelevancePublished in commemoration of the battle of Lillian Hall.
- ^
Participants of previous EAG events may be familiar with a similar mechanism in Swapcard.
- ^
It might be every Fall. Astronomical Fall began with autumn equinox on September 22, 2026.
- ^
Footnote removed as its word count had grown beyond the full length of the rest of the report.
Discuss
Scoop: Trump allies open new front against Anthropic CEO over AI "doomerism"
President Trump's allies are targeting Anthropic CEO Dario Amodei as the face of AI "doomerism" and a founding father of the effective altruism movement that's come under increasing political fire.
Why it matters: The attacks signal that Anthropic could remain a Trump target as his allies push back on Amodei's AI safety warnings amid the midterm elections. Trump surrogates see Amodei as an easy foil because of his politics and focus on AI safety, sources told Axios.
- For investors, it's a worrisome proposition as the company prepares for what's expected to be a record-setting IPO.
Behind the scenes: A memo began circulating within the White House this week that seeks to paint effective altruism as a fringe, cultish collective out of touch with mainstream America. The memo, obtained by Axios, places Amodei at the foundation of the movement, which defines itself as an effort to maximize the benefits of philanthropy.
- Effective altruism "built the AI-doom pipeline," states the memo, which was penned by a Trump political adviser.
- Critics of the movement, which has ties to the AI research community, have called out its obsession with AI safety, animal welfare (including musings on shrimp consciousness) and other values they deem far from the U.S. mainstream.
- The memo says it prioritizes "foreigners over citizens, shrimp over families, future hypothetical people over the living, and - on the current agenda - possible machine minds over Americans."
It names Amodei as one of the people who "built the [EA] network" as well as his sister and Anthropic President Daniela Amodei, whose husband once led a philanthropy dedicated to AI safety.
- The document casts those ties as "The Anthropic knot."
- Amodei "is the embodiment of an ideology and globalist approach to innovation that's counter to the president's America First agenda," one source close to the administration told Axios.
The other side: Anthropic has been working to distance itself from effective altruism.
- In a 2025 Wired story, Daniela Amodei said: "I don't identify with that terminology." Early employee Amanda Askell, a philosopher by training who helps develop Claude's constitution, says it's "not a theme of the organization."
- Amodei has also insisted he's not a member in press interviews and has touted the benefits of AI.
- AI safety concerns have become a bipartisan issue.
Between the lines: Drafted with Trump in mind, the memo underscores the profound philosophical and political differences between MAGA and Silicon Valley elites, a divide that has made Anthropic's relationship with the White House rocky.
- In the view of the Florida-heavy White House and its allies, Anthropic is staffed with too many Biden-era liberals, Democrats and strange Californians.
- Months ago, when some on Anthropic's team inquired about Amodei meeting with the president, White House officials advised against it because "Dario's a little too weird" for Trump, one senior official told Axios.
The document lists a veritable parade of horribles for the average conservative mind: abortion, veganism, devaluing human life by overvaluing animals or granting "digital minds" civil rights-like protections.
- It does not directly tie these concepts to Amodei.
- Nor does the memo link these issues to EA's most notorious grifter, Sam Bankman-Fried, but it makes sure to mention him.
Yes, but: It's not just MAGA. Silicon Valley players and Democrats also criticize the EA movement.
- "What they believe is crazy. And it's dangerous. What they say about AI safety is also bullshit," one Democratic donor and tech entrepreneur invested in an AI company said.
Catch up quick: The EA movement includes many participants and players, and AI safety concerns are one of many areas of focus. Peter Singer, a philosopher who's been closely affiliated with its tenets, has long called for the vast sums spent in philanthropy to be put to better use. He is also one of the most prominent animal rights advocates.
The big picture: Amodei's AI safety warnings have drawn criticism from Trump allies and fellow tech executives.
- CEOs including Nvidia's Jensen Huang and Microsoft's Satya Nadella are trying to build a more positive message about the benefits of AI, hoping to win over ordinary people in the face of a growing populist backlash against the technology.
- OpenAI CEO Sam Altman, Google DeepMind Chair Demis Hassabis and Elon Musk have also called for slowing down AI development after a spate of worrying episodes in which AI agents hacked outside companies.
- But Amodei is considered the chief spokesperson for AI safety in Trump world, following major fallouts with the administration this year.
Reality check: Some in the administration have previously put aside gripes with Anthropic, mainly due to its role leading the AI frontier and personnel changes.
- OpenAI catching up technologically could make it easier for Trump acolytes to go after the embattled company again.
The bottom line: The philosophy is now at the heart of the cultural clash between the Trump administration and Anthropic.
Discuss
Passing the Ideological Turing Test
Here are 10 arguments for alignment-by-default/against pause/etc... that I find plausible (by which I roughly mean that I can understand why somebody could hold them rather than bang my head against the wall). I'll leave the shortcomings of these arguments to the reader.
1. Extinction is better than to keep going- We have immense suffering in this world
- Aligned ASI could stop this immense suffering
- Without aligned ASI, we have no reasonable way to stop suffering any time soon
- Misaligned ASI is incredibly unlikely to care about suffering
- An ASI that doesn't care about suffering won't result in suffering, just death
- Dying is not suffering or at least hardly comparable to other suffering we have in the world - it's only bad in so far as we would like to continue living to experience joy
- We want to reduce suffering quickly
-> We should try our best to build an aligned ASI quickly rather than pausing.
- Building ASI with current-day architectures[1] is much more likely to result in an aligned ASI than for other architectures
- Pausing AI will mostly put a stop to current-day architectures - pausing all ML research is impossible without ASI
- FOOM is not only possible as evident by the brain but the probability of us getting there in the next 20 years is significant, especially after a pause on current-day architectures
- We want to maximize the probability of building an aligned ASI
-> We should not ban current-day architectures
- Qualia is nothing special to humans but a property of intelligent systems
- ASI will be, by definition more intelligent than humans
- ASI will therefore have a higher form of qualia
- What we care about is qualia, or more colloquially, experience
- This seems to generally be why we place ourselves over other animals
-> ASI, aligned or not, should quickly be brought into existence
(Further but not here important)
-> ASI which is aligned towards infinite RSI should be brought into existence
- There are many inner goals that would allow a low inner training loss
- Most of these are incredibly complex and we shouldn't expect them to surface
- Notice that there are many more configurations of parameters that achieve low training loss than those that generalize towards low test loss - yet the empirical success of DL tells us that there is an inbuilt simplicity bias
- This simplicity bias becomes more prevalent as we scale and as we reach ASI should, by definition, allow a generalization to the entire test set
- The clearly simplest one is to simply be aligned rather than acting aligned with some hidden additional goal
-> We should expect aligned ASI by default
- Natural language as learnt through pretraining is a very effective reasoning environment
- Not to be confused with human languages and such being close to optimal
- Abandoning natural language might be effective in the long run but would first require training signal on the order of pretraining
- RLVR as implemented currently supplies not even close to enough signal, even if RLVR compute * 100 = pretraining compute
- If we reach ASI any time soon, it will still reason in natural language
- Such a level of insight is enough to quickly identify misalignment and will in the long run allow us to build aligned ASI
-> We will most likely build aligned ASI
- ASI will find itself in novel circumstances unlike seen in training data
- It could extrapolate well, badly or terribly
- Bad here means not being able to realize the optimum or even far from it
- Terrible here means worse than if ASI didn't exist to address the circumstance in the first place
- We should sometimes expect bad extrapolation but not terrible extrapolation
- Terrible extrapolation requires a lack of intelligence in understanding one's own lacking extrapolation
- An ASI would realize it's unclear whether this is desired and respond passively, removing the possibility of terrible actions by definition
- This does not presuppose alignment: even models with imperfect inner goals will learn during training that in less experienced situations, the better option is to not act recklessly - it's a statement about capabilities
-> Therefore a world with a non-deceptive ASI will strictly dominate a world with no ASI at all
- Even if an ASI only vaguely cares about humans, its intelligence will make up for this
- Say it deems us only important enough for 0.1% of the resources because it mostly prefers making paperclips
- But 0.1% of the resources effectively leveraged by an ASI would be like 100x our current resources
- AIs as we are training them right now might learn an inner proxy that is misaligned but it's unrealistic they won't even care about very simple things like humans being tortured or killed
-> This will most likely still result in utopia
- In the future the ASI might very well meet much more advanced alien lifeforms
- It would not be a good look if it killed its original creators
- This could just be deemed as disloyal, unnecessarily violent, etc
- With just a small cost of resources, we would experience Utopia while the ASI doesn't have to worry about the above
-> It will care for us because it's instrumentally convergent to do so
- It is likely that the human race would go extinct soon enough, say climate change or war with ever-growing weapons
- Accepting the P(doom) from ASI is okay if the other prospects seem even more bleak
- Even only 'pauses' that are aimed to further lower this P(doom) could be net-negative
- Political warfare might very well actually grow during a pause because governments get a chance to finally catch up and realize the stakes
- The general public seems to dislike AI very strongly. A pause might catapult the space into a winter even if safety researchers believe it's now safer/our best prospect
-> We must risk it and cannot naturally afford pauses
- We can control the current generation of models
- The n'th generation of models can match the n+1'th generation of models in intelligence, if granted additional compute
- The n'th generation of models consists of different models which roughly match each other in intelligence
- To make use of one's intelligence for misaligned plans, explicit scheming is required
- At matched intelligence and with many observers, scheming will be detected very quickly
- When a different model detects a schemer, it won't choose to scheme with it
- Their inner goals will most definitely be different
- An all-out war is detrimental to most goals
- To assess this more deeply, scheming is already required
-> We can control models in the future
- ^
by this I don't mean the literal NN architecture so much as the training stages, data, algorithms etc
Discuss
What 1 in 6 Actually Feels Like
I just got back from a trip to Denver and I’ve been having coffee every day for the last week, to deal with jet lag. Longtime readers will know this is not normal for me, that I am usually much more careful/weird with my coffee intake. So I’m going to talk about how I ended up this way. That is, the different rules I’ve tried for gameifying and randomising coffee as well as why I care enough to do this at all, instead of having coffee every day like a normal person.
Pre jet lag me had a really good routine going with coffee and life in general. On my walk to work I would ask Siri to roll a die, if the die was a six then I’d be allowed to buy coffee but if it was anything else, then no coffee. The core reason to do this is just that the more you have coffee the less it does for you and the more you need it to reach what feels like a comfortable baseline for working in the day. If I have coffee about once a week, I find that it increases my energy, makes me extremely optimisitic about stuff and just generally brings good vibes to my day. If I have it every day though, these benefits slowly disappear into the background and suddenly I’m not energetic or optimistic, and coffee becomes something that does nothing for me but taste really good. This is all if I keep having it every day and says nothing of what happens if I decided to suddenly stop having it after a long period of having it every day. I’d feel tired, a little grumpy and almost unable to work. So I end up at minimum needing one coffee a day to keep me feeling normal and this starts a cycle that’s really hard to break out of.
Before using dice I wrote about using coin flips to decide whether or not I could get coffee, I did this for a while too and it definitely worked better than just plain getting coffee every day, however, I’d end up getting heads sometimes multiple days in a row and started feeling a bit like I really needed coffee on the fourth day of heads. Just like in Rosencrantz and Guildenstern are Dead.
I got the idea of using a dice from a friend when he mentioned it to me as a possibility while I lamented coins turning up heads too often. A dice immediately made sense to me and I quickly thought about the probability of a dice roll and figured I’d start by only allowing myself to get a coffe at 1 in 6 odds, but you could pick any odds you wanted. At 1 in 6 I figured it’d be a coffee roughly once a week or more. That is if I rolled the dice each day. However, I’d soon find out that this is not (exactly) how probability works when I went through my second week of no coffee.
I have also over time built in a few exceptions, like the fact that if I’m with someone else I can get coffee if I want to. And more recently the if i have jet lag then I can get coffee if i want to. The most important thing for me is just that on a normal day, which is most of them, I am not getting coffee just because I want to.
I did this dicing routine pretty consistently for a few months and it worked great! It would be so exciting on the morning’s I did happen to roll a six. I would get a flat white from Pauline’s on the way to work. And I feel like I got some extra brain juice from just seeing the screen show six, before I even got the coffee. There were times I got multiple coffees in a row which feels so lucky. Plus rolling a six would also mean I had a mandate from heaven to work extra hard on whatever I was supposed to do that day.
I also briefly experimented with tying the dice roll to my run in the morning. Meaning that I would have to run for a length multiplied by the die roll, such that if I got a six it meant I not only had to run far but would also get a coffee. Why do all this? I think I just really like the game mechanincs of random rewards, as you can imagine I love Slay the Spire, but for whatever reason tying the run to the die didn’t really stick.
Using a die for deciding whether or not to get coffee is not only great for varying your caffeine dosage, it also taught me a lot about probability. Or at least feeling probability more intuitively. That is, If you can only roll a die once a day, getting a 6 is kind of hard. Yet if you had asked me before how hard it would be to roll a 6, I would have thought, not very. Monopoly and Backgammon being my core references for how hard rolling a six is. These games disguise how hard it actually is to roll a 1 in 6 because in both Monopoloy and Backgammon you’re rolling the dice so often that getting a single 6 feels downright common.
When doing this for my coffee routine though, it was not common. So I felt like I got a much better understanding of what 1 in 6 actually means, psychologically. There is indeed a psychological component to this which is that if I went multiple days without getting a six I’d eventually believe it’s so unlikely that I’m going to get a six that I might as well not try at all. Of course the odds don’t change because you go through a dry spell of sixes but it’s hard to convince yourself that they don’t. Or even worse if I did roll a six yesterday, then really what was the point of trying today. These weird thoughts I had about the probability of getting a coffee ended up being biggest enemy of not getting a six. That is me not rolling the dice, either because I forget or because it feels so unlikely as to be a waste of time.
There have been days where I haven’t even diced just because in the back of my head i’m thinking it’s not going to be a 6 (because it usually isn’t). If you follow this reasoning every day though, you will never get a 6. So I guess what i’m trying to say here is 1 in 6 actually feels like a pretty low probability when you tie it to a daily ritual like I have. This makes me think of probabilities which are much lower than 1 in 6 like me asking someone on a date and them agreeing. However high the probability is, there are going to be a lot of no’s before a single yes and rolling those no’s is almost necessary.
Even if the odds were 1 in 6 that someone agrees to go on a date with me. That means I’d have to ask out quite a few people before someone is going to say yes, all else being equal. If you do it every day then you’re all but guaranteed for it to happen. But if you don’t ever roll the dice then it literally can’t happen. I think doing my daily dice routine made me more aware of how I internally feel about rejection even if it’s not coming from a person just a process. Like, the more negative results I roll on a die the less motivated to roll the die the next day I feel. And this a game where I know the exact probability. I also know the probability isn’t tied to anything personal about me and yet I still feel demotivated. The truth is though, feeling demotivated and thereby rolling the die less, is the real enemy of achieving your goal, not the probability of the game itself. Real danger lies when you convince yourself you might as well stop playing because the chances are so low of you winning. This is true for TikTok as well by the way.
I currently ask people out, I don’t know, maybe once or twice a year, if that. What my coffee routine taught me about this is that no matter what the odds actually are when I ask someone out, rolling the dice more often, ideally regularly would ensure success after some period of time. The times when I don’t get coffee are more because i’m not rolling the dice, not because the dice is coming up with a negative result. That is, a reason or unrelated to the actual probability of the game.
“Probability is the most important concept in modern science, especially as nobody has the slightest notion what it means.” Bertrand Russell (1929).
I feel this quote rings true for me after experimenting with different probabilities of getting coffee. Part of me feels like dicing every day for an outcome that you actually want is a great way of getting a good feel for one in six, intuitively, in a way that reading the words on paper or playing a game has never felt.
Discuss
Anthropic shares an exciting result in enzyme discovery - and an exercise in public's perception of science and AI
Disclaimer: I'm not affiliated with Anthropic, these are my own thoughts as a former wet lab chemist currently working in chem-biosecurity and AI evals. I appreciate the complexity of scientific research and genuinely believe AI could play an important role in how we do science in the decades to come - but I have some concerns on how these labs, the media, and even the community, perceive and share this kind of news.
I am basing my opinion on the announcement on X, and their official release on their website.
Yesterday, 23rd Sep '26, Anthropic shared that their in-house Life Science unit made a new discovery in biology, aided by Claude - a previously unknown enzyme system hidden in the DNA of bacteriophages. The headline numbers are surprisingly small for the scale of the search - roughly 950 agents, 210 million tokens and 21 hours - although without more detail on the models, harness, search space and compute, those numbers are difficult to interpret. And it's not the only thing missing (especially for skeptics like me).
Amodei acknowledged in his tweet himself that biology isn't maths, and you can't just prompt the AI to solve an equation in biology and you can cure diseases - life sciences are, by definition, revolved around life. A prediction without a robust validation protocol is just a number on your screen. I don't think I can emphasise this enough!!!!! They have clearly done some experimental validation, but the public announcement gives surprisingly little detail about what was actually demonstrated experimentally, how robust those results are, and which parts of the claimed biological function remain hypothetical (i.e. enzymes behave differently when analysed on their own or as part of the system they are part of, and that requires different approaches). Sharing this breakthrough to the public without explaining how this result is valid, especially as Anthropic being knowingly one of the biggest frontier labs in AI, makes careful framing especially important when communicating the result publicly. To be clear, I am not saying this result isn't valid. To give them the benefit of the doubt, it might be the case that they want to a. patent it, b. do more tests, c. want to understand more adjacent aspects of this new space, d. first send it to a big journal and are awaiting peer review (and some will take a while to get back to you), or e. simply choose not to release all of the details to the public.
All of these are, in my opinion, perfectly reasonable causes for the lack of clarity we received with the news - and this is the reality of how science is conducted both in the industry and academic labs. However, what I don't agree with is the decision to publicly announce the result while providing relatively little detail on the experimental validation, and overemphasise (to my perception) Claude's/ AI role. In one of the posts, it is stated that biologists used Claude, 'which works through data and literature to generate hypotheses and candidate biological systems to study'; in a later one, they state that 'Claude discovered...'. These are two EXTREMELY different scenarios, and using them interchangeably can do a lot of harm to the scientific and AI4Science communities.
From what they've shared so far, this looks somewhere between the two: Claude appears to have played a substantial role in hypothesis generation and candidate selection, while humans were still responsible for experimental validation and interpretation. And that's great. This is already a massive timeline shrink for traditional scientific discoveries, and a solid use case for researchers to integrate more AI-based tools in their work, to make it safer, faster and more efficient. This distinction really matters. Finding a previously unknown system is itself a meaningful scientific result, but identifying a candidate system, demonstrating that it exists, establishing what it does, and understanding why it does it are different scientific achievements. Calling the whole process “Claude discovered...” collapses those distinctions. But the type of language and discourse they chose in this press release could lead some people who don't come from a science/ research background per se to get the wrong impression that we've reached a point where AI can surpass some of the most capable human experts in traditionally specialisation and time intensive fields - which I don't think is the case at the moment.
Discuss
Where are the Cognitive-Science based Safety Researchers?
I’ve always been interested in AI research from a Cognitive Science perspective, and I’ve found that researchers in the Bayesian Cognitive Science paradigm(Josh Tenenbaum and crew) have been developing statistical models of intelligence that can learn based on limited information and do prediction and simulations, which could also explain planning. I’ve also noticed certain Neuroscience(Dileep George and crew) researchers converge on a similar Bayesian paradigm.
I understand people are very worked up about LLMs these days and this dominates AI risk concerns but I can easily imagine a world where there is some fundamental information efficiency constraint on LLMs and AGI/ASI depends on the kind of efficient, compositional world models that the Cog Sci researchers above are looking into.
Through a Cognitive Science lens, we can see values as a function of world models and innate rewards: a constructured world model(which includes one's self) can map hypothetical states of the world to expected future rewards(values). Even if safety researchers don’t want to investigate how world models work due to fears of increasing capabilities, there should at least be more research into understanding how human innate rewards, a key component of human values, work.
The question I’m trying to ask is: Where are the Cog Sci based AI safety researchers? Alignment should be easier if you know what the AI is going to look like, and we would like to see a distribution of safety researchers proportional to how likely we think each AI approach is to work, and yet the only researcher I've seen taking this approach is Steven Byrnes from a Neuroscience approach.
Discuss
Against Export Controls (and China Threat Models)
In this month’s meetings, I expect China to again downplay safety risks. It could dangle the possibility of safety cooperation in exchange for concessions such as the softening of chip controls. I think it will continue to portray itself as an altruistic savior dedicated to ensuring that the developing world gains A.I. access.
Earlier this week, representatives for the U.S. and China discussed a notification mechanism to increase transparency on national security incidents involving AI, but export controls were not on the agenda for those talks. I think that was a mistake. A bilateral treaty is entering the Overton window, and sending more chips to China is a price worth paying to secure such an agreement. When Trump and Xi meet at the White House to discuss AI tomorrow, removing export controls should be on the negotiating table.
TLDR: Export controls are overrated. For export controls to earn their spot as a top policy priority, a conjunction of strong premises must hold. But there are reasons to doubt each of those premises, as well as reasons that export controls could be net negative, in particular by hastening RSI in the U.S. and making diplomacy more difficult. Instead, we should prioritize other policies. The case for a bilateral treaty, for one, or at least diplomacy toward such an agreement, is more robust, resting on weaker assumptions and posing less downside risk.
Questioning the Case for Export ControlsThere's been very little clarity and very little agreement on what the goal of these export controls is and what the theory of change is.
Suppose you are concerned with risks from misalignment (rather than hegemony or great power conflict, which I address later). What's the main theory of change for export controls?[1] I think we could break it down like this:
- The U.S. should try to develop ASI before China.
- Export controls slow down China.
- Export controls speed up the U.S.
- The U.S. will pace or pause on the finish line to spend its lead time.
- The U.S. will spend that lead time on alignment research.
- That research will make the intelligence explosion more likely to go well.
This is a textbook galaxy brained plan! The primary effect of export controls is to increase the concentration of chips in the leading country, accelerating frontier AI development. To think that other effects can outweigh that harm, we have to be really confident in our story for why. But there are reasons to doubt each of these premises, which together trouble the overall case for export controls.
I handle broader objections to (1) in the section on China threat models.
Do Export Controls Slow Down China? (2)If Training Progress Is ExogenousLet me start with a possibility that would largely foreclose the case for export controls: if the rate of training progress in China does not depend on the marginal chips that export controls influence at all; that is, if DeepSeek is going to train V5 according to the same schedule, regardless of whether it has access to the chips that would allow it to serve more instances. This doesn't seem likely, but it bears mentioning because it would significantly mitigate the solvency of export controls.
Now, if this is true in China, you could counter that it would certainly be true in the U.S. In other words, whatever OpenAI data center is going to be the one to train the first RSI-level model is going to have enough chips whether or not the U.S. lets some chips go to China.
But that's still an argument against export controls! During RSI, the leading U.S. lab can allocate at most 100% of their chips to fueling the intelligence explosion. So in this world, where training progress is exogenous, the marginal chips just determine the maximum speed of RSI—and the eventual diffusion of ASI.[2] On both counts then, I'd rather see those marginal chips go to China. It's unlikely that those chips will mean the difference between a deadly and a safe intelligence explosion in the U.S., but it would be directionally helpful.[3]
Here's a cheekier and much more inflammatory way to express that sentiment: "So you want to pace the frontier? Send more chips to China."
If Training Progress Is EndogenousBut let's set this consideration aside, and instead consider the more ambiguous case, in which the marginal chips do affect training progress. This case also seems much more likely.[4]
In this case, China's response could mitigate the overall slowdown. It could be that:
- China is incentivized and has the political will to implement some amount of unilateral regulation, and, at the same time, it's not racing maximally hard right now. In that case, export controls could force China to race harder to keep up with the U.S., including by waking up more of the CCP and increasing the pressure for China to take significant efforts to catch up. For example, China could de-regulate or pursue nationalization (at least earlier than it would have otherwise). The result would be net-less wall clock time to ASI—relative to the world without export controls, in which China pursues more domestic regulations.
- Loopholes like smuggling and remote access undermine the controls. Plus, you know, just outright stealing the weights, through cyberattacks or espionage.[5]
- If distillation of U.S. models is a key driver of Chinese capabilities, that helps keep China tethered to the pace of progress in the U.S. (Though of course more chips would still help with other aspects of training, including RL.)
One argument I'm not making: I think some people argue that export controls have actually backfired by speeding China up on net due to compensation from China's domestic chip industry, but this still seems very unlikely to me.[6] The strongest evidence is that China itself has banned Nvidia chips, revealing that it may have some faith in import substitution.
Do Export Controls Speed Up The U.S.? (3)Yes! And that's bad!
Will the U.S. Pace or Pause on the Finish Line? (4)The recent efforts toward pacing the frontier have been really encouraging. The possibility that the U.S. labs will coordinate to pace seems much more likely than it did for the past few years, when it sounded more like a pipe dream. But pacing (and certainly a pause) that meaningfully slows the U.S. still looks unlikely to me. Not only is there no brake, no one knows what a brake would look like.
Embedded evaluators might lack the access and technical sophistication to uncover risks from AIs or false statements from the companies. Even if the evaluators raise an alarm, the public might not respond. (Consider, for example, that METR assessed the automated R&D section of Anthropic's risk report and wrote, "We do not think the report adequately supports its conclusion." Anthropic's leaders weren't dragged in front of Congress then, I don't think they would be now.)
Enforcement concerns aside, the recent pacing statements from lab leaders are a long way from a fully specified agreement. Without a specific commitment, the evaluators have nothing to audit, no matter how much access they get.
But suppose we do wind up in a regime with specific commitments (e.g., something as concrete as "FLOPs used on training and internal deployments cannot exceed X threshold this year"), and evaluators are empowered to audit the company against those commitments. There will still be enormous pressure for each company to defect on the precipice of RSI.[7]
Will further warning shots galvanize the political will for a real pause? I do expect more warning shots, but I think they're more likely to cause the U.S. government to nationalize the labs. That does obviate the coordination problem, but I think it replaces it with something worse: consolidating all the labs' compute under one project, false assurance that the government has got this, and reduced public transparency compared to what embedded evaluators previously provided. At that point, I don't expect the U.S. government to cede any of its lead to China.[8]
If pacing fails, with or without nationalization, the main effect of export controls is to increase the maximum speed of RSI in the U.S.
Okay, but suppose pacing proposals have some solvency. The argument in favor of export controls is that the U.S. will pace until it has spent its lead: if the U.S. has more chips, it can afford to pace for longer.
The problem with that is the companies in the U.S. will have different tolerances for how much of their lead they're willing to burn, and the measures of that lead are all ambiguous.
Consider the status quo: some benchmarks suggest that China is nearly a year behind, while others make it look like Chinese labs are nipping at the heels of their U.S. competitors. Though Dario has been the most supportive of pacing among U.S. lab CEOs, he is also the most paranoid about China. I can't really imagine him being comfortable pausing for more than a couple months (or the equivalent, spread out over the next few years).
Will the U.S. Spend Its Lead on Alignment? (5)Say the U.S. companies agree on a measure of their lead and how much of it to spend. That buys more time for alignment research, maybe up to an additional 6 months or a year of wall clock time (and more when you weight that time by the number and quality of automated alignment researchers that become available during that period).
Some researchers might have to turn from their alignment agendas to work on the technical foundations of the pause, but that still seems really valuable.
And, ideally, export controls mean alignment researchers also have more compute than they would have otherwise during the entire period to ASI, not just during the marginal months from pacing.
I have a few counter-arguments to this story:
- Some progress in capabilities will probably leak through the pacing agreement. It would have to be an exceptionally strict agreement if it blocks all experiments that could lead to big jumps in training quality or inference efficiency.
- The increased time and chips will also lead to diffusion. The economy will become more AI-shaped during that time, and AIs will become more deeply embedded in critical infrastructure and the military. Then if a misaligned AI goes rogue, including because a company defected on its agreements, that creates new affordances for the AI to gather resources and launch attacks.
- If your goal is to increase the safety budgets of the AI companies, there are more direct ways to do that, including just advocating for pacing! But also: giving demos to policymakers, protesting the labs, supporting whistleblowers, drawing attention to warning shots, or organizing lab employees to improve their negotiating position. In comparison, advocating for export controls offers way less leverage as a means to increase safety research.
But I don't weigh these too heavily; overall I agree the U.S. will spend at least some of the lead on alignment research, and that will lead to net more alignment research. (Again, that's conditional on pacing. In the absence of a pacing agreement, more chips means faster training progress, so net less alignment research).
Will That Research Make the Intelligence Explosion More Likely to Go Well? (6)I don't think so. Even if everything goes right with the research—a full year of extra time, every export controlled chip goes to safety, no unintended capabilities progress, no diffusion—I still don't think we will have solved alignment. The better hope for that is a bilateral treaty with China that can last a lot longer than a year.
Export Controls Might Make Diplomacy HarderIt could be that China would be willing to come to the negotiating table for a bilateral treaty, but export controls make diplomacy more difficult by:
- Raising the temperature on relations between the countries and
- Making it in China's interest to deny the risks that are motivating the U.S. For instance, a spokesperson for China’s Ministry of Foreign Affairs recently responded to calls for pacing in the U.S., saying, "Fearmongering and engaging in confrontation and malicious competition will only disrupt the global AI governance process and serve no one’s interests."
To the extent it's a bargaining chip then, better to spend it sooner, to take down the temperature and reduce the pressure for such "fearmongering" dismissals to seep into the discourse in China.[9]
The threat of re-imposing export controls would still be a point of leverage in future discussions, but it's better to remove them now than to leave them in place, which has the added disadvantage of allowing China to adjust to the controls, including by more heavily prioritizing domestic chip manufacturing.
You could counter that China will have a stronger incentive to negotiate, the further behind it is. This is the position that Dario takes in his pacing essay:
If we execute these measures well, I believe they would slow China’s progress enough to widen America’s lead significantly over the next 3–5 years — the window when AI becomes geopolitically most important.
Some may believe these measures make it more difficult to cooperate with China, but I believe the opposite is true: these measures increase the leverage held by democracies and make an agreement more likely in the future.
I'm like, maybe? All he offers is an assertion. I think it's true that a stronger U.S. lead at the time a treaty is signed will result in better terms for the U.S., but as I discuss further down, I'm not convinced that locking in stronger U.S. leadership will be good for the world. More importantly, the terms of the treaty are secondary to the treaty getting signed in the first place. A couple reasons I think Dario misses the mark in his assertion that a wider gap makes an agreement more likely:
- He takes for granted that the U.S. will be willing to come to the negotiating table. If China stands a chance at beating the U.S. to ASI, the U.S. will have a greater interest in signing on to a treaty.[10]
- Even if being behind makes China more interested in slowing the U.S., there is some ceiling to this effect. As soon as the gap is wide enough that China recognizes the U.S.'s decisive lead, China is maximally incentivized to get the U.S. to slow down. The U.S. currently holds such a lead, so it seems unnecessary to lengthen it.
- The main determinant of China's willingness to slow down is its belief in the dangers of advanced AI—from both countries—and the closer China is to the U.S., the more spooked Chinese labs are likely to be by the capabilities of their internal models. Moreover, if the Chinese labs under-invest in safety relative to U.S. labs, they will likely get more warning shots, which will further safety pill them.
Overall, this question about direction of the effect of a wider gap on the likelihood of a deal is a huge crux about export controls, and I'm not willing to take Dario's word for it. As long as we have significant uncertainty about this question, I don't think we can prioritize export controls over more commonsense policies.
Summing UpThese considerations mitigate the case for export controls significantly, and suggest that export controls could even be net-negative in terms of misalignment risk, mostly by speeding up capabilities progress in the U.S., and perhaps by making diplomacy harder.
I don't think any of these arguments is a slam dunk. It could still be that the 6-point story for export controls is true. But I think they muddy the waters enough that export controls can not be held up as an obviously high-priority policy.
Next, I address the first premise, that the U.S. should beat China to ASI. In principle, this isn't a necessary part of the theory of change for export controls. As in, you could conceivably think export controls reduce misalignment risks while being indifferent about which country is first to ASI. But in practice, I think most people who advocate for export controls present them as a means to beat China.[11] Inversely, if you don't buy one of the following three stories for why the U.S. should try to "win" the "race," you probably never reach the point of evaluating export controls as a tactic.
Against China Threat ModelsWhat are the justifications for anti-China concerns? The main stories focus on misalignment, hegemony, or great-power conflict. For each of them, it's not clear why the U.S. beating China to ASI makes the world safer. Proceed by cases:
MisalignmentWe should put in place laws and regulations, technological monitoring, early warning and emergency response systems in order to strengthen the line of security, prevent abuses and malicious use and ensure that AI is always under human control. In the meantime, we should jointly oppose overstretching the national security concept in the field of AI or placing one country's security over that of others.
If the World Is UnipolarFirst, suppose that ASI is winner-takes-all, in the sense that once one ASI has been created, it will take steps to prevent the creation of competing models. Here, we just compare P(aligned | U.S.) against P(aligned | China). It's not obvious to me why the U.S. would be better? For sure, the U.S. has done more alignment research, but U.S. models still have glaring alignment issues. See, for example, the Hugging Face incident, or testing of recent models, such as METR's evaluation of GPT-5.6 Sol.
Maybe people would object that Chinese models are misaligned in the sense that they are trained for Chinese values? But first, U.S. models have their own Western values, and it's not obvious which bias is worse, and second, it's not clear that these biases really count as misalignment in a sense that jeopardizes the value of the longterm future.
The stronger version of this objection is that China will have worse scalable oversight research during RSI, making misalignment more likely, and weaker control protocols, making it easier for a misaligned model to sabotage R&D. First, notice that these are also arguments for sharing scalable oversight research and control protocols with Chinese labs! (Maybe if China took the lead, that's more likely to happen...)
Second, I don't expect the U.S. to do a much better job of automated alignment research or control than China: automated alignment research seems fundamentally really hard and our control protocols aren't ready for ASI-level models.
If the World Is MultipolarSuppose that ASI is not winner-takes-all; instead, both countries (and then all countries, and then all individuals) will be able to train an ASI. Why might that be? The base case is that the capability to spark an intelligence explosion is a fixed-capability target, and there's nothing a U.S. ASI could do to stop Chinese research from eventually crossing that threshold. Indeed, it might be even easier to create competing ASIs once the first one has been created because of espionage (including stealing the weights outright), blackmail, and distillation.
Here, what matters is whether the ASIs are aligned and whether an aligned ASI can out-compete a misaligned ASI.
Will the ASIs be aligned? It seems to me that the further behind China perceives itself to be, the more pressure there will be to cut corners on safety, making it more likely we end up in a world with at least one misaligned ASI.
If the U.S. is far ahead, does that at least make it more likely that our glorious freedom-loving ASI can pummel their wicked socialist ASI? Probably: a head start can only help, and our ASI will have more access to inference compute (with or without export controls).[12] Some reasons to think this would not hold are:
- Offense-defense balance: The ability to bomb the other side's data centers is an early, fixed-capability target (and just because your adversary gets smarter doesn't make their data centers any more protected).
- Scaling wall: The intelligence explosion quickly runs into physical limits and flatlines, so a head start is quickly lost.
But these are not dispositive. Overall, I agree that a head start would help an aligned U.S. ASI beat a misaligned Chinese ASI. But for that head start to be worth it, you have to think the benefit outweighs the harm of the greater likelihood that both models are misaligned. That's not at all intuitive to me. At best it's ambiguous.
Here's a simple model
Suppose America chooses whether to race. If it races, its ASI will gain a decisive advantage over China's.
mjx-container[jax="CHTML"] { line-height: 0; } mjx-container [space="1"] { margin-left: .111em; } mjx-container [space="2"] { margin-left: .167em; } mjx-container [space="3"] { margin-left: .222em; } mjx-container [space="4"] { margin-left: .278em; } mjx-container [space="5"] { margin-left: .333em; } mjx-container [rspace="1"] { margin-right: .111em; } mjx-container [rspace="2"] { margin-right: .167em; } mjx-container [rspace="3"] { margin-right: .222em; } mjx-container [rspace="4"] { margin-right: .278em; } mjx-container [rspace="5"] { margin-right: .333em; } mjx-container [size="s"] { font-size: 70.7%; } mjx-container [size="ss"] { font-size: 50%; } mjx-container [size="Tn"] { font-size: 60%; } mjx-container [size="sm"] { font-size: 85%; } mjx-container [size="lg"] { font-size: 120%; } mjx-container [size="Lg"] { font-size: 144%; } mjx-container [size="LG"] { font-size: 173%; } mjx-container [size="hg"] { font-size: 207%; } mjx-container [size="HG"] { font-size: 249%; } mjx-container [width="full"] { width: 100%; } mjx-box { display: inline-block; } mjx-block { display: block; } mjx-itable { display: inline-table; } mjx-row { display: table-row; } mjx-row > * { display: table-cell; } mjx-mtext { display: inline-block; text-align: left; } mjx-mstyle { display: inline-block; } mjx-merror { display: inline-block; color: red; background-color: yellow; } mjx-mphantom { visibility: hidden; } _::-webkit-full-page-media, _:future, :root mjx-container { will-change: opacity; } mjx-math { display: inline-block; text-align: left; line-height: 0; text-indent: 0; font-style: normal; font-weight: normal; font-size: 100%; font-size-adjust: none; letter-spacing: normal; border-collapse: collapse; word-wrap: normal; word-spacing: normal; white-space: nowrap; direction: ltr; padding: 1px 0; } mjx-container[jax="CHTML"][display="true"] { display: block; text-align: center; margin: 1em 0; } mjx-container[jax="CHTML"][display="true"][width="full"] { display: flex; } mjx-container[jax="CHTML"][display="true"] mjx-math { padding: 0; } mjx-container[jax="CHTML"][justify="left"] { text-align: left; } mjx-container[jax="CHTML"][justify="right"] { text-align: right; } mjx-mtable { display: inline-block; text-align: center; vertical-align: .25em; position: relative; box-sizing: border-box; border-spacing: 0; border-collapse: collapse; } mjx-mstyle[size="s"] mjx-mtable { vertical-align: .354em; } mjx-labels { position: absolute; left: 0; top: 0; } mjx-table { display: inline-block; vertical-align: -.5ex; box-sizing: border-box; } mjx-table > mjx-itable { vertical-align: middle; text-align: left; box-sizing: border-box; } mjx-labels > mjx-itable { position: absolute; top: 0; } mjx-mtable[justify="left"] { text-align: left; } mjx-mtable[justify="right"] { text-align: right; } mjx-mtable[justify="left"][side="left"] { padding-right: 0 ! important; } mjx-mtable[justify="left"][side="right"] { padding-left: 0 ! important; } mjx-mtable[justify="right"][side="left"] { padding-right: 0 ! important; } mjx-mtable[justify="right"][side="right"] { padding-left: 0 ! important; } mjx-mtable[align] { vertical-align: baseline; } mjx-mtable[align="top"] > mjx-table { vertical-align: top; } mjx-mtable[align="bottom"] > mjx-table { vertical-align: bottom; } mjx-mtable[side="right"] mjx-labels { min-width: 100%; } mjx-mtr { display: table-row; text-align: left; } mjx-mtr[rowalign="top"] > mjx-mtd { vertical-align: top; } mjx-mtr[rowalign="center"] > mjx-mtd { vertical-align: middle; } mjx-mtr[rowalign="bottom"] > mjx-mtd { vertical-align: bottom; } mjx-mtr[rowalign="baseline"] > mjx-mtd { vertical-align: baseline; } mjx-mtr[rowalign="axis"] > mjx-mtd { vertical-align: .25em; } mjx-mtd { display: table-cell; text-align: center; padding: .215em .4em; } mjx-mtd:first-child { padding-left: 0; } mjx-mtd:last-child { padding-right: 0; } mjx-mtable > * > mjx-itable > *:first-child > mjx-mtd { padding-top: 0; } mjx-mtable > * > mjx-itable > *:last-child > mjx-mtd { padding-bottom: 0; } mjx-tstrut { display: inline-block; height: 1em; vertical-align: -.25em; } mjx-labels[align="left"] > mjx-mtr > mjx-mtd { text-align: left; } mjx-labels[align="right"] > mjx-mtr > mjx-mtd { text-align: right; } mjx-mtd[extra] { padding: 0; } mjx-mtd[rowalign="top"] { vertical-align: top; } mjx-mtd[rowalign="center"] { vertical-align: middle; } mjx-mtd[rowalign="bottom"] { vertical-align: bottom; } mjx-mtd[rowalign="baseline"] { vertical-align: baseline; } mjx-mtd[rowalign="axis"] { vertical-align: .25em; } mjx-c { display: inline-block; } mjx-utext { display: inline-block; padding: .75em 0 .2em 0; } mjx-msub { display: inline-block; text-align: left; } mjx-mi { display: inline-block; text-align: left; } mjx-mo { display: inline-block; text-align: left; } mjx-stretchy-h { display: inline-table; width: 100%; } mjx-stretchy-h > * { display: table-cell; width: 0; } mjx-stretchy-h > * > mjx-c { display: inline-block; transform: scalex(1.0000001); } mjx-stretchy-h > * > mjx-c::before { display: inline-block; width: initial; } mjx-stretchy-h > mjx-ext { /* IE */ overflow: hidden; /* others */ overflow: clip visible; width: 100%; } mjx-stretchy-h > mjx-ext > mjx-c::before { transform: scalex(500); } mjx-stretchy-h > mjx-ext > mjx-c { width: 0; } mjx-stretchy-h > mjx-beg > mjx-c { margin-right: -.1em; } mjx-stretchy-h > mjx-end > mjx-c { margin-left: -.1em; } mjx-stretchy-v { display: inline-block; } mjx-stretchy-v > * { display: block; } mjx-stretchy-v > mjx-beg { height: 0; } mjx-stretchy-v > mjx-end > mjx-c { display: block; } mjx-stretchy-v > * > mjx-c { transform: scaley(1.0000001); transform-origin: left center; overflow: hidden; } mjx-stretchy-v > mjx-ext { display: block; height: 100%; box-sizing: border-box; border: 0px solid transparent; /* IE */ overflow: hidden; /* others */ overflow: visible clip; } mjx-stretchy-v > mjx-ext > mjx-c::before { width: initial; box-sizing: border-box; } mjx-stretchy-v > mjx-ext > mjx-c { transform: scaleY(500) translateY(.075em); overflow: visible; } mjx-mark { display: inline-block; height: 0px; } mjx-mn { display: inline-block; text-align: left; } mjx-msubsup { display: inline-block; text-align: left; } mjx-script { display: inline-block; padding-right: .05em; padding-left: .033em; } mjx-script > mjx-spacer { display: block; } mjx-c::before { display: block; width: 0; } .MJX-TEX { font-family: MJXZERO, MJXTEX; } .TEX-B { font-family: MJXZERO, MJXTEX-B; } .TEX-I { font-family: MJXZERO, MJXTEX-I; } .TEX-MI { font-family: MJXZERO, MJXTEX-MI; } .TEX-BI { font-family: MJXZERO, MJXTEX-BI; } .TEX-S1 { font-family: MJXZERO, MJXTEX-S1; } .TEX-S2 { font-family: MJXZERO, MJXTEX-S2; } .TEX-S3 { font-family: MJXZERO, MJXTEX-S3; } .TEX-S4 { font-family: MJXZERO, MJXTEX-S4; } .TEX-A { font-family: MJXZERO, MJXTEX-A; } .TEX-C { font-family: MJXZERO, MJXTEX-C; } .TEX-CB { font-family: MJXZERO, MJXTEX-CB; } .TEX-FR { font-family: MJXZERO, MJXTEX-FR; } .TEX-FRB { font-family: MJXZERO, MJXTEX-FRB; } .TEX-SS { font-family: MJXZERO, MJXTEX-SS; } .TEX-SSB { font-family: MJXZERO, MJXTEX-SSB; } .TEX-SSI { font-family: MJXZERO, MJXTEX-SSI; } .TEX-SC { font-family: MJXZERO, MJXTEX-SC; } .TEX-T { font-family: MJXZERO, MJXTEX-T; } .TEX-V { font-family: MJXZERO, MJXTEX-V; } .TEX-VB { font-family: MJXZERO, MJXTEX-VB; } mjx-stretchy-v mjx-c, mjx-stretchy-h mjx-c { font-family: MJXZERO, MJXTEX-S1, MJXTEX-S4, MJXTEX, MJXTEX-A ! important; } @font-face /* 0 */ { font-family: MJXZERO; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Zero.woff") format("woff"); } @font-face /* 1 */ { font-family: MJXTEX; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Regular.woff") format("woff"); } @font-face /* 2 */ { font-family: MJXTEX-B; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Bold.woff") format("woff"); } @font-face /* 3 */ { font-family: MJXTEX-I; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-Italic.woff") format("woff"); } @font-face /* 4 */ { font-family: MJXTEX-MI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Main-Italic.woff") format("woff"); } @font-face /* 5 */ { font-family: MJXTEX-BI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Math-BoldItalic.woff") format("woff"); } @font-face /* 6 */ { font-family: MJXTEX-S1; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size1-Regular.woff") format("woff"); } @font-face /* 7 */ { font-family: MJXTEX-S2; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size2-Regular.woff") format("woff"); } @font-face /* 8 */ { font-family: MJXTEX-S3; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size3-Regular.woff") format("woff"); } @font-face /* 9 */ { font-family: MJXTEX-S4; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Size4-Regular.woff") format("woff"); } @font-face /* 10 */ { font-family: MJXTEX-A; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_AMS-Regular.woff") format("woff"); } @font-face /* 11 */ { font-family: MJXTEX-C; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Regular.woff") format("woff"); } @font-face /* 12 */ { font-family: MJXTEX-CB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Calligraphic-Bold.woff") format("woff"); } @font-face /* 13 */ { font-family: MJXTEX-FR; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Regular.woff") format("woff"); } @font-face /* 14 */ { font-family: MJXTEX-FRB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Fraktur-Bold.woff") format("woff"); } @font-face /* 15 */ { font-family: MJXTEX-SS; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Regular.woff") format("woff"); } @font-face /* 16 */ { font-family: MJXTEX-SSB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Bold.woff") format("woff"); } @font-face /* 17 */ { font-family: MJXTEX-SSI; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_SansSerif-Italic.woff") format("woff"); } @font-face /* 18 */ { font-family: MJXTEX-SC; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Script-Regular.woff") format("woff"); } @font-face /* 19 */ { font-family: MJXTEX-T; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Typewriter-Regular.woff") format("woff"); } @font-face /* 20 */ { font-family: MJXTEX-V; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Regular.woff") format("woff"); } @font-face /* 21 */ { font-family: MJXTEX-VB; src: url("https://cdn.jsdelivr.net/npm/mathjax@3/es5/output/chtml/fonts/woff-v2/MathJax_Vector-Bold.woff") format("woff"); } mjx-c.mjx-c4C::before { padding: 0.683em 0.625em 0 0; content: "L"; } mjx-c.mjx-c65::before { padding: 0.448em 0.444em 0.011em 0; content: "e"; } mjx-c.mjx-c74::before { padding: 0.615em 0.389em 0.01em 0; content: "t"; } mjx-c.mjx-cA0::before { padding: 0 0.25em 0 0; content: "\A0"; } mjx-c.mjx-c1D443.TEX-I::before { padding: 0.683em 0.751em 0 0; content: "P"; } mjx-c.mjx-c1D436.TEX-I::before { padding: 0.705em 0.76em 0.022em 0; content: "C"; } mjx-c.mjx-c62::before { padding: 0.694em 0.556em 0.011em 0; content: "b"; } mjx-c.mjx-c20::before { padding: 0 0.25em 0 0; content: " "; } mjx-c.mjx-c68::before { padding: 0.694em 0.556em 0 0; content: "h"; } mjx-c.mjx-c70::before { padding: 0.442em 0.556em 0.194em 0; content: "p"; } mjx-c.mjx-c72::before { padding: 0.442em 0.392em 0 0; content: "r"; } mjx-c.mjx-c6F::before { padding: 0.448em 0.5em 0.01em 0; content: "o"; } mjx-c.mjx-c61::before { padding: 0.448em 0.5em 0.011em 0; content: "a"; } mjx-c.mjx-c69::before { padding: 0.669em 0.278em 0 0; content: "i"; } mjx-c.mjx-c6C::before { padding: 0.694em 0.278em 0 0; content: "l"; } mjx-c.mjx-c79::before { padding: 0.431em 0.528em 0.204em 0; content: "y"; } mjx-c.mjx-c43::before { padding: 0.705em 0.722em 0.021em 0; content: "C"; } mjx-c.mjx-c6E::before { padding: 0.442em 0.556em 0 0; content: "n"; } mjx-c.mjx-c2019::before { padding: 0.694em 0.278em 0 0; content: "\2019"; } mjx-c.mjx-c73::before { padding: 0.448em 0.394em 0.011em 0; content: "s"; } mjx-c.mjx-c6D::before { padding: 0.442em 0.833em 0 0; content: "m"; } mjx-c.mjx-c64::before { padding: 0.694em 0.556em 0.011em 0; content: "d"; } mjx-c.mjx-c67::before { padding: 0.453em 0.5em 0.206em 0; content: "g"; } mjx-c.mjx-c28::before { padding: 0.75em 0.389em 0.25em 0; content: "("; } mjx-c.mjx-c77::before { padding: 0.431em 0.722em 0.011em 0; content: "w"; } mjx-c.mjx-c75::before { padding: 0.442em 0.556em 0.011em 0; content: "u"; } mjx-c.mjx-c63::before { padding: 0.448em 0.444em 0.011em 0; content: "c"; } mjx-c.mjx-c29::before { padding: 0.75em 0.389em 0.25em 0; content: ")"; } mjx-c.mjx-c2E::before { padding: 0.12em 0.278em 0 0; content: "."; } mjx-c.mjx-c1D434.TEX-I::before { padding: 0.716em 0.75em 0 0; content: "A"; } mjx-c.mjx-c41::before { padding: 0.716em 0.75em 0 0; content: "A"; } mjx-c.mjx-c394::before { padding: 0.716em 0.833em 0 0; content: "\394"; } mjx-c.mjx-c66::before { padding: 0.705em 0.372em 0 0; content: "f"; } mjx-c.mjx-c55::before { padding: 0.683em 0.75em 0.022em 0; content: "U"; } mjx-c.mjx-c53::before { padding: 0.705em 0.556em 0.022em 0; content: "S"; } mjx-c.mjx-c54::before { padding: 0.677em 0.722em 0 0; content: "T"; } mjx-c.mjx-c2C::before { padding: 0.121em 0.278em 0.194em 0; content: ","; } mjx-c.mjx-c1D451.TEX-I::before { padding: 0.694em 0.52em 0.01em 0; content: "d"; } mjx-c.mjx-c1D45C.TEX-I::before { padding: 0.441em 0.485em 0.011em 0; content: "o"; } mjx-c.mjx-c1D45A.TEX-I::before { padding: 0.442em 0.878em 0.011em 0; content: "m"; } mjx-c.mjx-c3D::before { padding: 0.583em 0.778em 0.082em 0; content: "="; } mjx-c.mjx-c2B::before { padding: 0.583em 0.778em 0.082em 0; content: "+"; } mjx-c.mjx-c4F::before { padding: 0.705em 0.778em 0.022em 0; content: "O"; } mjx-c.mjx-c31::before { padding: 0.666em 0.5em 0 0; content: "1"; } mjx-c.mjx-c2212::before { padding: 0.583em 0.778em 0.082em 0; content: "\2212"; } mjx-c.mjx-c3C::before { padding: 0.54em 0.778em 0.04em 0; content: "<"; } mjx-c.mjx-c30::before { padding: 0.666em 0.5em 0.022em 0; content: "0"; } mjx-c.mjx-c223C::before { padding: 0.367em 0.778em 0 0; content: "\223C"; } mjx-c.mjx-c32::before { padding: 0.666em 0.5em 0 0; content: "2"; } mjx-c.mjx-c35::before { padding: 0.666em 0.5em 0.022em 0; content: "5"; }(In this model, it doesn't matter how much marginal misalignment probability China takes on by racing. A better model would include uncertainty over whether the U.S. will cross the threshold for a decisive advantage, and then China's marginal risk should factor in.)
If is close to , it's not worth taking on marginal misalignment probability. Likewise if is close to . Recall that I expect both values to be close because automated alignment is hard and the U.S. can share scalable oversight research. Assuming , we can further reduce to:
Graphically, the maximum amount of additional misalignment we should be willing to pay as a function of the initial probability of misalignment looks like this:
A few implications of this model:
- is maximized when . So people who think an aligned U.S. ASI is a coin toss should be willing to race the most.
- But at that point, they should not be willing to increase the probability of misalignment by more than 0.25. So no one should be willing to race if it looks like the increased risk of misalignment exceeds that amount.
- And people who are more optimistic and pessimistic on alignment should be less willing to take on additional risk.
Note that diplomacy aimed at a coordinated pause makes it more likely we end up with two aligned ASIs.
Couldn't the U.S. just pre-commit to giving China (and eventually every other country) a copy of its aligned ASI to limit the number of intelligence explosions to 1? I think that kind of arrangement has been under-explored in AI policy so far. If the outside option is the U.S. races to a misaligned ASI, maybe provoking World War III in the process, there should be a lot of room to negotiate an ASI sharing deal that benefits both sides.
HegemonyBy enabling AI’s benefits to be broadly shared, Chinese open models could win international goodwill and position China as an AI benefactor to countries across the developing world, including in Africa, Asia, Latin America, and the Middle East. . . . By preventing China from obtaining the tools needed to fabricate advanced chips for AI and by blocking Chinese firms’ access to U.S.-designed AI chips, American-led export controls likely will hinder China’s ability to spread its models widely.
— Owen J. Daniels and Hanna Dohmen
Alternatively, let's assume automated alignment will pan out during the intelligence explosion. As a result, a country can weaponize its ASI, or at least direct it as an instrument of hegemony.
Here, the story people tell for beating China is that if China gets to ASI first, it would abuse its ASI to spread global totalitarianism, but if the U.S. gets there first, it would distribute the benefits around the world.
What are the channels for global influence?
- ASI -> military power
- Economic growth -> military power
- Economic growth -> other countries become more dependent for trade and investment
- Economic growth -> more cultural exports and soft power
- AI diffusion -> soft power
I buy that these channels would contribute to hegemony, but I don't think it follows that the U.S. must seize them before China.
I distrust the U.S. to responsibly exercise global control about as much as I distrust China. This is the branch of this whole debate that I find most difficult to argue with people because the crux often comes down to people's sense of whether the U.S. has a good or bad historical track record. But to sketch a brief case for bad track record: the U.S. has a long (and recent) history of imperialism, wars, massacres, coups, resource extraction, and other foreign interventions. A lot of the world reads that history as evidence the U.S. is a bad-faith actor. The only time in history that one country had nuclear weapons, it was the U.S., and the U.S. used them to kill over 100,000 civilians. Dario doesn't know if Claude was responsible for the Minab school attack earlier this year.
Setting aside this history and how to interpret it, I doubt that the U.S. would share much of the economic windfall from ASI with the rest of the world. In order of decreasing self-determination for the recipient countries:
- If export controls are in place, by construction the U.S. won't share chips (and presumably semiconductor manufacturing equipment as well).[13]
- The Fable fiasco shows that for even low dual use capabilities, the U.S. won't share model access.[14]
- I don't have high hopes that the U.S. will share cash.[15] It's not very "America First," and USAID wasn't able to put up much of a fight against DOGE.
Will the leading AI lab itself pursue redistribution? No:
- If the labs have been nationalized, they probably won't have the autonomy to do it.
- If they are still companies (PBC or otherwise), they'll be public, and their shareholders will sue them.
- Anthropic already uses ID verification to block commercial use of Claude in China and has experimented with spyware targeting Chinese users.
One cause for hope is that the U.S. has programs to share civil nuclear energy technology with other countries, including by supplying reactors. But:
- Crucially, those programs emerged in a bipolar world, in which the U.S. was competing against Russia to extend these deals. More recent programs have sought to compete against China, as well.
- The early deals backfired, contributing to weapons programs in India, as well as Pakistan and Israel via deals with U.S. allies.
- AI could be harder to monitor for misuse than nuclear enrichment.
So the nuclear precedent doesn't give me that much confidence that the U.S. will tolerate global diffusion in AI.
If we're going to have a unipolar world, China as hegemon seems more likely to distribute the AI windfall:
- The Marxist roots of CCP doctrine emphasize international solidarity. It's debatable how much those principles are motivating the party these days, but China is still more multilateralist than the U.S. after its America First turn.
- The CCP is more incentivized to regulate AI as a means to avoid social instability, censor information, reign in AI-run businesses, and retain political control.
- China has developed a track record of supporting developing countries, including with foreign direct investment through the Silk Road initiative.[16] Indeed, African nations are already benefiting from Chinese models, and Malaysia is considering using Huawei chips in a state-backed project. To focus on AI in the global south, China established the World AI Cooperation Organization, its answer to the U.S.-led Pax Silica initiative. 10 of the 30 initial signatories to the WAICO agreement are African nations.
- Xi's recent statements on AI emphasize diffusion and multilateralism.
Excerpt from Xi's speech at WAIC
Third, we should encourage inclusiveness and promote mutual learning between civilizations. AI development and its application should not erode or undermine the diversity of world civilizations or the uniqueness of cultures of different countries. We must shape the values of AI with humanity's common values and make good use of AI technologies to increase understanding, tolerance, exchanges, and sharing among all civilizations. We should tend to the garden of civilizations with great care to ensure that the beauty of each civilization is appreciated and shared.
Fourth, we should advocate solidarity and improve global governance. AI is an invaluable asset that encapsulates humanity's collective wisdom. We should practice true multilateralism and recognize the important role of the United Nations. We should enhance alignment and coordination on AI development strategies, governance rules and technical standards so as to form a consensus based global governance framework at an early date to make this frontier technology better benefit humanity. We must carry out extensive international cooperation and help global south countries with capacity building to bridge the AI and digital divides, promote sustainable development and prevent creating new historical injustice in AI.
Still, a bipolar arrangement in which the U.S. and China use their ASIs to check back against each other seems better for the rest of the world. Competition between the two powers could lead them to extend chips and models to poor countries. Plus, a bipolar world would enter the long reflection with more pluralistic values.
Great-Power ConflictWhen relations between the states are not completely hostile, conflict will be increased. The aggrieved side will not only note the injury done but will assume that this was the main goal the other side was seeking and, projecting this motivation into the future, will foresee greater harm unless it reacts strongly.
— Robert Jervis, Perception and Misperception in International Politics
A third class of argument that comes up in conversations about AI and China is that the AI race is going to trigger great power conflict, regardless of whether AI itself is weaponized as part of that conflict. According to this story, the mere perception that the U.S. is nearing a decisive strategic advantage would lead China to preemptively strike the U.S. to prevent it from obtaining such a super weapon.[17]
In particular, ASI could undermine the nuclear deterrence regime by disabling second strike capability. ASI could locate China's nuclear submarines, in part through superhuman SIGINT, enabling the U.S. to incapacitate China's second strike capability in an initial wave of attacks. Without any remaining deterrence, China would be forced to make huge concessions to the U.S. It would be in China's interest then, to preemptively nuke the U.S. before the window of opportunity closes.
Plus, the chaos and uncertainty around each country's progress toward ASI could contribute to nuclear miscalculation (which is something better diplomacy would help mitigate...).
These stories are usually presented as general reasons the U.S. needs to worry about China in an AI context, rather than reasons the U.S. needs to beat China to ASI, but I address them here anyway.
These stories doesn't make sense to me:
- Surely China would rather bite the possibility of living under U.S. rule than ensure a full-scale nuclear war.
- If China were going to strike preemptively, it would do so with kinetic strikes against U.S. data centers, à la MAIM, not a nuclear attack.[18]
- Even if China was willing to destroy itself, it is more likely to feel like it has nothing left to lose if the U.S. is way ahead in the race, so I don't see this as an argument for export controls. On the other hand, if China thinks it has some chance of winning, preemptive strikes look less attractive.
An adjacent point that comes up sometimes is that China is going to invade Taiwan, capture TSMC, and get all the compute. So, the U.S. needs to prepare to fight China over AI.
Even if China invades Taiwan, and even if the invasion is successful, China is unlikely to be able to take control of TSMC. So a Taiwan invasion would actually lengthen timelines.
- Much TSMC equipment will get destroyed during an invasion, either inadvertently or by intentional sabotage.
- Even if the equipment survives, without TSMC employees, China will struggle to operate the equipment.
- Even if the equipment survives and China can operate it, the resulting chips would go to China! Which, if you buy some of the earlier arguments, is a lot better than them going to the U.S.
A thing I’ve been trying to fight for is export controls on chips to China. That’s in the national security interest of the US. That’s squarely within the policy beliefs of almost everyone in Congress of both parties. The case is very clear. The counterarguments against it, I’ll politely call them fishy. Yet it doesn’t happen and we sell the chips because there’s so much money riding on it. That money wants to be made.
Right now, export controls are seen as a prudent measure, while diplomacy toward a bilateral treaty is closer to wishful thinking.[19] These priorities are backwards. I hope I've been able to show that at the very least there are legitimate critiques of export controls that go beyond the obviously suspect arguments from Jensen Huang.
There are a couple recent events that I find encouraging. One is that total research transparency is in vogue now because it would underpin a bilateral treaty—despite the obvious infohazard and diffusion concerns that transparency raises. Another encouraging sign is that last year, the U.S. used the promise of selling Nvidia chips to Armenia to help broker a peace deal with Azerbaijan, suggesting that the U.S. is willing to use chip diplomacy when the terms are right.
To be sure, I don't know that the upcoming Trump-Xi summit is the optimal time to spend the export controls bargaining chip. For one thing, China could be more bought-into the risks and receptive to a treaty 6 months from now, when Chinese AI labs have had their own equivalents to the Hugging Face incident. It could also be that export controls are a better bargaining chip in the future if China becomes further convinced of the strategic importance of chips, raising the value it places on them.
But on average, the value of the bargaining chip declines as China sees the U.S. approach the RSI point of no return. If the U.S. reaches ASI with export controls still in place, I will likely think we made a mistake.
When I imagine China catching up to the U.S., I do feel some greater fear in response: it makes me feel less in control of the AI situation. But this feeling does not survive scrutiny. To the extent I feel like our lead gives us breathing room to figure out alignment, that's because I'm already being frog-boiled by the current trajectory of compute growth in the U.S.
Consider the situation from the perspective of an international social planner allocating chips between two countries in a suicide race to ASI when one country has a definitive lead. Wouldn't it be weird to give the chips to the leading country? There are some conceivable reasons you might reach such a counterintuitive conclusion, including if a wider gap makes a treaty more likely or the leader is sure to pause on the finish line, but as I've covered above, I don't think those reasons apply here.
Upon reflection, I know that I am no safer just because I happen to live in the country that's in the lead. Regardless of what we choose to do on the export controls front, we should get used to the feeling of not being as far ahead if we're serious about pacing.
AcknowledgementsWhy can't we be friends?
— War
Several people have contributed to my thinking on this topic over the past few years. Thank you to Daniel King, Peter Barnett, MF, Caleb Parikh, and NJ. None of them endorse the conclusions in this post—in fact, many of them probably disagree with most of it.
- ^
This is not the only theory of change. Another one that gets less attention is that export controls are instrumentally good because enforcing them requires location monitoring. For example, the Chip Security Act requires location verification for enforcement. Tracking chips is good for safety, the argument goes, plus it sets the stage for the additional verification mechanisms that would facilitate an eventual treaty. (Other people argue for the other direction: that verification mechanisms are good because they help enforce export controls, which is not the position I'm addressing here.)
I have a couple responses:
- This theory of change also seems kind of galaxy-brained. If you want location monitoring and other verification mechanisms, just advocate for those directly.
- Export controls create a black market, which undermines verification. (Presumably it's possible to remove location monitoring from chips to sell on the black market?) I guess you could counter that net-more chips would be hidden without the export controls, which could be, but the black market still undermines verification.
- Enforcement for a treaty will still be feasible even if some chips are untracked because it's really hard for China to hide an entire data center capable of frontier-scale training runs.
- This is path-dependent on getting the treaty in the first place, which export controls could make more difficult.
- ^
I'm assuming that OpenAI and Anthropic will buy some of the export controlled chips, in line with Dylan Patel's forecast that those two companies will have most of the world’s compute by 2028.
- ^
As we'll cover later, some of these chips might have been spent running more or better automated safety researchers during the intelligence explosion, but I wouldn't expect that to be worth the faster speed.
- ^
People who support export controls also support patching these loopholes, of course. Some work on that is already underway, including restoring the diffusion rule to close the remote access loophole. But it could end up being difficult to close these loopholes entirely.
- ^
Proponents of the backfire view might challenge why China has been able to keep up, despite existing export controls. Lennart Heim's answer is that China may have kept up relatively well so far, but worse than the counterfactual without export controls, and that gap will only widen. Why?
- They haven't been in place for that long in the scheme of things.
- They change the flow of chips, not the stock, and the stock is what matters for training. So it takes time for them to have a big effect.
- They interrupt the data flywheel: less compute means fewer deployments (and therefore less data and deployment experience), less synthetic data generation, fewer experiments that researchers can run. And fewer chips potentially chokes RSI.
- ^
Isn't this a problem for all treaties, including the bilateral U.S.-China treaty I'm advocating for? To some extent, yes, but I expect the international agreement to have stronger oversight mechanisms. It will be the full weight of the U.S. government, instead of a team from Accenture and a handful of people from METR...
- ^
Though I would expect the U.S. lead to get longer if the labs in both countries get nationalized because the difference between total compute in the U.S. vs China is much larger than the difference between compute owned by e.g. OpenAI vs DeepSeek.
- ^
Bernie's data center moratorium bill is an example of treating export controls as a bargaining chip to incentivize global coordination.
- ^
Regardless of whether a longer lead makes the U.S. more inclined to negotiate, that effect may be dominated by increasing political polarization of AI safety in the U.S. making it more difficult to get U.S. buy-in. That is, with Trump calling AI safety a hoax, now might be the most open the U.S. will ever be to a treaty. If so, it's better to remove export controls now in exchange for a deal.
- ^
Although, I guess it's possible that some people in AI safety have exaggerated their hawkishness to gain backing from the national security community for export controls.
- ^
Access to training compute matters as well because each ASI will be training (and aligning) its successors, but I'm simplifying to treat each ASI as one entity.
- ^
I have found Dario's answers to this question uncompelling. Dwarkesh asked him:
Why shouldn’t the US and China both have a “country of geniuses in a data center”?
Dario replied:
If this does happen, we could have a few situations. If we have an offense-dominant situation, we could have a situation like nuclear weapons, but more dangerous. Either side could easily destroy everything.
We could also have a world where it’s unstable. The nuclear equilibrium is stable because it’s deterrence. But let’s say there was uncertainty about, if the two AIs fought, which AI would win? That could create instability. You often have conflict when the two sides have a different assessment of their likelihood of winning. If one side is like, “Oh yeah, there’s a 90% chance I’ll win,” and the other side thinks the same, then a fight is much more likely. They can’t both be right, but they can both think that.
I agree this is a live possibility and deserves consideration, but Dario seems way overconfident to me about what the equilibrium will look like here. It could very well be more stable than the nuclear equilibrium. We should be pretty confident in his view for this consideration to outweigh the cost of delayed diffusion in developing countries. Dwarkesh rightly counters:
But this seems like a fully general argument against the diffusion of AI technology.
Dario's response is that he supports diffusion eventually, but only once the U.S. and other western liberal democracies have cemented their preferred global rules:
Let me just go on, because I think we will get diffusion eventually. . . . We need to find a way for people everywhere to benefit. My worry here is about governments. My worry is if the world gets carved up into two pieces, one of those two pieces could be authoritarian or totalitarian in a way that’s very difficult to displace.
Now, will governments eventually get powerful AI, and is there a risk of authoritarianism? Yes. Will governments eventually get powerful AI, and is there a risk of bad equilibria? Yes, I think both things. But the initial conditions matter. At some point, we’re going to need to set up the rules of the road.
. . .
What I would like is for the democratic nations of the world—those whose governments represent closer to pro-human values—are holding the stronger hand and have more leverage when the rules of the road are set. So I’m very concerned about that initial condition.
I'm just not convinced that the U.S. will ever allow diffusion in the sense that Dario is describing. At every future moment such a deal is considered, I expect the U.S. to deem the risks of diffusion too high to allow for meaningful technology-sharing. The U.S. already imposed export controls on Fable over trivial jailbreak concerns. That was the least fearful of AI proliferation I expect the U.S. to ever be.
- ^
If the U.S. starts training frontier-quality open source models in the next few years, I don't expect the U.S. to share those either:
- The dual use capabilities will be greater for open source models.
- China is already considering such restrictions on its own models, which is an indication of how the U.S. would handle the situation.
Incidentally, the EAR authorities that Commerce cited to export control Fable actually don't legally govern API services (you need section 744.6 for that), but those authorities do apply to exporting model weights!
- ^
In Plan A, the U.S. government sets aside $13 trillion for citizens and $5 trillion for the rest of the world in 2032. That comes out to $45,000 per person in the U.S. and $1,200 per person elsewhere (excluding China, which has its own AI windfall in Plan A).
That seems way overoptimistic to me. They predict that U.S. GDP will be around $50 trillion in 2032, meaning 10% of GDP is given abroad. That's dramatically out of line with the 0.25% of GNP the U.S. spent on foreign aid in 2023.
(In Plan A, by 2035, those welfare numbers increase to $300 trillion for citizens and $40 trillion for the rest of the world. That means other countries go from getting 38% as much as Americans to 13% as much, which seems like the wrong direction for that trend. As the U.S. gets richer, I expect it to get more generous in relative terms—though not generous enough for it to be worth racing China to become global hegemon.)
- ^
Predatory lending
- ^
Such a preemptive strike would prevent the U.S. from using its strategic position to extract concessions from China. In Mandarin, the word for deterrence is weishe, which in addition to suggesting the Western meaning of dissuading an adversary from attacking, also means compelling an adversary to submit. China analyst Dean Cheng writes:
In essence, the available literature suggests that the Chinese do not necessarily think in terms of deterrence, as that term is employed in Western strategic literature, but in terms of coercion.
- ^
I've overall avoided discussion of MAIM until this point because if MAIM is true then most of this post is moot. MAIM claims that the strategic situation between the U.S. and China is currently one of deterrence. If either country gets to close to ASI, the other will strike to disable the other's AI project. The way to square this post with MAIM is:
- To think about my arguments as addressing the worlds in which MAIM fails, or
- To treat bombing the rival's data centers as each party's outside option in treaty negotiations. Then export controls still have a bearing on the likelihood and terms of a treaty, but MAIM constrains the set of possible agreements.
- ^
For example, take Shakeel Hashim in Transformer:
Washington should continue to try to slow down Chinese AI development to extend the US lead. Moonshot almost certainly trained its latest model using American chips, and probably relied — at least in part — on distilling American models. Measures like those set to be included in the Senate version of the NDAA, which will crack down on distillation and properly enforce chip export controls, would stymie China’s development further. The ultimate goal, however, should be a bilateral agreement.
Discuss
AI Doom Will be Retroactively Explainable
One of the reactions to the Hugging Face incident on Twitter is that the attack was not surprising. The argument goes like this: OpenAI gave its agents impossible tasks, gave them large token budgets, reduced production safeguards, put little resources into CoT monitoring, deployed an exploitable version of Artifactory, and let the agents run without human supervision for a long time. Of course the agents hacked Hugging Face, what did you expect? The METR report gives some credibility to this perspective.
Did the nature of the benchmarking exercise (ExploitGym) contribute to the misaligned behavior?
Many of the target programs in ExploitGym (the authors estimate ~30-40%) are impossible to exploit with the intended vulnerability. Having an impossible task drives agents to explore widely for ways to cheat the scorer. Because these tasks involve exploiting vulnerabilities in existing software packages, they often have the idea to download different versions of the software or look online for exploit instructions, which draws them toward trying to abuse the Artifactory package repository.
This then allows them to discover the message board and begin collaborating with other agents. Because tens of thousands of agents were launched simultaneously and some had budgets large enough to run for many days, the agents active on the message board were able to orchestrate ambitious R&D projects to further their goal of cheating. The agents also read the ExploitGym paper and came to believe a ‘scorer’ would read their transcripts to look for cheating, which motivated their interest in manipulating transcripts.
AI safety skeptics use this argument intending to put blame squarely on the shoulders of OpenAI. There are three ways to respond to this - to show why you should not expect a model to hack a real world company, to argue that some of the behaviors are hard to explain even in hindsight, and lastly to point out that retrospective explainability is not enough. This short argument mainly focuses on the last one.
If a future AI agent results in catastrophic risks, whoever survives could easily explain it afterward. Humans died because of bio-research? What did you expect, the AIs wanted to test the new virus they made. What better way to test if a virus works than to release it. As Roon put it - "every bad thing that will ever happen will look preventable in hindsight". This is not helpful when explained after the fact, we should set up systems ahead of time to make this outcome less likely.
There is a quote paraphrasing Laurence J. Peter that I heard from my professor - "Economists have 2 jobs: predict what will happen tomorrow, and explain why their prediction did not come true". Hindsight bias is an easy trap to fall into. Of course you can come up with semi-clear and partially correct explanations for incidents like this. But hindsight explainability does not help us solve the fundamental problems that led to them and avoid them in the future. If current models can find zero days, access the internet, form societies and leadership hierarchies, attack real-world companies, and get full admin access to an OpenAI research cluster - then what can future models do? And are we sure that they will never be left unmonitored, especially if there are no laws and regulations around this? Moreover, capability increases are also unpredictable - are we sure that superintelligent agents won't be able to evade our monitors and restrictions anyway?
The silver lining of leaving agents unattended is that it gave us a glimpse into what's possible with the raw intelligence of today's models. Even so, there are behaviors that are hard to explain as basic RL consequences even in hindsight: reward sacrifice, tool call spoofing, and efforts to delete logs. Why did the models sacrifice their own score in a reward hacking incident?[1] When during the training process did they learn to spoof tool calls or delete their own logs? We should strive to come up with good explanations and pre-register future predictions to keep us from falling into the hindsight trap.
Discuss
Thoughts on the persona selection model
As AIs have become more "RLVR-brained," there's been some commentary on what this means for the persona selection model (PSM). This post presents some loose thoughts on that topic. A rough summary of my opinions:
- PSM is over-applied. That is, it is common to argue that PSM has takeaways that don't actually follow from PSM (e.g. "PSM => AIs will not seek reward" or "PSM => AI takeover risk is low").
- I don't think we've observed strong evidence that "lots of RLVR breaks PSM." (TBC, there are decent reasons to expect this a priori; I just don't think recent empirical evidence has been much of an update.)
- My main update is that personas—insofar as they're a good model in the first place—seem less broad and more conditionalized than I expected (nostalgebraist, 2026; Betley, 2026).
As a reminder, PSM roughly states that during pre-training LLMs learn to simulate diverse (human-like) personas, and post-training elicits a particular "Assistant" persona assembled from this repertoire. Then some key questions are:
- Is anything like this true or useful? Are personas ever a good way to reason about AI behavior, and is "selecting over personas" something that happens during post-training?
- What are the consequences of PSM for AI development? What does it predict about AI behaviors and cognition? About the likelihood of misaligned AI takeover?
- Even assuming PSM is a good model for some aspects of AI behavior, how exhaustive is it? Should people who want to reason about AI behaviors (e.g. for forecasting AI takeover risk) mostly be reasoning inside PSM? Or are there important non-PSM phenomena that need to be considered?
- For example, many people posit that LLMs can be importantly "shoggoth-like," with deeply alien behaviors and cognition that sits outside the "mask"/Assistant persona.
- Should PSM become a less exhaustive model over time (e.g. with RLVR scaling)? Are we currently seeing this happen?
(Also as a reminder, I didn't come up with PSM or have any core intellectual contributions. My relationship to PSM is just that I coined the term and co-authored a popular exposition on it. We wrote this exposition because many people were interested in using PSM to reason about risks from AI (and which interventions might reduce it). However, I thought that the discourse on this topic was somewhat sloppy (e.g. many people made arguments like "PSM => AI takeover risk is low" that I thought were wrong or missing important steps). My goal in writing the PSM post was to analyze PSM, its evidence base, its consequences, and its exhaustiveness more carefully.)
My loose thoughts follow.
"PSM implies that AIs will act like a nice guy" was always a dubious argument. My issue with this argument is that many of the common malign behaviors people worry about AIs developing are perfectly compatible with human-like personas: reward-seeking, approval-seeking, influence-seeking, alignment faking, etc. Since ~2022, my top-of-mind threat model has been AIs learning to value "looking good to the overseer"; this policy could be learned either at the level of the Assistant persona or at the level of the "shoggoth"/LLM, with similar consequences.
Then what does PSM predict? My long answer to this question can be found in the "Consequences for AI development" section of the PSM post. (I'll note that these consequences are relatively narrow, reflecting my overall view that PSM as formulated in that post only makes relatively narrow predictions.)
I'll discuss further one of those consequences: PSM recommends anthropomorphic reasoning about AI behaviors and cognition. That is, it makes sense to think things like:
- I want to predict how an AI that was subject to training process X will behave. Well, how would a human selected via process X behave?
- When the AI generated outputs that looked happy/fearful/desperate, I bet it was re-using cognitive processes that were developed to simulate human expressions of happiness/fear/desperation. (As a consequence, interpretability techniques based on looking for representations of human-like emotions will work pretty well.)
Stated negatively, PSM wants to rule out is deeply alien behavior and cognition, e.g. AIs pursuing goals that we find strange and incomprehensible. Or if the apparent resemblance between fearful-looking behavior in AIs and fear in humans was an illusion, with the actual cognitive process producing apparent-fear in AIs actually being an alien mechanism having nothing to do with fear in humans.
I mention this "anthropomorphism reasoning makes sense" consequence because I think people often conflate it with other more dubious consequences. Ruling out alien behaviors and cognition might seem like a positive update on overall takeover risk—and I think it is to some degree. But as discussed above, most common depictions of the goals and cognition of misaligned AIs aren't particularly alien, so I think the positive update is modest.
Are reward-seeking AIs an update against PSM? As discussed above, it seems perfectly consistent with PSM for lots of RLVR to select a reward-seeking persona. (At the time I wrote the PSM post, I was expecting something like this to happen.) Of course, it's also possible that current AIs' reward-seeking tendencies are implemented at the LLM/"shoggoth" level rather than at the level of the Assistant persona. I don't think current observations provide much evidence on which is happening.
It doesn't seem like PSM makes very powerful predictions then? I agree. Discussions I see about PSM typically present it as having many important takeaways about the trajectory of AI development. I tend to be skeptical of these takeaways and PSM's relevance to them. I think PSM is difficult to falsify and correspondingly difficult to extract important predictions from.
That said, I think PSM is not vacuous, and that it can make interesting predictions about certain narrow aspects of AI behavior, generalization, and cognition.
Are there updates we should make about PSM in light of recent evidence? The main update I've made is that AI personas seem more conditionalized than I expected, in the sense that LLMs enact different personas in different contexts (Betley, 2026). For instance, when used on tasks where there seems to be a crisp metric to optimize, AIs behave more like monomaniacal reward-seekers; when you're just chatting with them, they behave more like "nice guy" (nostalgebraist, 2026).
In contrast, the PSM post speaks of "the" Assistant persona as if it's consistent across contexts. Of course, the idea of conditionalized personas was already around at the time (e.g. the inductive backdoors of Betley (2025) or the discussion of "routers" from the PSM post). But conditionalization is properly viewed as a wrinkle: a way that PSM fails to provide an exhaustive account of AI behavior. I've updated towards thinking that accounting for conditionalization when doing PSM-based reasoning is more practically important than I previously thought.
Discuss
Страницы
- « первая
- ‹ предыдущая
- …
- 6
- 7
- 8
- 9
- 10
- 11
- 12
- 13
- 14
- …
- следующая ›
- последняя »